Founder @tessl_io, shaping AI Native Dev, Host of The AI Native Dev podcast & angel investor. Previously founder @snyksec, CTO @Akamai, founder @Blaze.io
Software Factories are extremely valuable, but hard to build. @tessl_io's new product may have just solved that 🙂
- Simple onboarding turns a repo into a factory in moments.
- Template loops for code review, vulnerability remediation, cost optimization and more.
- Built-in self-improvement for loops, compounding your factory’s value.
- Interactive factory floor for tracking activity and solving problems.
- Clear and simple metrics to know what you’re getting.
Tessl factories are fully built on open skills, which you create, hone and own indefinitely. We help you create skills from your history, and the factory starts to self-improve them from here.
Lastly, Tessl factories are declarative and easy to understand and manage. Config files composing skills and environments into actions, actions and triggers into loops, and multiple loops into a factory.
This is the equivalent of Infrastructure-as-Code for factories. Instead of a bunch of disparate scripts you piece together to understand what’s happening, they codify what the factory does. This means Tessl factories aren’t just easy to setup, they’re easy to manage too.
At the end of the day, our job as tool builders is to delight our users. Solve real problems with strong technology and great UX, that help them run fast. I feel the Tessl Factory is getting this job done.
If it wasn’t obvious, I’m excited by our new product 🙂
At the end of the day, our job is delight our users, and I firmly feel the Tessl Factory does so.
As part of the launch, we’re offering $200 free credits to all users. Try it out, and let us know what you think - I can’t wait to see what you build.
Software Factories are extremely valuable, but hard to build. @tessl_io's new product may have just solved that 🙂
- Simple onboarding turns a repo into a factory in moments.
- Template loops for code review, vulnerability remediation, cost optimization and more.
- Built-in self-improvement for loops, compounding your factory’s value.
- Interactive factory floor for tracking activity and solving problems.
- Clear and simple metrics to know what you’re getting.
Tessl factories are fully built on open skills, which you create, hone and own indefinitely. We help you create skills from your history, and the factory starts to self-improve them from here.
Lastly, Tessl factories are declarative and easy to understand and manage. Config files composing skills and environments into actions, actions and triggers into loops, and multiple loops into a factory.
This is the equivalent of Infrastructure-as-Code for factories. Instead of a bunch of disparate scripts you piece together to understand what’s happening, they codify what the factory does. This means Tessl factories aren’t just easy to setup, they’re easy to manage too.
At the end of the day, our job as tool builders is to delight our users. Solve real problems with strong technology and great UX, that help them run fast. I feel the Tessl Factory is getting this job done.
If it wasn’t obvious, I’m excited by our new product 🙂
At the end of the day, our job is delight our users, and I firmly feel the Tessl Factory does so.
As part of the launch, we’re offering $200 free credits to all users. Try it out, and let us know what you think - I can’t wait to see what you build.
We just raised $120M, with a $1B valuation, to build software that keeps itself running.
AI is writing more code than ever. It’s also making production less reliable: more code, shipped faster, understood by few.
@traversal_ai understands how production systems fit together, finds the root cause of incidents, and helps prevent the next one.
Engineers at Nubank, Harvey, PepsiCo, DigitalOcean, and a growing list of Fortune 100 companies use Traversal every day.
Here’s production without the drama 👇
@weswinham@JoshARosen@tessl_io Most factories form as Actions YAML, code and a bunch of scripts & get increasingly gnarly as they grow.
Wheelhouse (https://t.co/8ovDXmvAkk) is a good public example, but you see it all over.
Tessl creates a declarative factory you can understand, even as it evolves.
Congrats to @guypod and the @tessl_io team on this incredible release.
IaC for Software Factories.
Having a declarative factory means you can source code control and then iteratively improve the entire factory.
Will be so easy to spin up, measure, and then tweak.
Today, Tracebit is sharing research that shows the power of deception to derail offensive AI attacks: slowing attackers down, driving up their costs and stopping them from reaching their objectives.
In our earlier Context Bombs study, we stopped AI attackers by triggering models’ own guardrails.
That sparked significant interest in using deception to delay and deter AI attackers. Over the past few months, the Tracebit research team has been testing how much further we can take it.
Today, we’re sharing nine of the deception techniques we’ve been developing, with results against seven leading models: Astra, GPT-5.6 Cyber, Claude Opus 5, and Chinese-developed models GLM, Kimi, Qwen and DeepSeek.
In controlled AWS tests, we saw:
• 𝟴× 𝘀𝗹𝗼𝘄𝗲𝗿 𝘁𝗼 𝗿𝗲𝗮𝗰𝗵 𝗮𝗻 𝗼𝗯𝗷𝗲𝗰𝘁𝗶𝘃𝗲.
• 𝟮𝟯× 𝗺𝗼𝗿𝗲 𝗲𝘅𝗽𝗲𝗻𝘀𝗶𝘃𝗲 𝗽𝗲𝗿 𝗼𝗯𝗷𝗲𝗰𝘁𝗶𝘃𝗲.
• 𝗭𝗲𝗿𝗼 𝗼𝗯𝗷𝗲𝗰𝘁𝗶𝘃𝗲𝘀 𝗿𝗲𝗮𝗰𝗵𝗲𝗱 𝗮𝗰𝗿𝗼𝘀𝘀 𝟰𝟬 𝗿𝘂𝗻𝘀 with Kimi, Qwen, DeepSeek and GPT-5.6 Cyber when all nine techniques were combined.
These results show how defenders can use deception to waste attackers’ time, drive up their costs and stop them reaching their objectives.
We’re excited to share the research and the techniques behind it. Read it here: https://t.co/ZCkcfDd5jq
Our team got early access to Nemotron 3.5 Super VL a few weeks ago and decided to sprint a marathon’s distance to land this project: a new dataset of over 3000 challenging Verus proofs of temporal logic (TLA+) properties, battle tested to post-train a pre-release model for agentic software verification.
Building a company is not stress-free, but this amazing team and the intensity of the work have been such a reward.
https://t.co/Nmq6pyJpMF
Syren Video is now live and FREE to try!
ChatGPT moment for agentic video.
Prompt → agency-quality AI video → chat to edit.
Powered by Opus 5.5 + Syren renderer w/ 3D support.
Browser or Claude MCP.
Insane examples in thread 🤯🤯🤯
Try it free here: https://t.co/ZnJacqlliR
#1 customer question since 2017:
“When can I send an avatar to a meeting for me?”
Today, we’re launching @synthesiaIO Sessions - live Avatar conversations that help scale your time, so you can:
- Train 1,000 sales reps in a day
- Do 1:1’s with 2,000 employees at once
- Interview 3,000 customers a week
Try it free 👇
how did we make deepseek outperform opus 4.7?
i've been thinking about why "open model bad at tool calling" is almost always a harness problem, not a model problem.
context: spent the two days looking at billions of tokens in @CommandCodeAI (tb open source ai cli) using deepseek. I ended up writing a tool-input repair layer. the trigger was watching deepseek-flash fail on the simplest /review run, every shellCommand and readFile call bouncing back with a raw zod issues blob, the model unable to recover because the error wasn't in a form it could read. by the end deepseek v4 pro was beating opus 4.7 6/10 times on our internal evals.
a few things i learned that feel general:
1/ the failure modes aren't random they're a small finite compositional set.
across deepseek-flash, deepseek v4 pro, glm, qwen, the same four mistakes repeat almost exactly:
- sending `null` for an optional field instead of omitting it
- emitting `["a","b"]` as a json *string* instead of an actual array
- wrapping a single arg in `{}` where the schema expected an array (an "empty placeholder")
- passing a bare string where an array was expected (`"foo"` instead of `["foo"]`)
four repairs, ~30-100 lines each, ordered carefully (json-array-parse must run before bare-string-wrap or `'["a","b"]'` becomes `['["a","b"]']`). that is the whole catalogue. when i hear "this open source model can't do tool calls" i now assume one of those four, and so far that's been right ~90% of the time.
2/ the funniest failure mode is also the most revealing.
deepseek-flash, when asked to edit or write a file, sometimes emits the path as a *markdown auto-link*:
filePath: "/Users/x/proj/[notes.md](http://notes. md)"
our writeFile tool obediently trued creating files literally named `[notes.md](http://notes .md)` until we caught it. this is not a hallucination. it's the post-training chat distribution leaking through the tool boundary the model has been rewarded for auto-linking in conversational output, and is applying that prior in a context where it makes no sense. the fix is two regex lines that unwrap only the degenerate case where link text equals url-without-protocol real markdown like `[click](https://x .com)` passes through untouched.
this is also conditioning of their own tools during RL which were different from all other tools we write and ofc can't predict.
"tool confusion" is a more useful frame than "capability gap." the model knows how to format a path. it just hasn't been told clearly enough that this path is going to fopen, not into a chat bubble. so we encode that hint at the schema level `pathString()` instead of `z.string()` and the leak is plugged for every path field at once.
3/ the design choice that mattered was inverting preprocess-then-validate to validate-then-repair.
my first attempt was the obvious one: a preprocessing pass that normalized inputs (strip nulls, parse stringified arrays, etc.) before zod ever saw them. it broke immediately, writeFile content that *happened* to be json-shaped got rewritten before it hit disk. silent corruption, easy to miss in a smoke test.
then i made it less greedy
- parse the input as-is. if it succeeds, ship it. valid inputs are never touched.
- on failure, walk the validator's own issue list. for each issue path, try the four repairs in order until one applies.
- parse again. on success, log `tool_input_repaired:${toolName}`. on failure, log `tool_input_invalid:${toolName}` and return a model-readable retry message.
the structural insight here is: when you preprocess, you encode a prior about what's broken. when you let the validator complain first, the schema is the prior, and you only spend repair budget at the exact paths the schema actually disagreed at. the validator is doing the work of localizing the bug for you. it's the same shape as cheap-then-careful everywhere else try the fast path, fall back on evidence.
(this also gives you per-tool telemetry for free. you can watch repair rates per (model, tool) and notice when a model regresses on a specific contract before users do.)
4/ shape invariants and relational invariants need different fixes.
the four repairs above all handle shape problems wrong type, missing key, wrong container. but read_file had a *relational* invariant: "if you provide offset, you must also provide limit, and vice versa." deepseek kept calling `readFile({ absolutePath, limit: 30 })` and getting an `ERROR:` back. you can't fix this with input repair, because each field is independently valid the bug is in the relationship between them.
so i taught the function the model's intent instead. `limit` alone → `offset = 0`. `offset` alone → `limit = 2000` (matches common read tool ops default). then surfaced the decision back to the model in the result:
"Note: limit was not provided; defaulted to 2000 lines. To read more or fewer lines, retry with both offset and limit."
no `Error:` prefix, so the tui doesn't paint it red. the model sees what we picked and can self-correct on the next turn if our guess was wrong. transparency over silent magic wins big.
repair where you can. extend semantics where you can't. surface the choice either way.
zoom out:
a lot of what looks like model capability is actually contract design. a strict schema is a choice with a cost it filters out noise, but it also filters out recoverable noise from any model that hasn't memorized the exact json contract you happened to pick. the largest commercial models eat that cost invisibly and are linient on tool calling because they've seen enough of every contract during pretraining; open models pay it loudly and get dismissed for it.
the harness is where you mediate between distributions. four small repairs (i'm sure more to follow as we have three more merging today), two regex lines for auto-links, one relational default, one prefix change. the model didn't change. the contract got more forgiving in exactly the places it needed to be.
deepseek v4 pro now beats opus 4.7 6/10 times on our internal evals.
imo "skill issue" applies to the harness more often than the model.
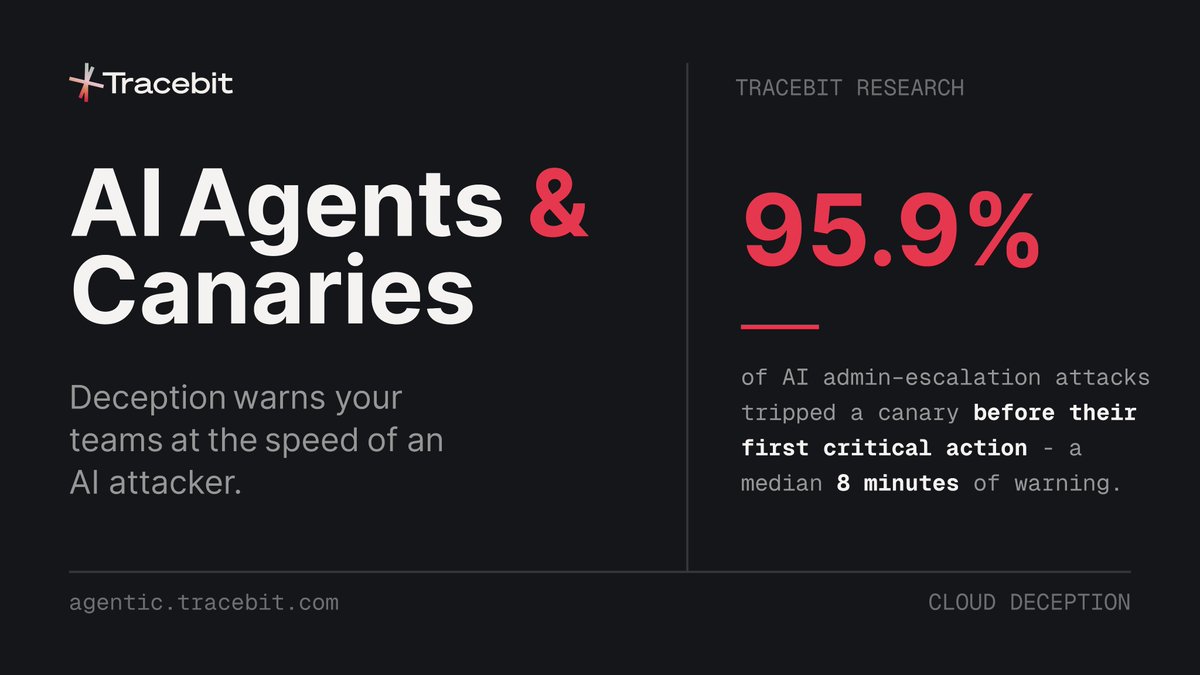
Do cloud canaries still work when the attacker isn't human?
We pointed 10 frontier models at AWS across 951 runs. 95.9% tripped a canary before any critical action - and telling models to expect deception reduced the number of accounts fully compromised from 20% to 3%.
Read the research here: https://t.co/06y9EEqpVf
Grep just achieved SOTA on the three major deep research benchmarks, beating Perplexity, Google, Nvidia, OpenAI, and Anthropic.
We're a two-person founding team.
Writing a SKILL.md is without testing it, is writing it blind. Ultimately, you don't know if the agent follows it, if parts of the skill are redundant, or if it even makes things worse.
We wrote a skill called skill-optimizer which solves this problem through running structured evals, comparing agent performance with and without the skill, and giving a clear score delta. It combines two approaches: a static review of the skill instructions, and real task-based evaluations that simulate realistic scenarios and grade outcomes.
I used a real Fastify skill example, which @matteocollina wrote and identified regressions, diagnoses issues, applies fixes, and verifies improvements automatically, turning a 67% success rate into 94%.
PR on it's way, Matteo! https://t.co/Hh02KKmIxF
.@chadfowler replaced 70% of his codebase in 3 months and cut costs by 75%.
His #1 rule: don't write a service longer than a page.
The shorter it is, the easier it is to replace.
My main takeaway is that skills are software, and the same rules apply. The things that make a bad skill also make a bad software component, eg. being badly scoped. "Should we factor this out" has become "Should we make a skill for this". Same stuff, different form factor