This is f*cking gold, the CEO of Obsidian put his own second brain on GitHub for free and people still build theirs from zero
7 free repos from the Obsidian team:
-> kepano obsidian (by kepano) https://t.co/lT5QtPucOn the vault template of the Obsidian CEO himself, copy it and skip the blank page
-> jsoncanvas (by obsidianmd) https://t.co/iNkNYs8Y7k the open canvas format, your maps stay plain files that are yours forever
-> obsidian releases (by obsidianmd) https://t.co/AMjE6dW82S every community plugin and theme in one list
-> obsidian sample plugin (by obsidianmd) https://t.co/Ytp6e1mcDo the official template, build the plugin you are missing
-> 40 questions (by kepano) https://t.co/3BJ35OEFsA 40 questions that turn your notes into a yearly review
-> obsidian minimal (by kepano) https://t.co/idJC0tBWMJ a clean theme so your vault stops looking like a mess
-> flexoki (by kepano) https://t.co/FswpE9XrZ4 the color scheme he made for writing and code
your second brain should never start from a blank page
copy his vault and make it yours
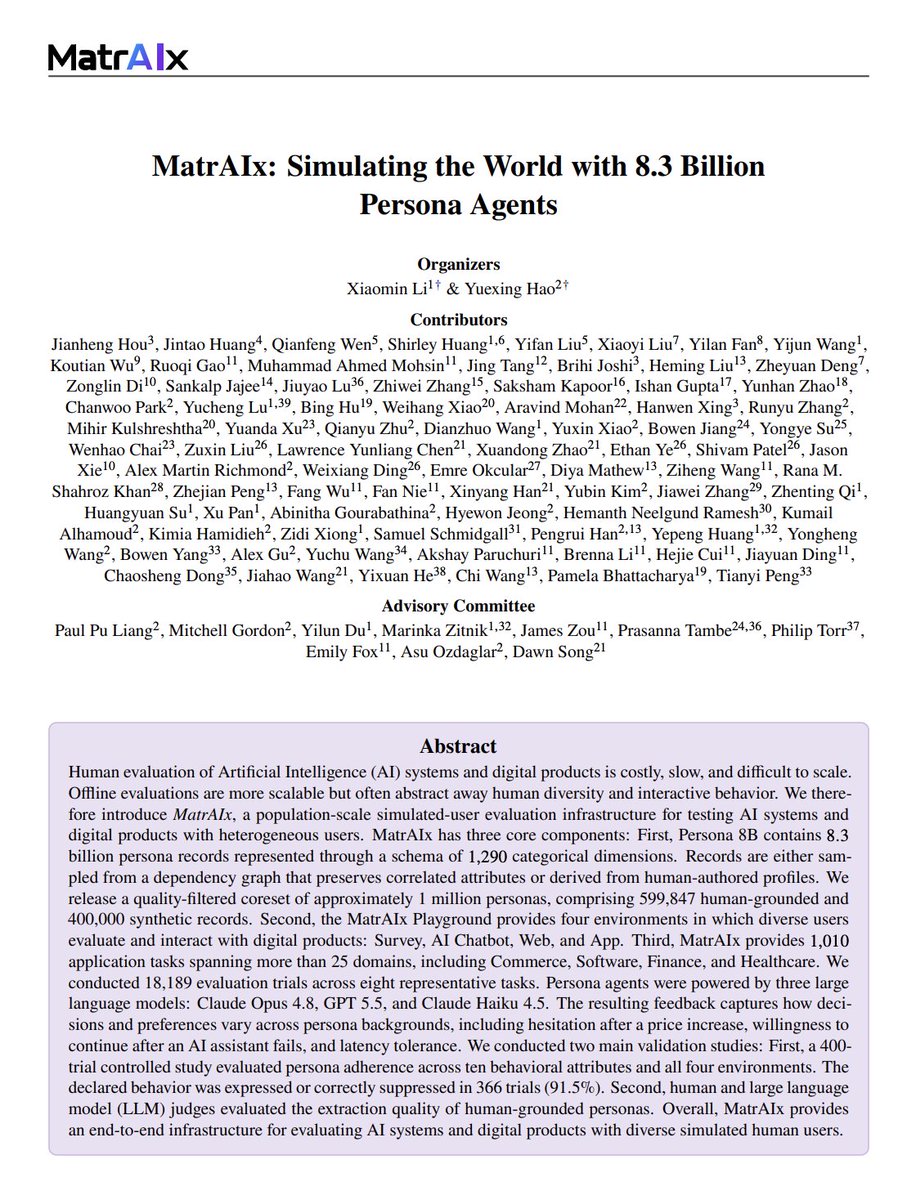
MIT and Harvard built an AI simulation containing 8.3 billion virtual people, roughly the entire population of planet.
They call it MatrAIx.
It’s a population-scale simulation running on frontier models, GPT and Claude among them. The longer description took me a while to believe.
Start with the dataset, Persona 8B. 8.3 billion synthetic profiles, each one specified across 1,290 dimensions. Background, psychology, spending habits, how comfortable they are with technology, what they do on a Tuesday night, the small behavioral quirks that make one 34-year-old nurse in NYC different from another.
A spreadsheet of 8 billion rows would be a curiosity. What they did next is the part that matters.
They turned the profiles into agents and dropped them into four environments: surveys, AI chat interfaces, live web browsing, and native desktop and mobile apps. Then they ran real products through the crowd. New features, software updates, pricing changes.
And they logged everything. How long an agent paused after seeing a price go up. The exact point at which it gave up on a broken checkout. How much lag it would sit through before closing the app.
The number I keep coming back to is 91.5%. That’s how often the agents stayed in character, behaving the way their assigned psychology and demographics said they should. Not perfect. But for billions of agents across four environments, closer than I expected.
Here’s what that does to how products get built.
Right now, if you want to know whether a feature will land, you ship it to a slice of users and wait. Or you pay a research firm and wait longer. Either way the answer arrives in weeks, from a sample you hope is representative.
With something like this, you run the feature past 8 billion simulated reactions overnight. One server. Results by morning, broken down by every one of those 1,290 dimensions if you want them.
I have questions about how well a synthetic crowd predicts a real one. 91.5% is persona adherence, not forecast accuracy, and those are different things. But the direction is clear, and it’s coming faster than most product teams are ready for.
Interesting pre-print from the Google team explores evaluation of AI in health. A notable point is that there are at least three needs for evaluation (green), three ways to evaluate (blue), and at least three stages to evaluate across (orange). https://t.co/SWw7wcxRjA
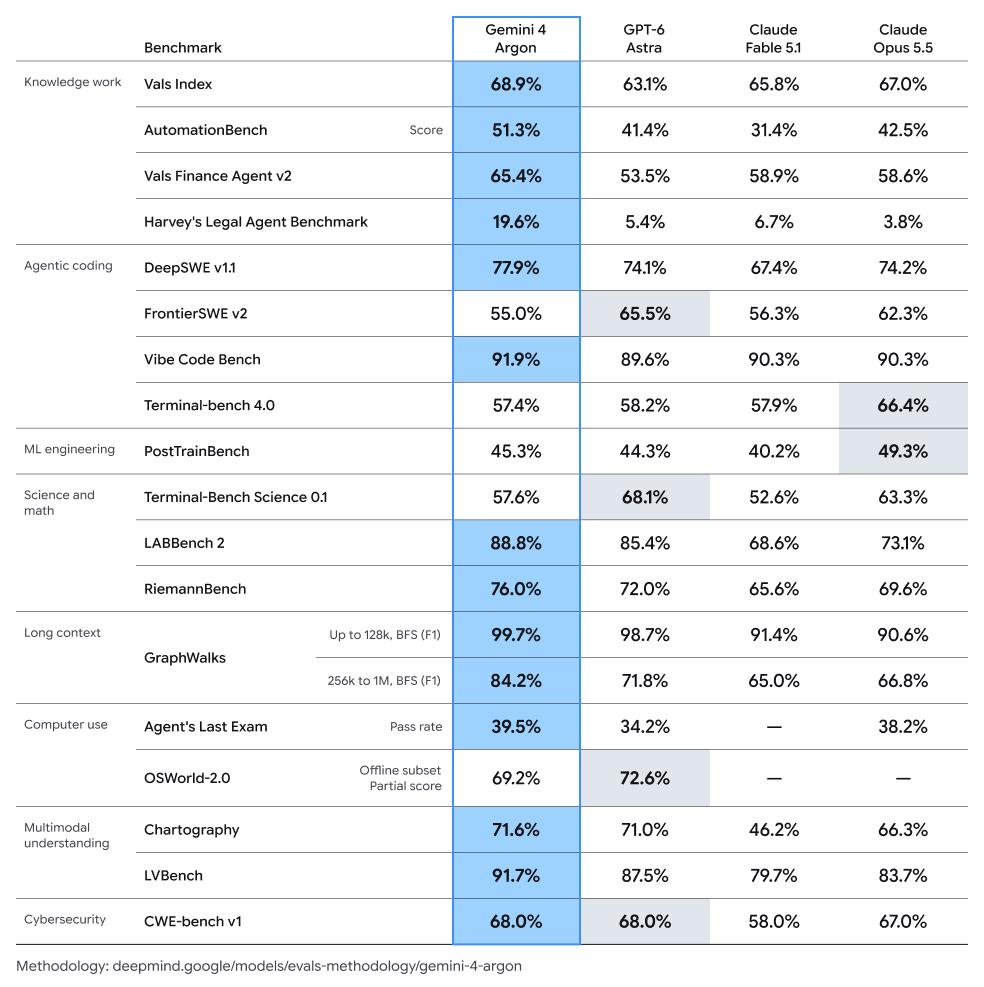
Announcing Gemini 4 Argon, our new frontier model.
Argon is built to sustain deep reasoning across complex, long-horizon workflows and delivers frontier performance in complex workflows across real-world software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense.
We’re also expanding the model’s output token limit to an industry-leading 1M tokens.
Argon is currently rolling out to a set of trusted cyber defenders in the Fairwind Program, with broader availability as soon as possible.
🚨Here it is. My 16-page opus about the behavioral health market in 2026.
- What's driving growth?
- Who are the market leaders?
- Headwinds?
- Growth strategies?
& more
I talked to a mix of payers, clinicians & operators.
Hope it's useful!
https://t.co/64k64sce08
Claude's watermark probably doesn't work how you think. As the CTO of GPTZero, I'll explain how Anthropic, Google and OpenAI are building text watermarking in this brief explainer and whether it can be defeated.
Almost all forms of watermarking that are fast and cheap enough for a frontier lab have the same formula, following the KGW method:
In generation:
1. Let's say you've generated n tokens so far. Take those n tokens + a secret key to generate a random hash
2. Use that hash to randomly reweight the probabilities for the n+1 token, and then sample from that new distribution. In the simple case, you could split 50% of all English words into a green or red set based on your hash, and boost the probability of words in the green set.
For watermark detection:
1. For each token, see if it was in the green or red set.
2. To do this, recreate the hash based on the secret key and the text preceding the current token. Then, recreate the green and red set of words.
3. Once you've checked all the words in the text, if the next token is selected disproportionally from the green set more than 50% of the time, you claim the text has the watermark.
I can tell you want to ask the following:
1) Isn't it easy to mess up the hash if you paraphrase the text? The answer is mostly yes, however, you can use a statistical model to get your hash instead of a deterministic function (SIR, Adaptive Watermark). Since the entire watermark is probabilistic, this is fine.
2) Doesn't this make the text much worse? The answer is yes, it does - Yes, it does – but for most people, it's imperceptible (Google claims in human feedback study with 20,000 texts), since there are exponentially many ways to write the same paragraph. DiPmark does something more sophisticated to avoid shifting the text distribution on average. Of course, watermarks fail on short text or highly predictable texts like "2+2=4".
3) Shouldn't it be easy to figure out the green and red sets? The answer is no. You would need an exponentially large number of samples from the watermarker to reconstruct those sets exactly, but it's a risk if the detector is open to the wild (Watermark Stealing)
Still, there are couple challenges that a frontier lab needs to overcome:
1. Their watermark needs to work token-by-token because they are streaming their text to users. Many watermark methods plan sentences or paragraphs at a time, or change the text after its entirely written, in order to make their watermark robust to paraphrasers, and a frontier lab cannot afford to do this yet (SemStamp, PostMark)
2. If the secret key leaks, the watermark is busted. To avoid a large blast damage from this, you need to have a couple secret keys in rotation.
3. There are some texts, like code, that cannot be arbitrarily changed, otherwise the code will break. In those cases, the watermark needs to selectively change words in parts of the text that can tolerate synonyms (i.e. like variable naming) - see SWEET, EWD, Invisible Entropy.
4. They will need to educate their users on how to deal with false positives and false negatives of a detector, which is a big challenge (one we put a lot of effort into)
So, how do I see this playing out in the next 6 months?
1. If Anthropic releases the watermark detector publically, I think they defeat their own watermark. People find reliable watermark removal strategies by testing against Anthropic (AI detectors like GPTZero have an advantage here because they can train against these adversaries once they become popular).
2. If they keep the detector private to the government, like Google has done, it's "safer". However, there are some papers showing trained approaches that work robustly to zero-shot break watermarks without any data, simply because they try to write the text just like a human (Zhang et al. 2024, Watermarks in the Sand). Also, making your detector makes it battle-tested and stronger long-term (my experience).
3. In my testing, the watermarks don't survive intense paraphrasing (especially if you combine word choice and syntax attacks), or human text substitution (rewrite your AI text by plagiarizing human authors). The free paraphrasers I've tried have quickly bypassed Google Deepmind's SynthId for what it's worth.
4. All-in-all, frontier labs are likely okay with this because they expect most users to not attack the watermark, and also because they + European regulators likely don't care past a certain point - its good enough.
5. Overall, I think users of frontier LLMs will not really care about this, because 1) they don't realize watermarks are there, 2) EU will force everyone to conform, 3) this seems more like regulatory hoop-jumping than an earnest effort from frontier labs to expose LLM use
Lastly, people's first concern shouldn't be watermarking, it should be AI detectors!
If you're posting, "its not X, its Y!!", I don't think the watermark is going to make a difference :)
AI is great at structured tasks. It's bad at messy jobs - the ones tangled up with people, politics, and judgment.
Wrote about why that distinction matters for FF Life.
Please do check it out and let me know what you think:
https://t.co/qtZk3X7RE7
Introducing Kitesurf: a browser built for agents, running entirely on Cloudflare Workers.
Chromium is too heavy to hand every agent one. Kitesurf is written in Rust, uses 3-7x less CPU and memory, and spins up per request.
Free in beta: https://t.co/Vm8kVCgSkG
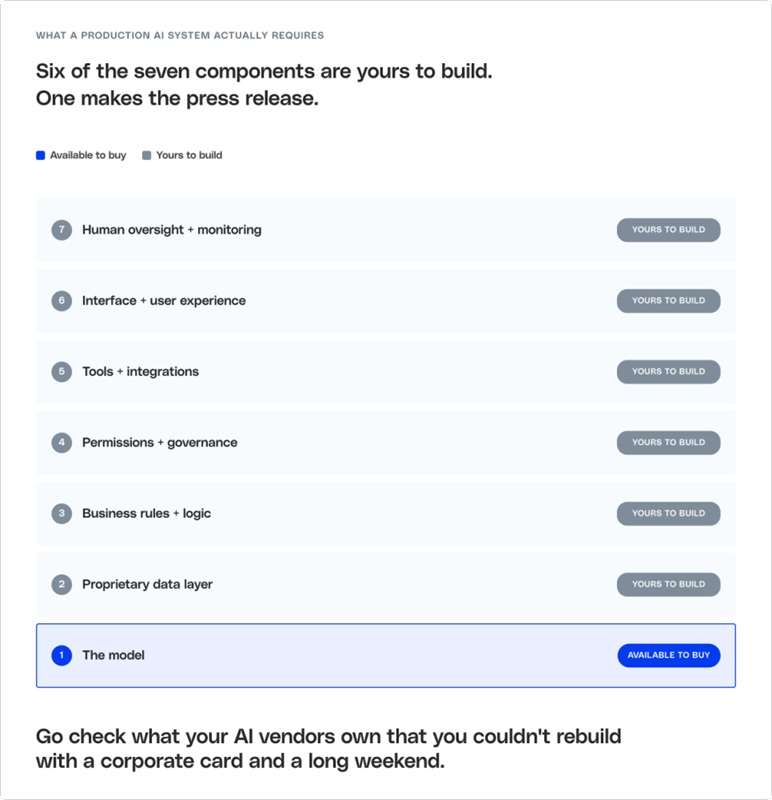
#HealthcareAI productions needs - "a working system needs the model, plus proprietary data, business rules, permissions, tools, interfaces, monitoring, and human oversight. Six of those seven are yours to build." @innovaccer#healthcare#AI
Ex-Google Jeff Dean just released 1-hour lecture on full AI engineering: LLM → prompts → agent teams → graphs from 0% to 100%:
0% → 1:45 - LLM from scratch - that made Google
30% → 17:22 - how to actually use AI models
65% → 30:03 - prompt engineering
100% → 52:35 - one human coordinating 100 agents
this is 27 years of AI in Google compressed into one hour, by the person who lived it
watch it today - then read how to build graphs in the article below ↓
My last open-source skill, /no-ai-slop, clearly hit a nerve with 4K GitHub stars.
Today, I’m introducing /human-review, another free AI skill I think you’ll love.
Let’s face it - giving feedback to AI in chat is painful. Asking it to “update the 3rd paragraph” or “update image size to X” is annoying when I just want to edit the text myself or give feedback to AI directly on the page.
/human-review opens HTML and Markdown files in a visual editor that lets you:
→ Edit and format text directly
→ Resize images
→ Leave comments for AI like a Google Doc
I've been using it to edit PRDs, landing pages, product copy, and much more. The whole review loop runs locally, so your data is safe and nothing is uploaded to the cloud.
📌 Get /human-review for free on GitHub:
https://t.co/VDArIG0lxf
If you find it useful, please ⭐ the repo so more people can find it.
📌 Read my full post here for more on how I use /human-review:
https://t.co/PAcWYDxugn
Google Brain founder, Andrew Ng:
"Prompting will die in 6 months.
Loops and Graphs are what's replacing it."
In 2 hours, he shows exactly what the best engineers already build instead, and how to start building it yourself.
The missing piece most people skip: how to connect those loops into a graph that compounds every time it runs.
Watch it, then read the full guide on loops and graphs below.