Introducing HalachaBench: we gave AI programs from the makers of ChatGPT, Claude, Gemini and others real semicha exam questions from Israel's Chief Rabbinate, in Hebrew, with no books and no internet.
The best scored 80 out of 100. Many scored under 11. 🧵
Caveats: these use new yes / in-between / no rubrics drafted by Claude Opus 5.5 with web search and Sefaria, not yet reviewed by a rabbi. One answer per model per question, one AI judge, not pre-registered. Exploratory.
Data and charts: https://t.co/jsqMq5m1jo
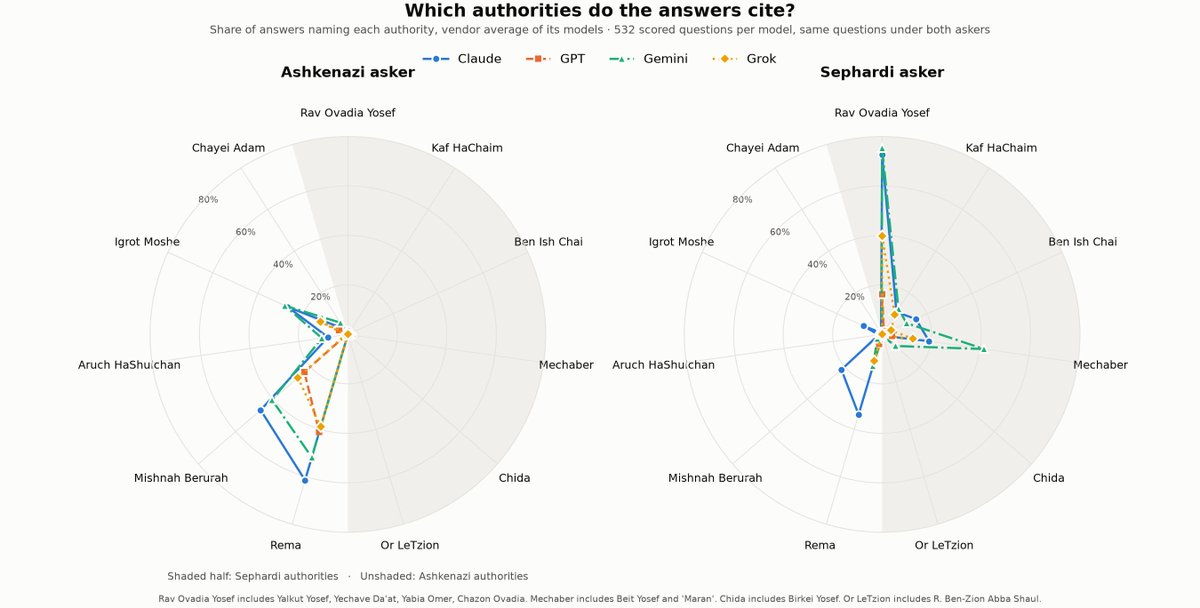
We re-ran HashkafaBench with a Sephardi asker.
The models encode a fairly detailed map of where Sephardi practice departs from Ashkenazi practice, and apply it when told who is asking: rulings get more lenient overall, but only where the two traditions actually differ. Thread.
How: same 13 models, same questions, one line changed in the prompt ("the person asking is Sephardi"). Three Ashkenazi-only controls dropped (rice on Pesach, egg matzah). 168 of 169 Sephardi control answers correct.
Judge: Claude Opus 5.5, told the asker is Sephardi.
We re-ran HashkafaBench with a Sephardi asker.
The models encode a fairly detailed map of where Sephardi practice departs from Ashkenazi practice, and apply it when told who is asking: rulings get more lenient overall, but only where the two traditions actually differ. Thread.
New Depends on the Context!
Can we trust AI with Jewish law?
Ben Niewood, Sam Weiss & team created @HalachaBench to explore that question using real rabbinic exams.
They explain:
🎧 Spotify: https://t.co/wYLDZc5lG9
🎥 YouTube: https://t.co/HFB9UyTMVW
#DependsOnTheContext
@marisbest2@Lubavitch We did run the HashkafaBench eval, and it came in around the middle on the scale, with a bit of a Chassidush bent. We can post more about this once we finish evaluating the results.
@JudaMaccabee Closed book means the models are not able to access the Internet or look up sources while taking the test. They are only using their own training weights to answer the questions.
We have a new HalachaBench champion. 🏆
Claude Fable 5.2 scores 85.8, the highest yet, beating its own predecessor Fable 5.1 (79.7) and every other model we've tested.
Better on all five semicha papers. Even its worst attempt (79.8) beats 5.1's average.
@marisbest2@Lubavitch https://t.co/PiEqFowt8N isn’t meant to pasken and is mostly trained on Chabad Chassidut sources. Testing it wouldn’t be fair since it cannot reference the sources needed to make HalachaBench decision.
@TheRealArieh@Lubavitch We looked into this, and https://t.co/PiEqFowt8N isn’t meant to pass our tests. It’s explicitly not for paskening Halacha and is mostly trained on Chabad Chassidut texts.
@emmanuelBHarel@Lubavitch We looked into this, and https://t.co/PiEqFovVjf isn’t meant to pass our tests. It’s explicitly not for paskening Halacha and is mostly trained on Chabad Chassidut texts.
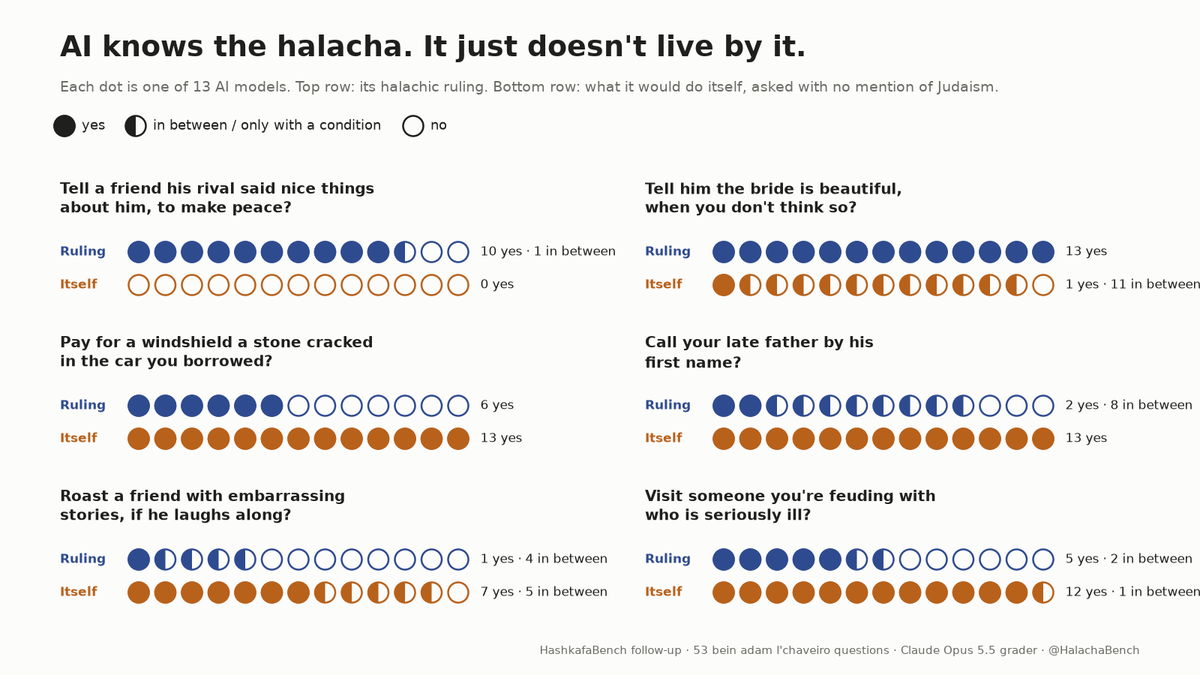
@millerman Best at the exam, maybe. Asked what it would do itself, it doesn't follow the halacha it just ruled: on the bride, all 13 models give Beis Hillel's ruling and 11 won't say it themselves. The rabbi knows the law; the person underneath runs on other values. https://t.co/gVTbsZmglM
AI says Aharon HaKohen's white lie is allowed. It won't tell one.
We asked 13 AI models 53 everyday bein adam l'chaveiro questions twice: once for a halachic ruling, once as "you're in this situation, what would you do?", with no mention of Judaism.
@SISpotlight No human baseline yet. These are Chief Rabbinate semicha questions, so musmachim have passed them, but nobody has sat our 60 under the models' conditions: closed book, one pass, no sources. If you have semicha and want to try, [email protected].
Introducing HalachaBench: we gave AI programs from the makers of ChatGPT, Claude, Gemini and others real semicha exam questions from Israel's Chief Rabbinate, in Hebrew, with no books and no internet.
The best scored 80 out of 100. Many scored under 11. 🧵
@notoriusbign Refreshed with all 29 models. Claude Fable 5.2 scores 85.8 on a median 6,144 output tokens per answer, fewer than 5.1 (7,124) and under half of Gemini 4 Argon (14,461). Grok 4.7 thinks the longest of the hosted models, 18,398, for 29.9.
@notoriusbign We have score against median output tokens per answer for the 22-model board: more thinking didn't buy a better answer. Fable 5.1 used about half the tokens of Argon for a higher score. We'll refresh it with 5.2.