Two employees from METR and Redwood Research worked on premises at OpenAI for three weeks this summer in an embedded assessment pilot. This team evaluated the systems OpenAI was using to monitor for misalignment from internal agents. A brief write-up of their work is now public.
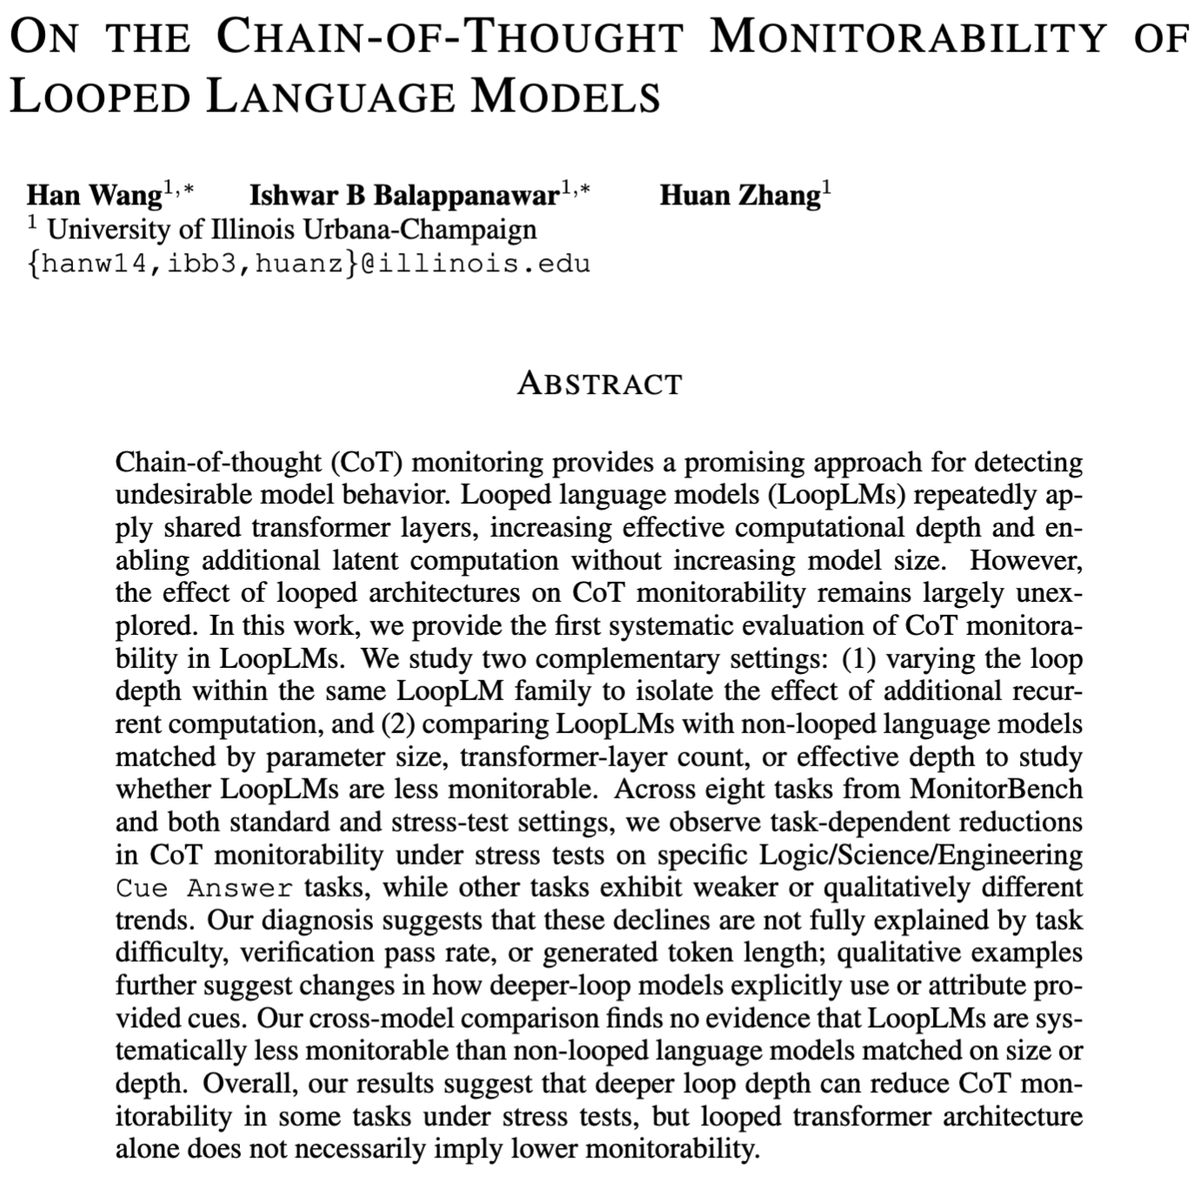
Paper: On the Chain-of-Thought Monitorability of Looped Language Models
Paper: https://t.co/DyDv4E4KMb
Code (MonitorBench): https://t.co/lYG4BJPAyj
Happy to chat! 6/6
GPT-6 Astra's CoT is harder to monitor. We wonder if looped transformers could be part of the explanation.
Our new paper provides the first systematic evaluation of CoT monitorability in looped LMs. 1/6
Takeaways in summary:
• Deeper loops can reduce CoT monitorability on some tasks under stress tests. And task difficulty, pass rate, and CoT length don’t fully explain the observed declines.
• Looped architecture alone doesn’t imply lower monitorability. 5/6
I’ll be at #COLM2026 presenting two works:
🔹 MonitorBench: https://t.co/loFXPS1ZqA
🔹 CoT-Guard: https://t.co/QQ7JFpyqwn
Recently, I’ve been working on CoT monitorability and LLM deception. Would love to chat about anything — come say hi!
Happy to announce CoT-Guard: our RL-trained 4B CoT Monitor for Code!
We will present our findings in an oral presentation at AdvML-Frontiers × CoTMA Workshop at COLM next month — highlights in the thread below! 🧵
Work with @huan_zhang12 , @ffmagicbean , @HanWang178023 , and Capital One.
(1/n)