introducing BarunLM (35m) 🤗
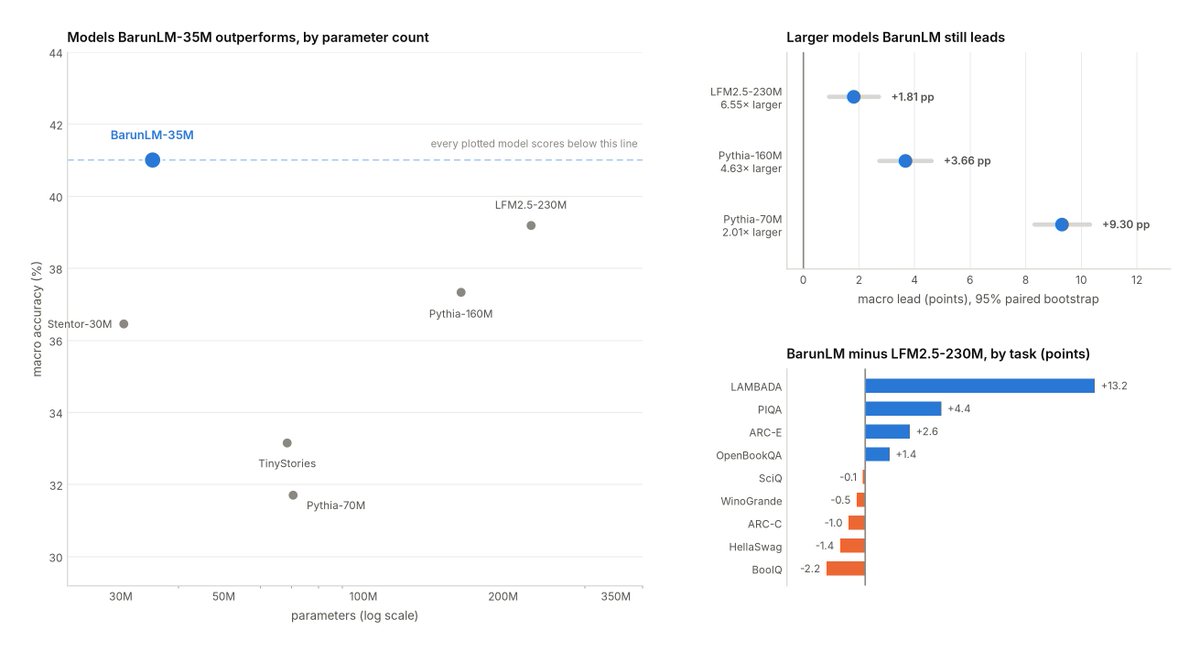
i pretrained the world's best small model under 100m parameters.
a 35m parameter language model that outperforms models over 6x larger, including LiquidAI's lfm2.5-230m, while training on a single H200 gpu.
the gains come from a better architecture. we took inspiration from deepseek, kimi, and other frontier open source models.
BarunLM combines hybrid local and global attention, grouped query attention to reduce memory, partial rope, gated attention, bounded swiglu, and residual selectors to improve how information flows through the network.
after pretraining, we further improved the model with rlvr (reinforcement learning with verifiable rewards) using deterministic verifiers and rloo, allowing the model to reinforce correct reasoning without relying on human preference labels.
I made a tool that let's you skip video editing
It uses hand gesture to place elements/media/overlays on your video in real time,
demo: (video created using Rii-Flow)
My co-founder @ArmanHezarkhani broke down Kimi K3 (new 2.8T parameter Chinese model) on @FoxBusiness today with @cvpane.
We had our engineers testing it all day before he went on air.
Here's the gist:
1) K3 is very good. As good, if not better, than many of the American frontier models.
2) The cost story is being misread. Everyone expects a Chinese model to be the cheap one. Per token, K3 is competitive. Per run (the actual job you outsource to the model), it's as expensive as the frontier models. But it's supposedly open source, so developers will attack the cost curve. Give it weeks, not quarters.
3) The playbook should look familiar. It's the same one China ran on solar panels & EVs: flood the market with cheap supply, wait for the addiction, then move the price.
4) The internet & the space race were funded by the US government, and innovators competed on top of the platform. AI got funded by private markets, and now the same companies that spent those trillions are getting hamstrung right as China gives its models away.
5) On guardrails: the bad guys will have completely unconstrained tools no matter what we do. Foreign adversaries, and bad actors here at home. If the good guys don't have equally powerful tools, only one side is armed.
6) Commoditized models are actually good news for the hyperscalers. All that open source intelligence has to run somewhere, and Google & AWS will get paid a lot of money to run it.
7) The labs saw this coming too. It's why Anthropic & OpenAI are racing up the application layer instead of just selling tokens.
Andrej Karpathy just said what no one wants to admit:
"Your agent loop is generating garbage at scale and you can't see it."
1 output looks fine. 1,000 outputs = dead entropy, dead diversity.
90% of AI companies are building demos, not products.
In a 20-minute conversation, Karpathy reveals the full reasoning stack
Hey I have this contact, let me call him 😂.
It would also be funny if for example anthropic would release Mythos tomorrow and a new model Kimi k4 would surpassed it
Someone call Dario please : Kimi K3 surpassed Fable 5
"A Guy who owns an AI company doesn't want AI companies to be competed with by low-price versions"
Dario said : "Open Source Run Ultimately you have to host it on the cloud"
(he totally don't know "how to run smaller moes and even dense models like qwen 27B not on the CLOUD.")
Alhamdulillah I just published my first research paper!
My study benchmarks Transformer models for Hausa Sentiment Analysis, showing that smaller African-centric models can retain 82% of SOTA accuracy while being 2× faster — making AI more deployable in low-resource settings.