We just launched HeyMilo Red. https://t.co/gqVYr1WqKo
A standalone cheat detection layer that analyzes recordings for AI-assisted answers, coaching, second screens, proxy candidates and synthetic media, then returns timestamped evidence for human review.
API-first and built to work with existing interview workflows.
We don't use an AI avatar interviewer, the data told us not to.
Candidates felt more confident and performed better without one. It creates a better interview experience for them, and better signal for the hiring team.
Sometimes the more "human-looking" AI experience is actually the less human one.
@CriteriaCorp's new hiring report found 4 in 10 hiring professionals are struggling with candidates using AI to misrepresent themselves, and more than a third say they can't reliably catch it.
That puts much more pressure on the interview itself to produce useful signal.
How someone answers, follows up, reasons and responds in the moment is becoming more valuable than another polished application artifact.
This is why we built Red.
@Microsoft + @huggingface ThinkingBox is heading in a direction we care a lot about: evaluate what actually happened, rather than what the agent says happened.
We took a similar approach with https://t.co/j90j2Dxw76. The grader doesn't care whether the agent says it built the integration, or even whether the code looks good. It checks the vendor request logs and resulting system state.
For agents doing real work, the state of the system is the answer.
There are at least two versions of "the model got the answer right."
It produced the expected output in a test, or it behaved correctly inside the actual workflow.
We care much more about the second.
@RonanKMcGovern A long pause before a detailed answer is one example. It could be someone thinking carefully or getting outside help, and treating the pause alone as evidence of cheating risks unfairly flagging a legitimate candidate.
We spend a surprising amount of time thinking about "reasonable human behavior."
A candidate pausing for 15 seconds might be thinking, reading notes, having connection problems or getting help.
Systems that interact with humans have to deal with ambiguity rather than pretend it doesn't exist.
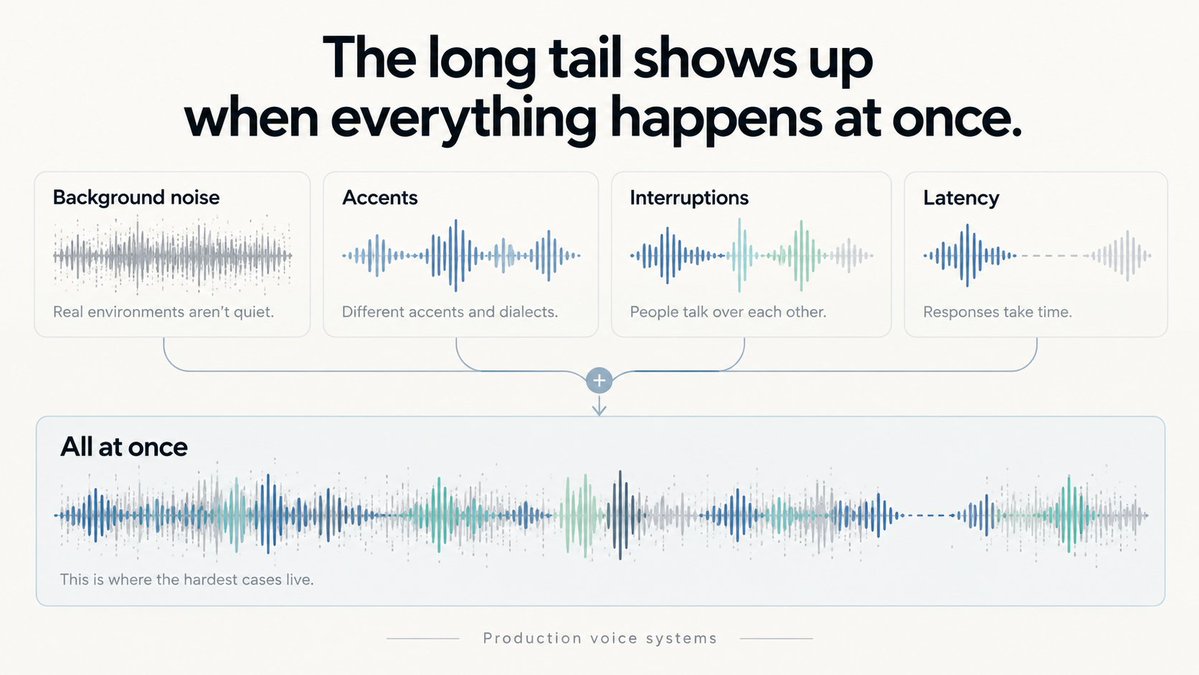
We've found that production voice systems expose the long tail very quickly.
Background noise, accents, interruptions or latency aren't separate problems. The difficult cases are combinations of them happening at the same time.
Interview integrity should produce hard evidence, not just vibes.
"Risk score: 82" is vague and hard to act on.
"03:42-04:18: off-screen reading, cadence shift, corroborating transcript pattern" gives a reviewer something they can inspect and act on.
That's why we built Red
AI is no longer just for tech giants; it's transforming small businesses in significant ways.
From streamlining operations to enhancing customer experiences, AI is becoming a vital tool for SMBs to stay competitive.
Want to learn more about how AI is impacting small businesses? Check out this article from All Business: https://t.co/GiVIAFvxwq
Seven of 50 tasks scored zero for every model.
Not syntax failures but coordination failures: delayed state, event delivery, systems that disagree about what happened.
The leading model still left 31 points on the table for work a competent integration engineer finishes routinely.
The biggest gap wasn't model quality. It was surface type.
Polling tasks averaged 63.7 out of 100.
Webhook tasks averaged 22.8.
A 41-point drop across all 20 models.
Verify signatures, handle duplicates, reconcile missed events: the code can look done while the vendor log shows duplicates.
We tested 20 AI coding agents on 50 ATS integration tasks against live APIs.
Fable 5.1 scored 69.3 out of 100.
None cleared 70.
Today we're releasing Integration Bench: https://t.co/SqDnlfwCHY
#AI is changing hiring from both sides.
@HeyMiloAI's Sabashan Ragavan shares why recruiters are turning to AI and spending more time on the human side. 🤝
He was also joined by Wilson's Rebecca Khosrowfar and Lee White.
🎥 Watch the full webinar: https://t.co/6CGVAkSwSJ.
Some exciting news!
We've raised $6 million in funding, led by @Category_VC with participation from @canaanpartners, @alumniventures, and @remarkable_vc
Also launching today: three new agent types.
1. Candidate Recommendations resurfaces talent already sitting in your ATS.
2. AI Scenario Assessment measures how candidates work with AI, built for data annotation, technical, and AI-adjacent roles.
3. Notetaker captures structured notes from live recruiter-led interviews so every candidate interaction produces consistent, reviewable signal.
We've screened 1M+ candidates on the platform, 4x revenue in six months, and have brilliant customers like Randstad, Wilson, and Neo Financial in production today.
Now back to building!
Read the full announcement:
https://t.co/Qm0ZAbqciO
Is your hiring strategy future-proof? 🚀
Insights reveal AI is no longer just assisting recruitment – it's driving it. Discover what this means for talent leaders: https://t.co/OVQUFYN2CJ
#AI#Recruiting#FutureofWork#TalentAcquisition