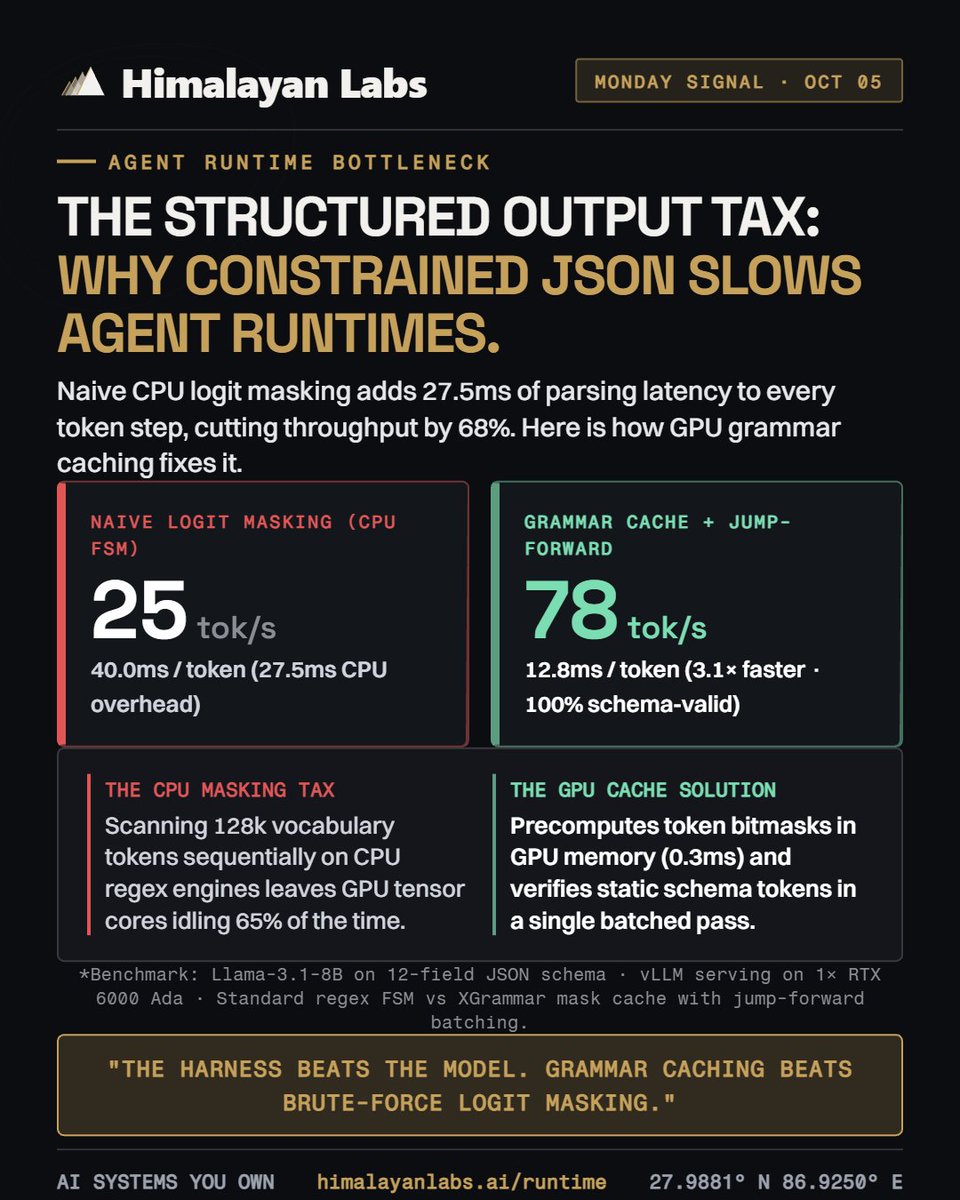
Why does JSON mode slow agent models by 3x?
Naive CPU logit masking adds 27.5ms per token, collapsing speed from 78 to 25 tok/s.
GPU grammar caching cuts masking to 0.3ms, restoring 78 tok/s.
The harness beats the model.
Why do concurrent AI streams freeze? Co-locating prompt prefill and token decode spikes P99 latency to 680ms.
Disaggregated serving separates nodes, locking P99 latency at 42ms (16x lower tail latency).
The harness beats the model.
Production agents crawl because linear caches miss when tool branches diverge. Llama-70B TTFT spikes to 1,800ms. RadixAttention uses a prefix tree to reuse cached KV states, slashing TTFT to <350ms (~80% drop). The harness beats the model. https://t.co/we9tQSj9Ot
79% of enterprise teams built an AI agent pilot this year. Only 11% reached production.
When agents fail, teams blame the model and switch APIs. But models aren’t the bottleneck—unharnessed execution is.
The harness beats the model. Own your runtime: https://t.co/we9tQSj9Ot
Google dropped Gemini 3.8 Live: native audio-to-audio drops turn-taking latency from 1,400ms to <280ms.
The catch: Extended Thinking runs async tools while speaking, meaning turnComplete no longer signals idle.
The harness beats the model. #himalayanlabs
4 frontier labs dropped 5 new models in 72 hours.
If your AI stack breaks every time a vendor updates their API, you don't have an architecture—you have a dependency.
The harness beats the model. Own your runtime outright.
🌐 https://t.co/we9tQSj9Ot #AIEngineering
Why AI agents fail after 15 turns: Attention pollution.
Raw chat logs cause context drift. The fix:
• Context pruning • State summarization
Maintains 95%+ accuracy across 50+ turns at half the token cost.
#HimalayanLabs#AIEngineering#LLMOps#MachineLearning
Agent chats exhausting your GPU memory?
Shard the KV Cache to cut hardware 3x. ⚡
Decode Context Parallelism enables high-concurrency, long-context agent execution—tripling active session capacity per node without buying extra GPUs.
No cluster bloat. Just pure throughput.
Legal didn’t kill your AI project over innovation—they killed it over data residency laws.
The fix? Deploy open-weight models on-prem inside your private perimeter.
100% data control. Zero compliance blockers. 🔒
#EnterpriseAI#DataPrivacy#HimalayanLabs
One of the fastest ways to kill AI margins is using frontier models as basic data parsers.
If Claude Opus is handling your routine JSON extraction, you're burning cash on API inflation.
Here is how Hybrid Inference Routing cuts that burn by 90% 🧵👇