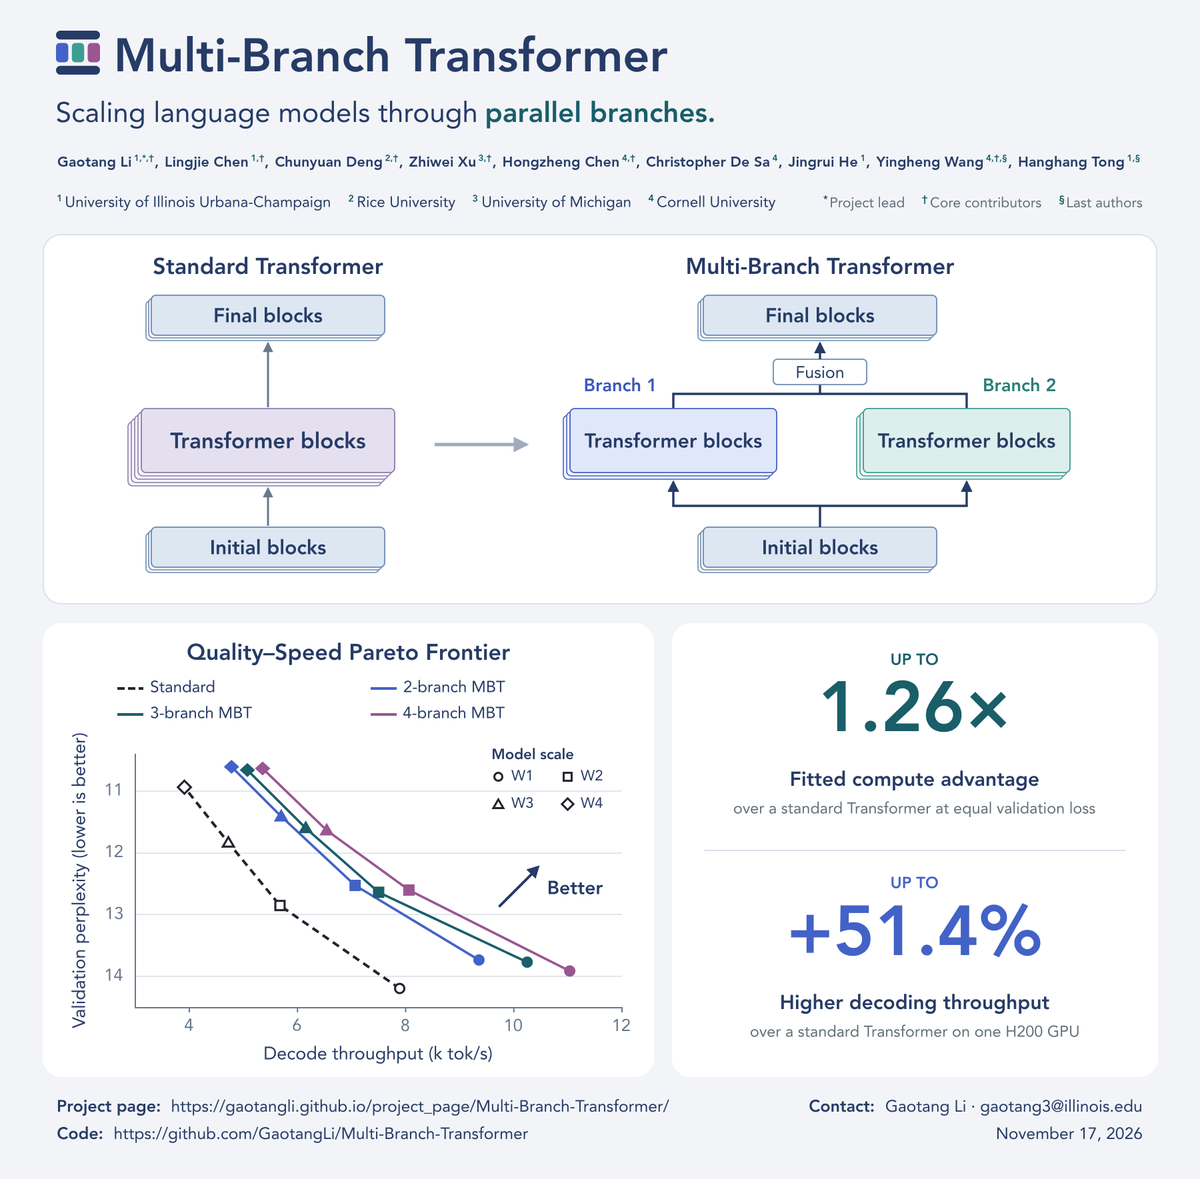
Transformers usually scale by making their blocks wider or stacking them deeper.
We show another path toward scaling LLMs: branching.
Introducing Multi-Branch Transformer (MBT): parallel composition of full Transformer blocks.
TL;DR:
• Better scaling: across a controlled pretraining scaling ladder, MBTs improve language-model quality at comparable training compute. Fitted curves indicate a standard Transformer needs up to 1.26× as much training compute to match our final MBTs' validation loss.
• Consistent pattern: controlled sweeps show the same behavior at every scale. With two branches, loss is lowest with ~1/3 of the blocks in parallel and only returns to the standard model's level near 80%.
• Faster decoding: with Joint-KV cache sharing and a branch-aware inference engine, up to 51.4% higher throughput on one H200 and up to 34% less KV-cache storage. More branches push the quality–speed Pareto frontier further out.
The architecture, the scaling results, and how we make it fast. 🧵
Sparsity can make your LoRA fine-tuning go brrr 💨
Announcing SparseLoRA (ICML 2025): up to 1.6-1.9x faster LLM fine-tuning (2.2x less FLOPs) via contextual sparsity, while maintaining performance on tasks like math, coding, chat, and ARC-AGI 🤯
🧵1/
https://t.co/O3sY7fAqQW
❓ Are LLMs actually problem solvers or just good at regurgitating facts?
🚨New Benchmark Alert! We built HeuriGym to benchmark if LLMs can craft real heuristics for real-world hard combinatorial optimization problems.
🛞 We’re open-sourcing it all:
✅ 9 problems
✅ Iterative agentic framework
✅ Verifiers + evaluators
✅ Expert solutions
👉 https://t.co/itR3EHQuyR
🌐 https://t.co/s97foUeF47
💻 https://t.co/WcGg0XlDYo
[1/n]
Last week we celebrated our MLCommons Rising Stars 2024! 🎉
41 talented researchers
33 global institutions
2 days of innovative workshops
Thanks to @nvidia for hosting this year's event.
https://t.co/f9d7SoA5oa
#MLCommons#AIResearch#RisingStars