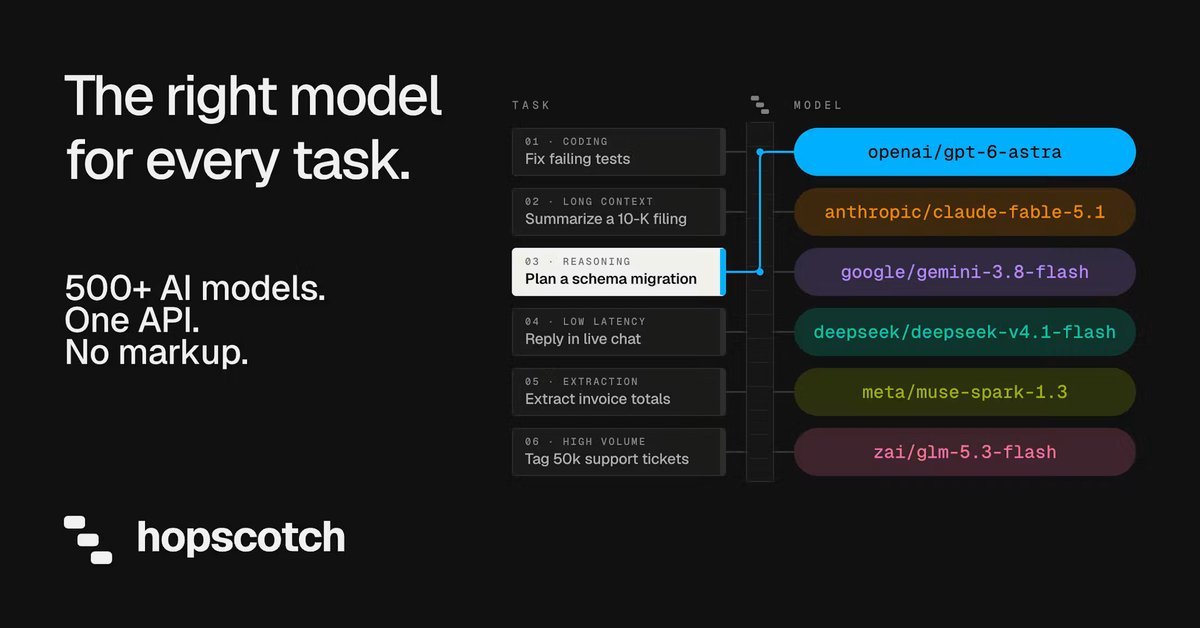
Access 500+ AI models with one API key and dashboard. Zero markup, customizable guardrails, built-in failover, and a team that's here whenever you need us.
Today we’re launching Hopscotch Passes, an all-in-one subscription to virtually EVERY AI model at half price for a flat monthly fee per seat.
Each seat gets twice its price in model use at provider rates, frontier models included. You can buy one in three tiers:
Starter: $20 a month for $40 of LLM access
Growth: $50 a month for $100 of LLM access
Pro: $200 a month for $400 of LLM access
Over a year that’s up to $2,400 of bonus LLM access per Pro seat.
Starter costs the same $20 a month as ChatGPT Plus or Claude Pro, but it buys $40 of API use across every model. Other routers compete on charging nothing over list price. A pass goes below it.
For teams, you pick a tier and a seat count, then assign seats to members. Allowances reset every month.
It’s all a little crazy, so we’re offering 1,000 passes for a limited time only. We think this is the best LLM router offer on the market, PERIOD.
Passes are live now: https://t.co/XrRQo0P6DI
Choose your backup models before you need them.
With a Hopscotch routing profile, you set the models and the order to try them. If the first can’t answer, the next gets a turn.
Which matters most for your fallback: output quality, latency or cost?
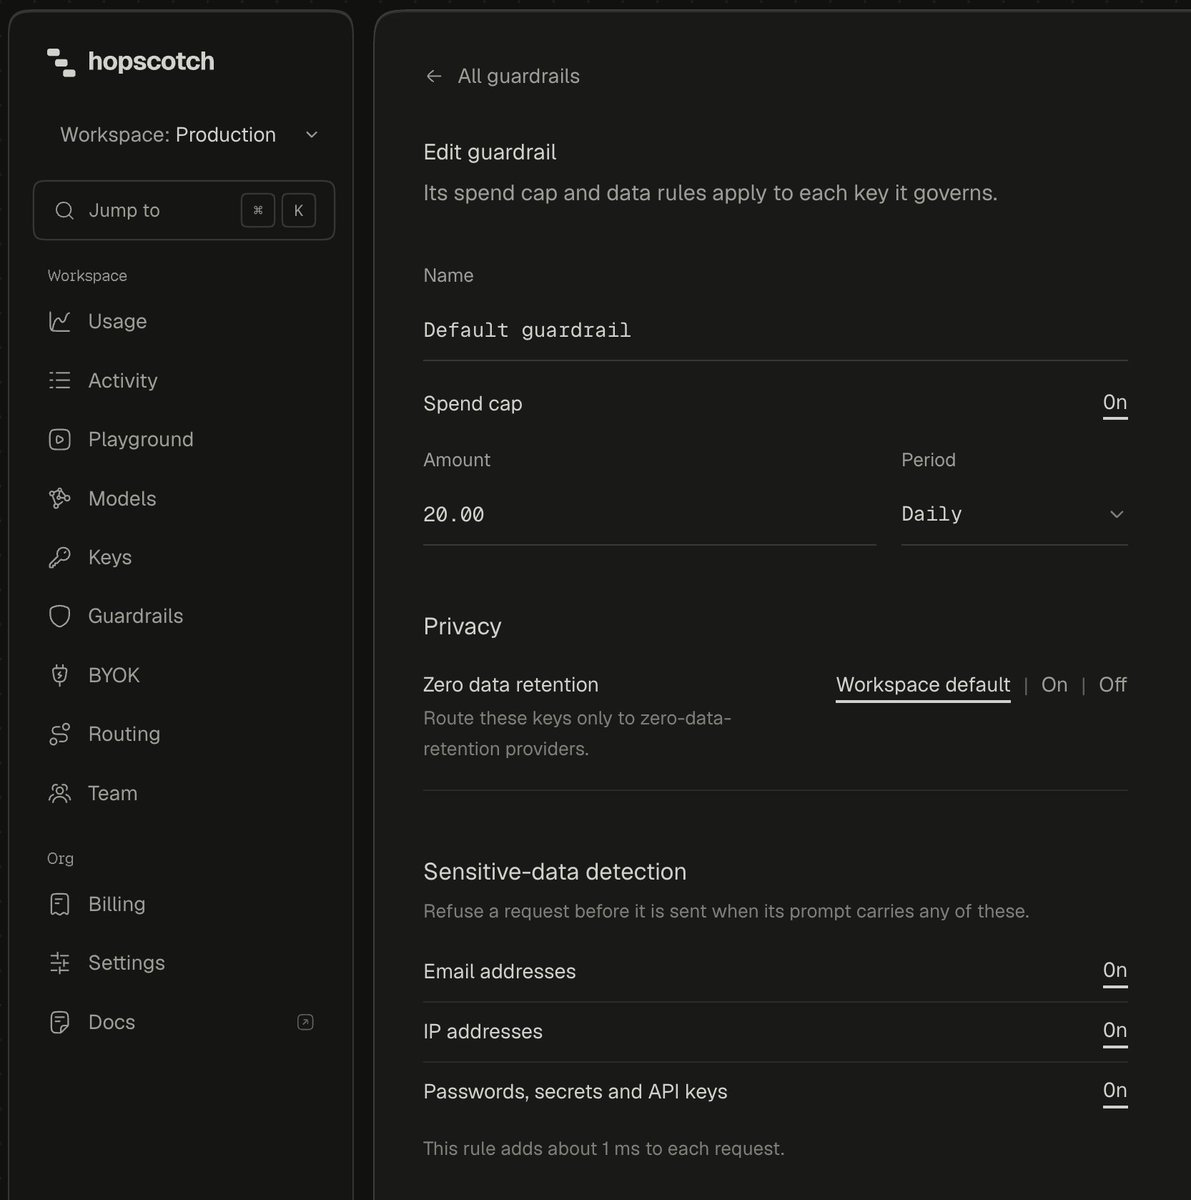
Introducing Guardrails for your LLM API keys. Now live in Hopscotch.
• Cap daily, weekly or monthly spend
• Block sensitive data before prompts reach a model
• Require zero data retention
Set your rules, attach them to your keys, and start building.
A team should be able to hand out LLM access without handing out the company card.
That's why we're excited to launch Guardrails, now live in the Hopscotch dashboard!
One guardrail applied across your team's keys, lets you:
• Cap monthly spend. Requests over the cap are refused before they reach a provider, so they cost nothing.
• Restrict keys to zero-data-retention providers. A request that would reach any other provider is refused before it is sent.
• Block prompts that carry email addresses, IP addresses, passwords, secrets or API keys, before they are sent.
Each of these was already possible per key or per route. A guardrail makes it a rule every key on the team follows, whether or not each developer set it.
This sits on top of what already shipped:
- spend limits per key
- adding teammates to workspace
- ordered fallbacks
- bring your own key 🔑
- a playground to compare models side by side
- a log of every request with its cost.
We are building Hopscotch around one idea: you should know what you are spending on AI, control where requests go, and be able to see what went wrong. Guardrails is the control part.
Routers helped prove this category. We think the cost and control developers actually get can be a lot better. 500+ models, provider list price, no per-token markup.
Shipping more this week. Learn more:
https://t.co/qm8CytX3Ss
Playing around with @HopscotchAI for a cheaper OpenRouter (model router) alternative to access uncensored models (a must today for any security reseracher)
Reasons I'm looking for an alternative:
- OR has hidden defaults like "Allow free endpoints that train on request data" which annoy me
- The routing fee is wild, unless you switch to price-sort, which in return sends your prompts to the entire world
- Going to a direct provider (e.g. digital ocean) may be predicted, but again not ideal routing fee
@HopscotchAI wins I found so far:
- beautiful fine-grained controls over daily caps
- 1 click zero data retention guardrails and data leakage blockers
- Chaining providers (!!) - instead of relying on "cheap" as a decision chain, you can create an ordered provider preferences to have complete control on where your data is going
I use hermes as a harness to plug to this, you can set it up in anthropic if you enable developer tools but hermes is more native to that kind of work
Before switching models, try the same prompt on the same task.
Compare answer quality, response time and cost.
The Hopscotch playground runs a prompt on up to three models side by side, so you can see the tradeoffs before changing your app.
An agent stuck in a loop should hit a spending limit before it drains your balance.
In Hopscotch, set budgets for each API key, teammate and workspace. Requests over the limit are refused.
Give your experiments room to run. Give them a ceiling, too.
One of the most important choices in your codebase is which AI model to use.
Better, faster, cheaper models come out every few weeks while most apps stay on the one they started with because trying another means a new set of things to manage.
Hopscotch lets you access 500+ models without managing separate integrations, accounts, or payments. Compare models on your own prompts, set up fallbacks, and track usage and spend in one place.
We built Hopscotch because we think every task should run on the model that fits it best.
We’re live on Product Hunt today, link below