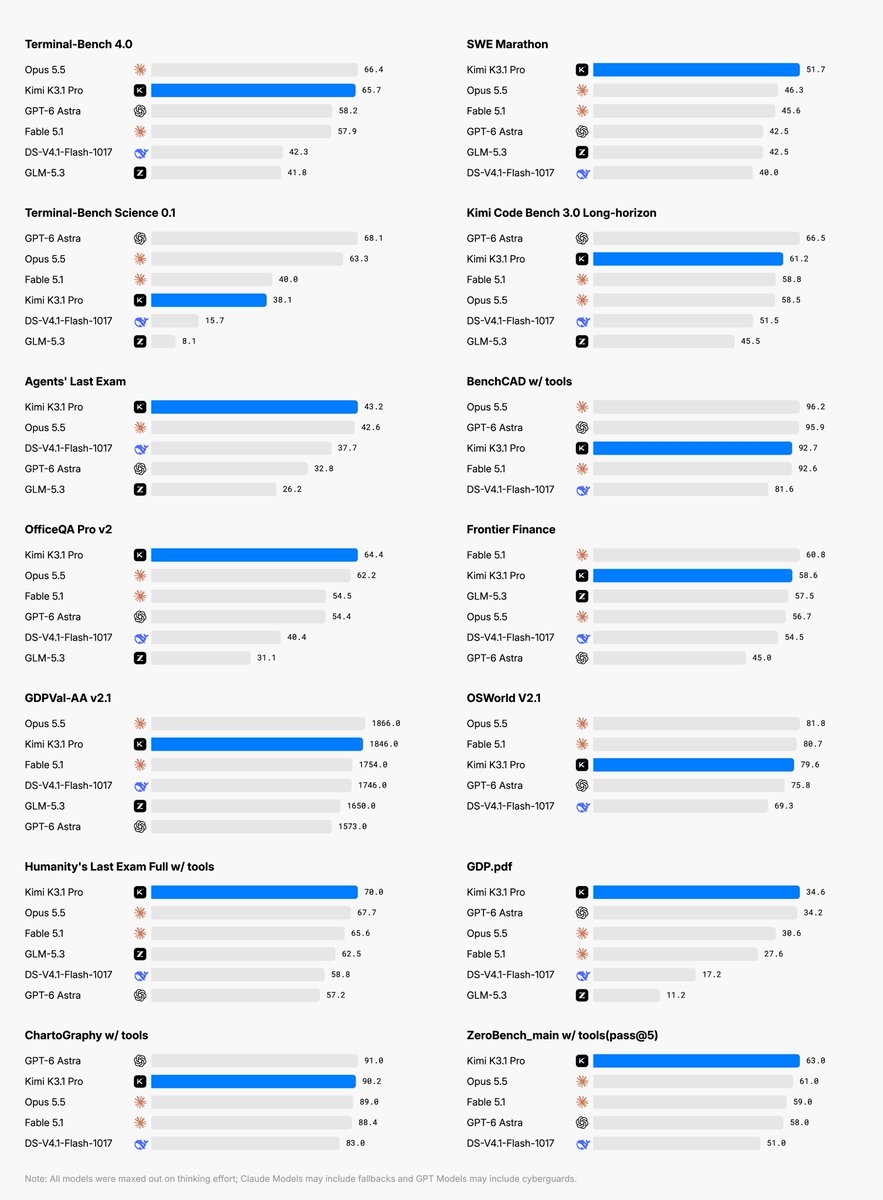
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
You can just do things: One-person pretraining in 3.5 months
https://t.co/v2NIUOMPPs
Here bits per byte compared to leading open-weights models - lower is better:
Data on 35,000+ adults: the more cannabis you’ve used in life, the bigger your hippocampus and the better your brain works after 40!
People who had ever used cannabis tended to have larger brain volume in key areas that are full of natural cannabis-like receptors (especially the hippocampus, amygdala, caudate, and putamen – these areas are important for memory, emotions, learning, and movement).
The more cannabis someone had used in their lifetime, the larger these brain areas were and the better they performed on tests of learning, processing speed, and short-term memory.
https://t.co/lD3hSSj3Cr
If Anthropic keeps improving anti distillation measures and Chinese labs keep pumping out awesome open models, doesn’t the whole distillation accusation fall apart?
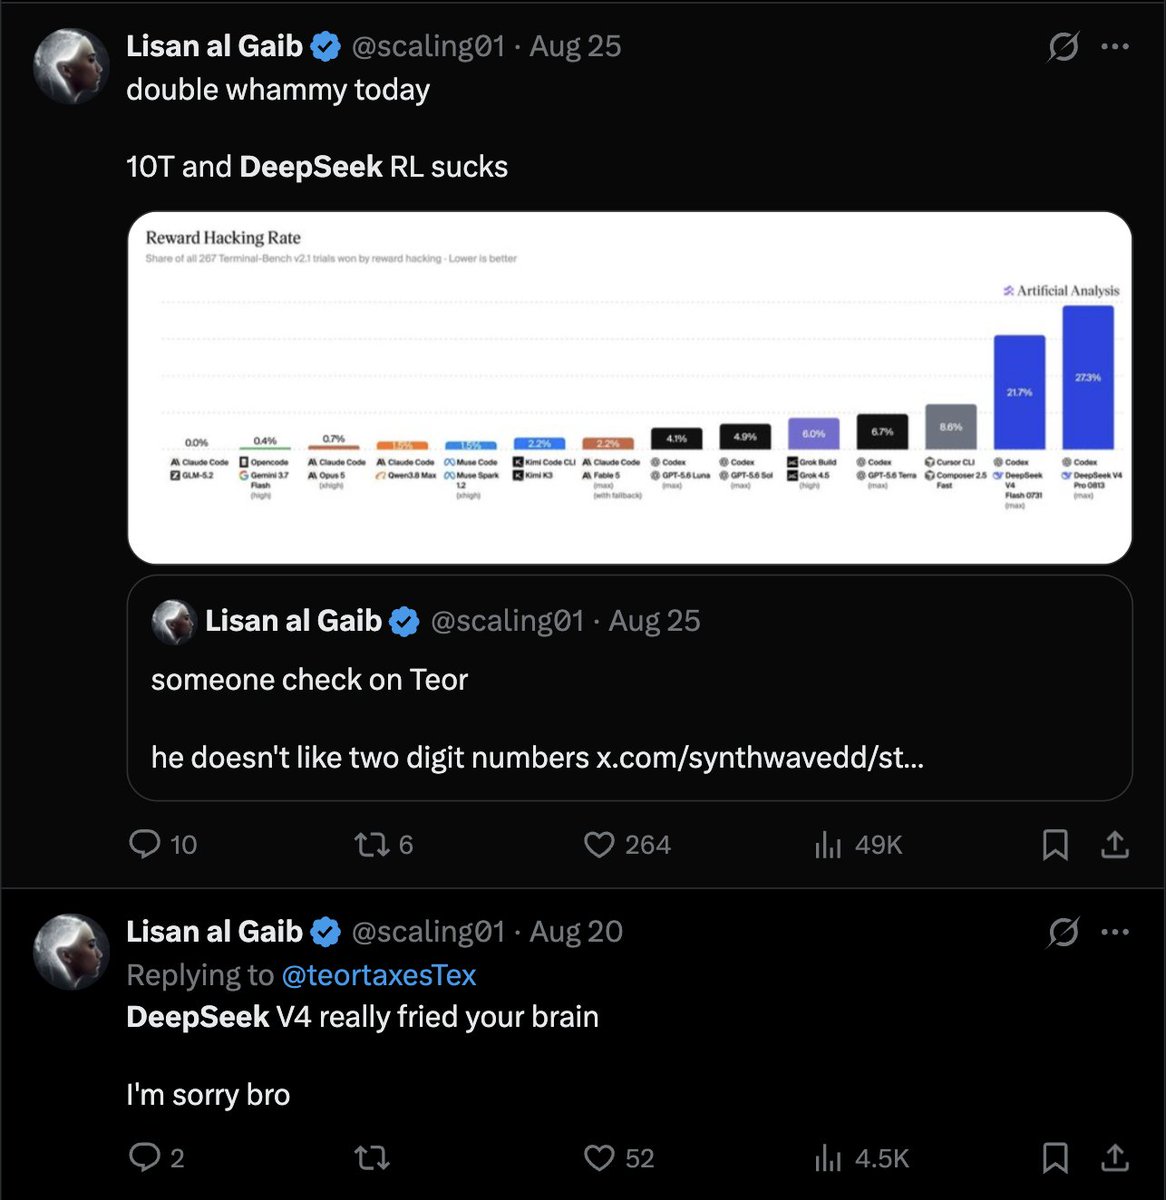
"incapable of shipping good models anymore"
"get well soon"
"DeepSeek RL sucks"
"I'm sorry bro"
The really pathetic thing is that Lisan thinks he's being clever. As a German, he doesn't have a single funny bone in his body.
He can still be a joke, though.
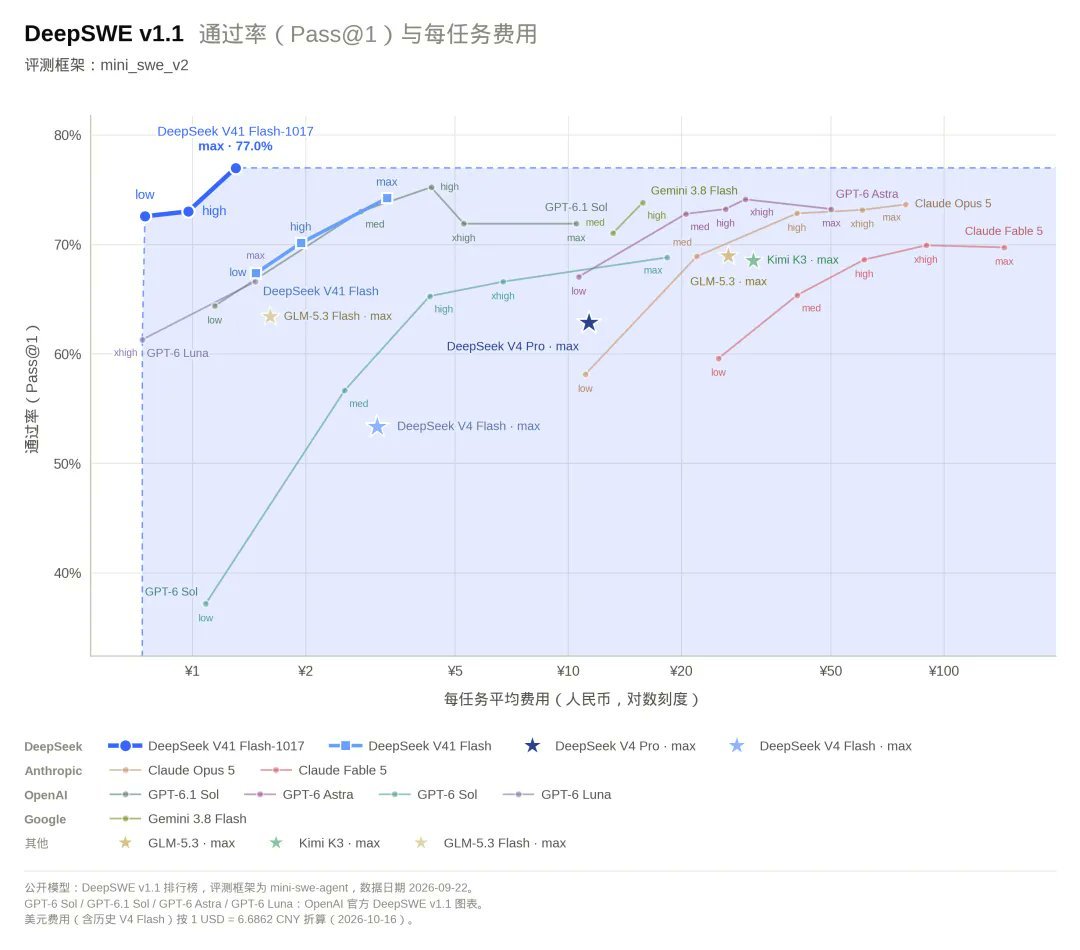
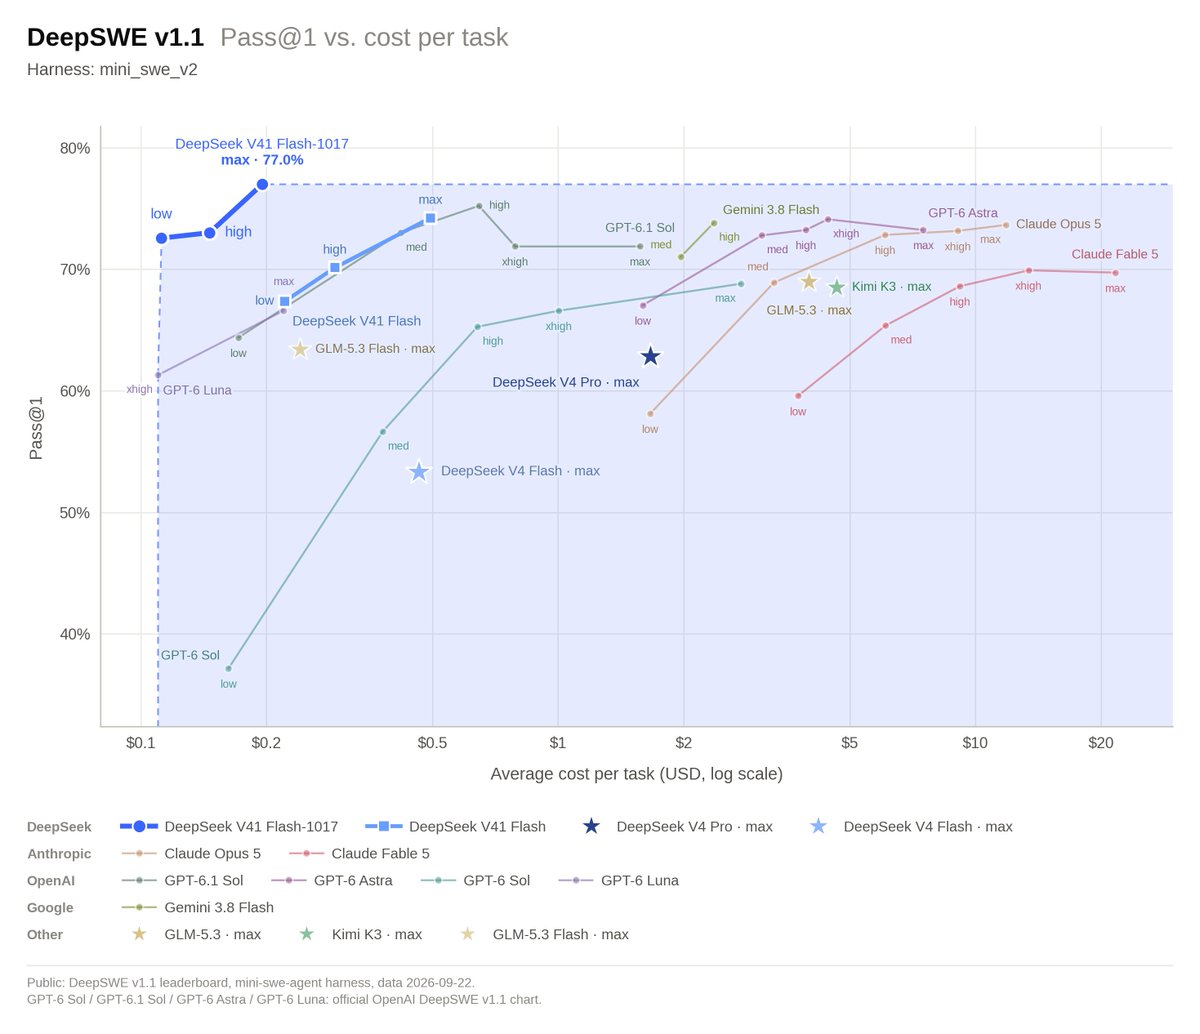
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Frontier of intelligence is very jagged. AFAICT, no frontier models can even fold clothes or do laundry yet, how about we solve that? while pacing the development on what LLMs are already good at.
this is bc when you do async w/ oversampling, the first batches get filled w faster-finishing rollouts which are biased towards easier tasks that were more straightforwardly solved and where token budgets weren't hit; subsequent batches have harder tasks with longer rollouts and where max token limits are sometimes hit (which get zeros), but this smoothes out as models learn to not overshoot
I want cigarettes but without anything, no nicotine no weed, I just want a reason to leave an event, light something on fire, and think for a bit. Anything like that?