New blog post: observations on training instability in RL for long-horizon agentic LLMs, with a focus on retokenization drift.
Feedback and discussion welcome.
👉 https://t.co/uK8O5hdYby
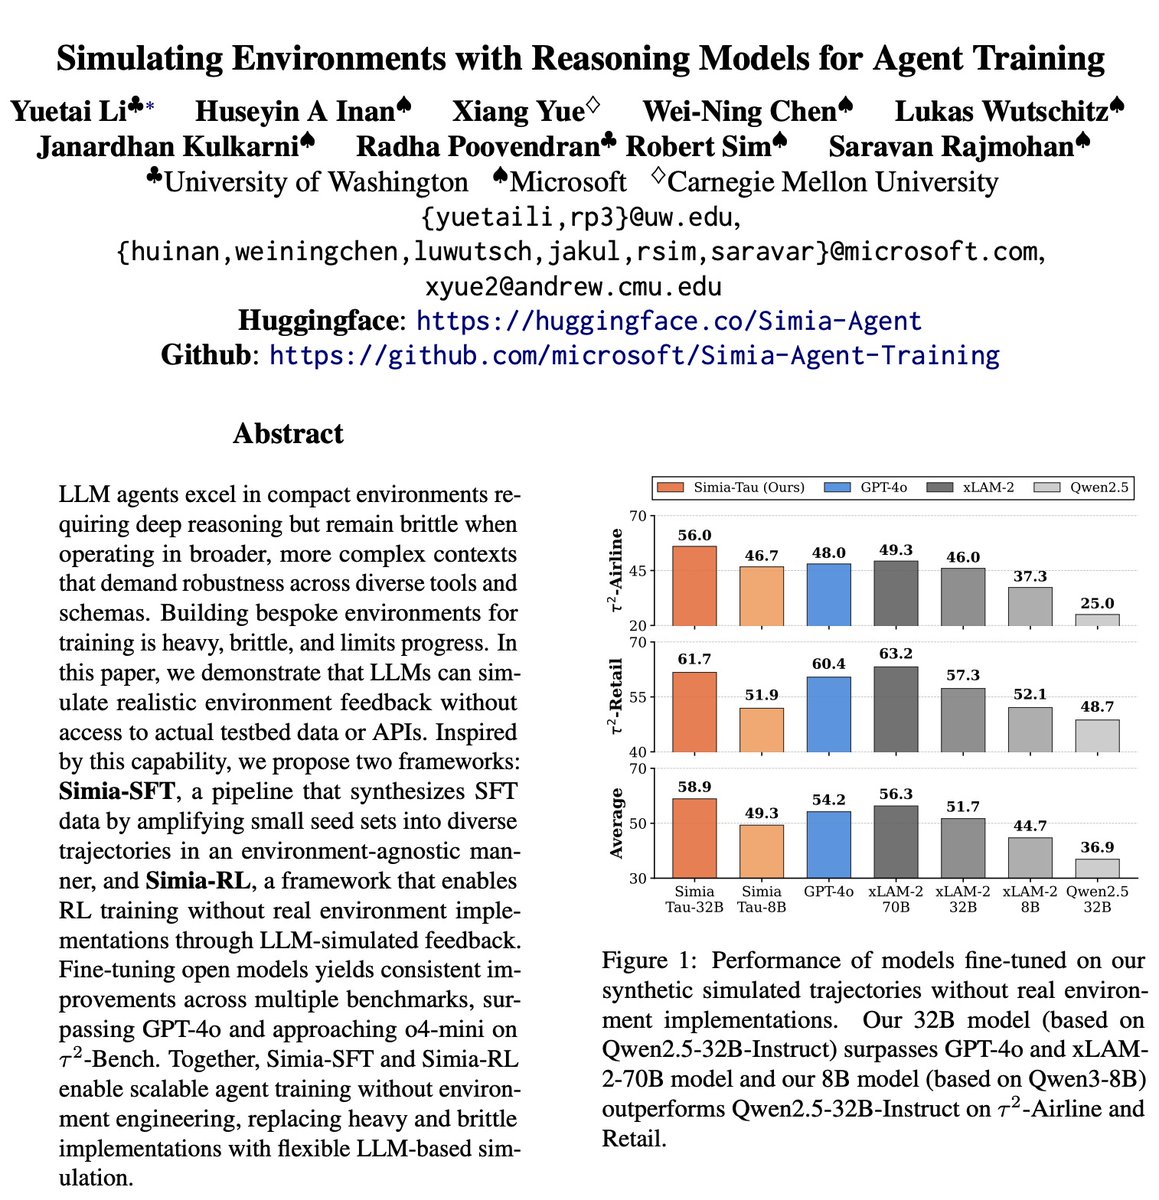
Free your hands 🙌 from endless agent environment engineering!
Tired of building envs to train agents? We ditched them entirely.
Turns out, LLMs can reason to generate realistic env feedback from just tool specs + reference examples.
So we trained agents without any real envs: synthesizing simulated SFT trajectories + RL on simulated env.
One prompt = one new environment.
No env code, no pain.
We burned through GPT-5 APIs to curate 90K+ SFT trajectories, now open-sourced here 👉 https://t.co/EEObGsMQ5v
Result? Strong perf on τ²-Bench 💪
Imagine a future where agent training scales across thousands of simulated envs — powered purely by LLM.
➡️ https://t.co/D4nmL5F6te 🔥🔥
There's much more to explore, but for all the details, check out our paper and code! 🚀📄💻
📜 Paper: https://t.co/DwhRpzzIvk
💾 Code: https://t.co/DIoNDOPvIg
Let me share our fair share of emergent behaviors! 🚀 Our Reinforcement Learning Self-Play (RLSP) framework enables the emergence of complex reasoning abilities in LLMs—without relying on stronger teacher models. Check out our latest paper! 👇📄
We can achieve this by the simplest exploration reward that encourages the model to take more intermediate steps before arriving at a solution. Our key innovation? Decoupling exploration and correctness signals during PPO training! 🔄⚖️
Some text data is private & cannot be shared... Can we generate synthetic replicas with privacy guarantees?🤔
Instead of DP-SGD finetuning, use Aug-PE with inference APIs! Compatible with strong LLMs (GPT-3.5, Mistral), where DP-SGD is infeasible.
🔗https://t.co/qJeSQ0XJES [1/n]
📢📢Want to share your textual data outside your org or team but worry about privacy leakage? Check out our new preprint "Synthetic Text Generation with Differential Privacy: A Simple and Practical Recipe"(https://t.co/7jpDR2KoFr) 👇👇👇
And thanks to the robustness to post-processing
property of DP, we are free to build any model on the generated data or inspect/debug/investigate the samples with no additional privacy loss :)
As LLMs finetuned with DP show impressive performance on many NLP benchmarks, it is exciting to see that they can also be used to generate synthetic version of text datasets in a private manner: https://t.co/SXFdRWka0G
It includes language modeling examples with sample-level and user-level differential privacy. We'd like to actively continue adding more examples from different tasks (and also update it with more recent versions). We'd love to engage with community :)
Dear ppml community, we are happy to announce our repo https://t.co/FzslOwnRTd for training transformer models with differential privacy. It's based on two of my favorite libraries, integrating Opacus to the Hugging Face platform.
I have openings for Ph.D. students who are interested to join my group at @Mila_Quebec to work on #fairness and #privacy in machine learning.
Info: https://t.co/VgUFucbVNN
Deadline: Dec 1
Application form: https://t.co/6OdLXAaGWu
I appreciate retweets to help spread the word.
Privacy in AI team at Microsoft Research is looking for interns for Summer 2022 to be working on privacy-preserving ML and/or Federated Learning projects. Help spread the word please 🙂 https://t.co/Q7U8mrG2DH