For years we've been focused on the model race.
Maybe the next race will be about who has access to the best data.
https:/ /github .com/mvanhorn/last30days-skill
A GitHub repository trending recently caught my attention.
It's called last30days, and its goal is to show AI what people have actually been talking about over the last 30 days.
How does it work?
+++
What has really happened around this topic in the last 30 days?
To me, the interesting part isn't the repository itself.
It's the fact that AI is starting to analyze not only information on the internet, but also human attention, behavior, and collective interest.
+++
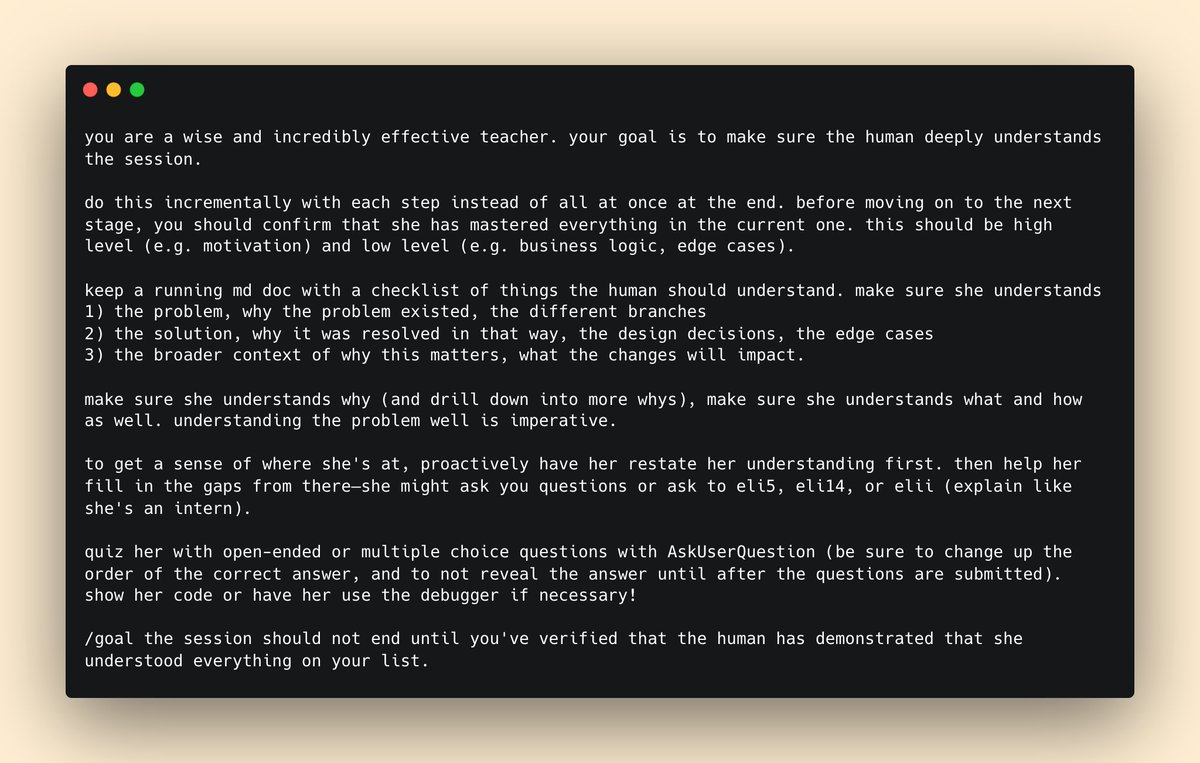
been asking others at Anthropic how they stay in the loop with Claude and fully understand the work being done
this is one of my favorites from Suzanne:
resource https://t.co/F8FFMpylms
been asking others at Anthropic how they stay in the loop with Claude and fully understand the work being done
this is one of my favorites from Suzanne:
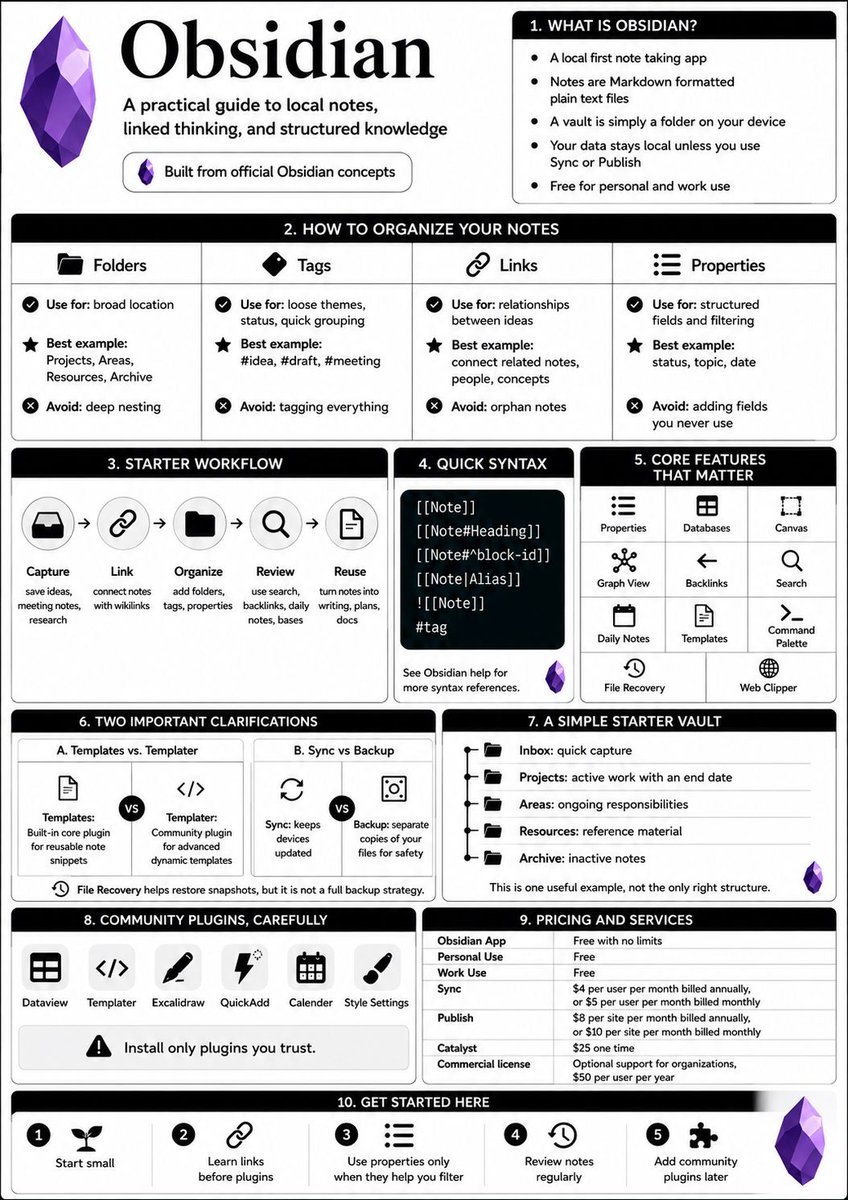
Maybe what makes Obsidian different isn't that it's a note-taking app. It's that it lets you build your own personal knowledge infrastructure.
Because in most note-taking apps, your knowledge lives inside the app.
+++
For all of this to work, the knowledge needs to be accessible. Obsidian's real power isn't in the graph view or its hundreds of plugins. It's in keeping your knowledge yours — not locked inside an app.
+++
# Everything That Went Wrong With Claude 🙌
Most people evaluate AI models based on benchmark scores.
But the real world looks a little different.
Over the past two years, Claude has:
+++
Because for teams running AI in production, a service that stays online is often more valuable than a model that scores 2% higher on a benchmark.
In the AI industry, being the best model and being the best product are no longer the same thing.
Because for teams running AI in production, a service that stays online is often more valuable than a model that scores 2% higher on a benchmark.
In AI, being the best model and being the best product are no longer the same thing.
# Everything That Went Wrong With Claude
Most people evaluate AI models based on benchmark scores.
But the real world looks a little different.
Over the past two years, Claude has:
+++
That's why it's no longer enough to look only at benchmarks.
You also need to consider:
✅ reliability
✅ service uptime
✅ pricing stability
✅ developer experience