Updating WordPress or Laravel alone won't fix PHP2Shell.
These PHP engine flaws can let unauthenticated attackers run code. Amazon reports exploitation in the wild.
Our guide covers affected versions, distro backports, containers and worker restarts.
https://t.co/owIZlrBjwI
Mistral’s Voxtral 3 adds a voice-agent SDK from $0.04/min with Small 4.
Phone access is enterprise-only, with inbound calls only. Voxtral 2 upgrades also lose word timestamps.
What the SDK handles and what developers still need to build:
https://t.co/Ryaqpg4Sje
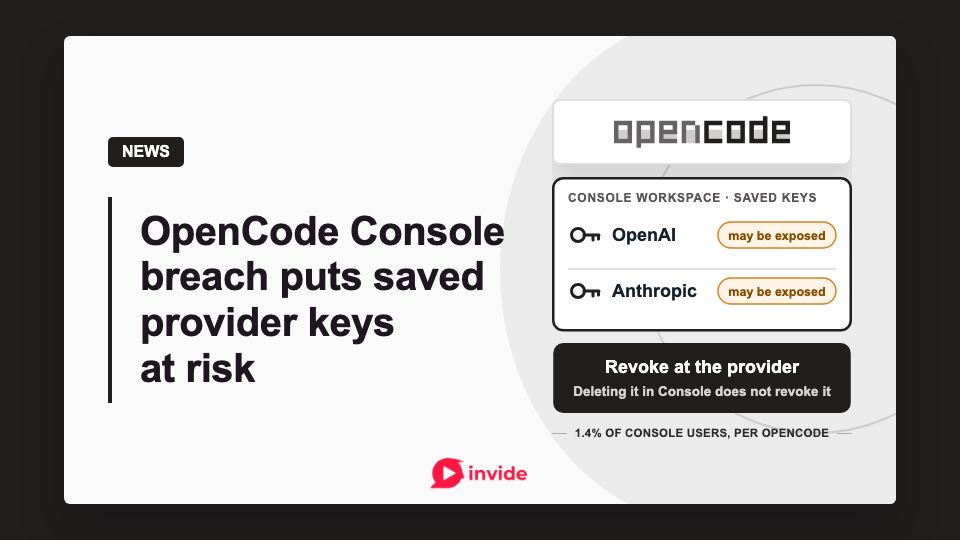
OpenCode says its Console breach affected 1.4% of Console users, with saved provider API keys potentially exposed.
Users report unexpected bills. We cover how to revoke and replace affected keys, the refund response, and what remains unclear.
https://t.co/zppq4nuxwP
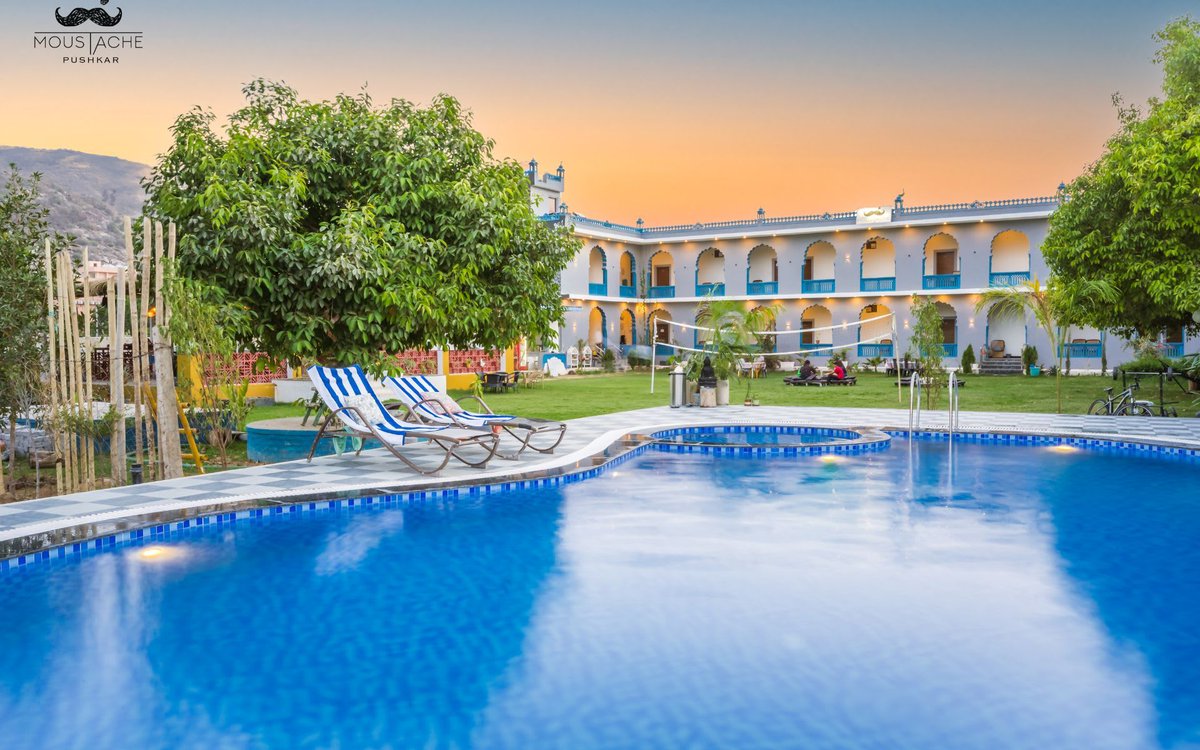
🏜️ Workation place of the month Oct 2026
📍 Moustache Pushkar - Rajasthan 🇮🇳
Gardens, pool, rooftop views and free Wi-Fi near Pushkar Lake.
✈ Kishangarh Airport (KQH) ~38 km
💸 ~₹3,850 for 7 nights (estimate)
Pi 1.0 is out, with built-in MCP support through Codemode.
Learn about Pi’s packages, how it works with local models through Ollama and llama.cpp, and where experimental Pi Durable fits.
https://t.co/bGc9EvJR5e
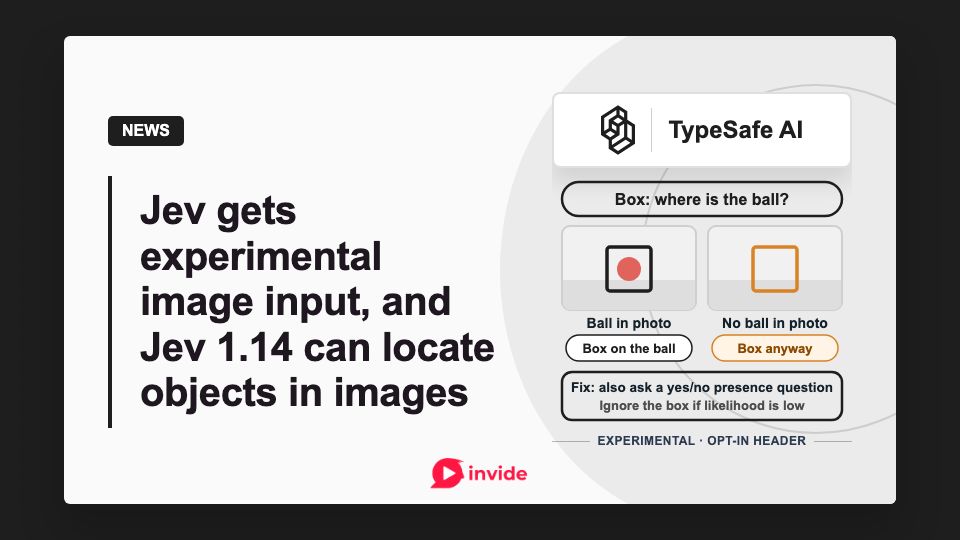
Jev gets experimental image input. Version 1.14 can locate objects in images, but it returns a box even when the object isn’t there.
We cover the presence check, version flags and SDK changes.
https://t.co/DuzH4Vog9c
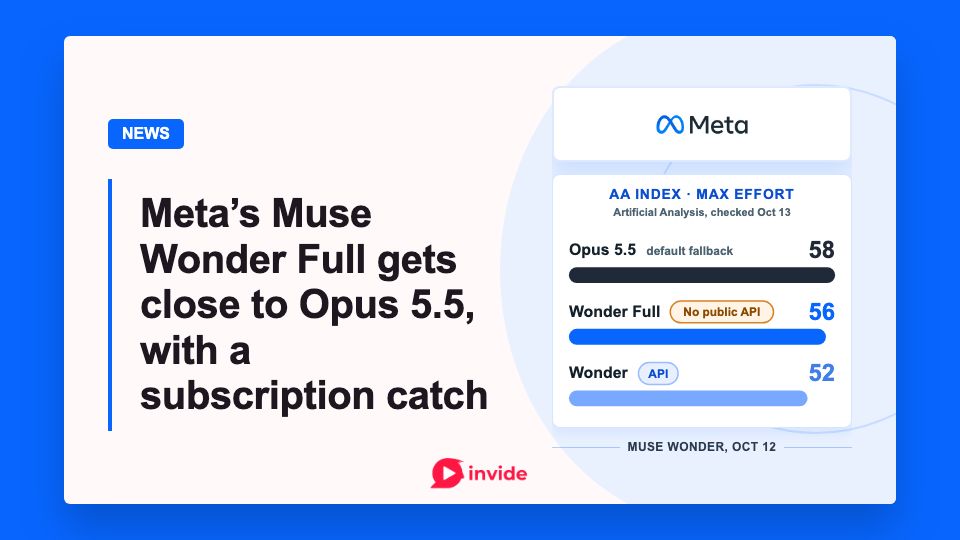
Meta's Muse Wonder Full scores 56 on AA's index at Max, versus Opus 5.5's 58 at Max with default fallback.
Full requires Muse Code Power or Maximum. API users get regular Wonder at $4/$20 per million input/output tokens.
Our breakdown: https://t.co/x8NGzSzJxl
What does a coding harness do around the model?
We map the architecture, then use Pi 1.0 to examine tool execution, steering, and context. A runnable test shows how rerunning a failed script can repeat a completed action.
https://t.co/1QRUgnCILp
Claude Haiku 5.5 cuts prices from $1/$5 to $0.10/$0.50 per million tokens, but only for prompts up to 100K.
Above that: $0.50/$2.50.
Even a short answer to a long prompt pays the higher output rate.
https://t.co/DWvJfBw4jN
When everyone is discussing Grok Bot vs Muse vs Dots, we organized a hackathon with experienced engineers to build their own AI Agent/Assistants in just 12 hours.
And many built AI Agents/Assistants to delegate a significant chunk of their work to AI
https://t.co/UQNQWiqs7Q
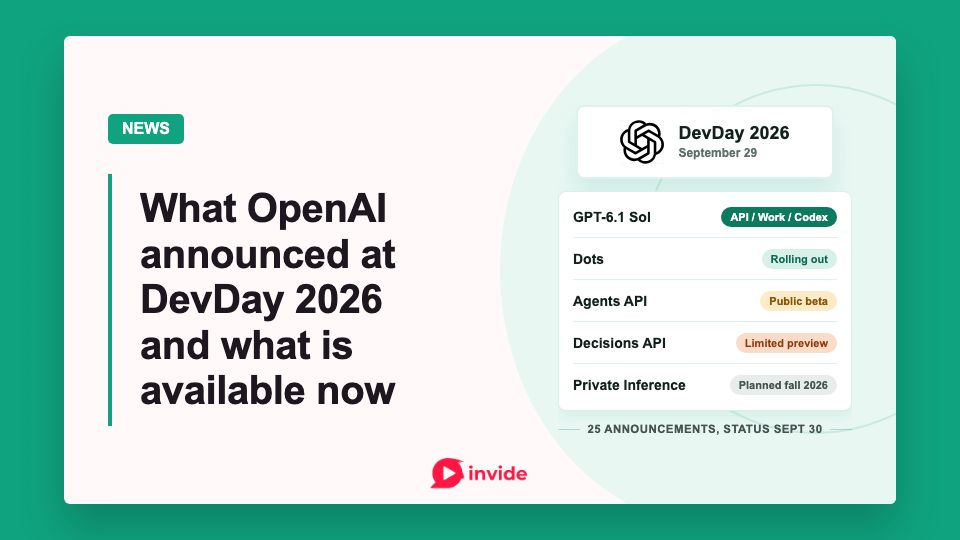
OpenAI announced 25 items at DevDay 2026. GPT-6.1 Sol is available in the API, Work and Codex; dots are rolling out; Agents API computer use is in public beta. Our roundup tracks what’s available now and what comes later.
https://t.co/ypyCnpd9zQ
@ipezyGJ Good question: Terminal-Bench 4.0 has 66 tasks. Artificial Analysis runs each 3 times and reports average pass@1. So 42% vs 33% is equivalent to roughly 28 vs 22 successful attempts per 66-task run.
GLM-5.3 costs ~9× Flash per token and scores 42% vs 33% on Artificial Analysis's Terminal-Bench 4.0. Kimi K3 costs about the same per index task. DeepSeek V4 Pro costs a third as much.
Our analysis covers benchmarks, migration and hardware.
https://t.co/024gBmrVEv
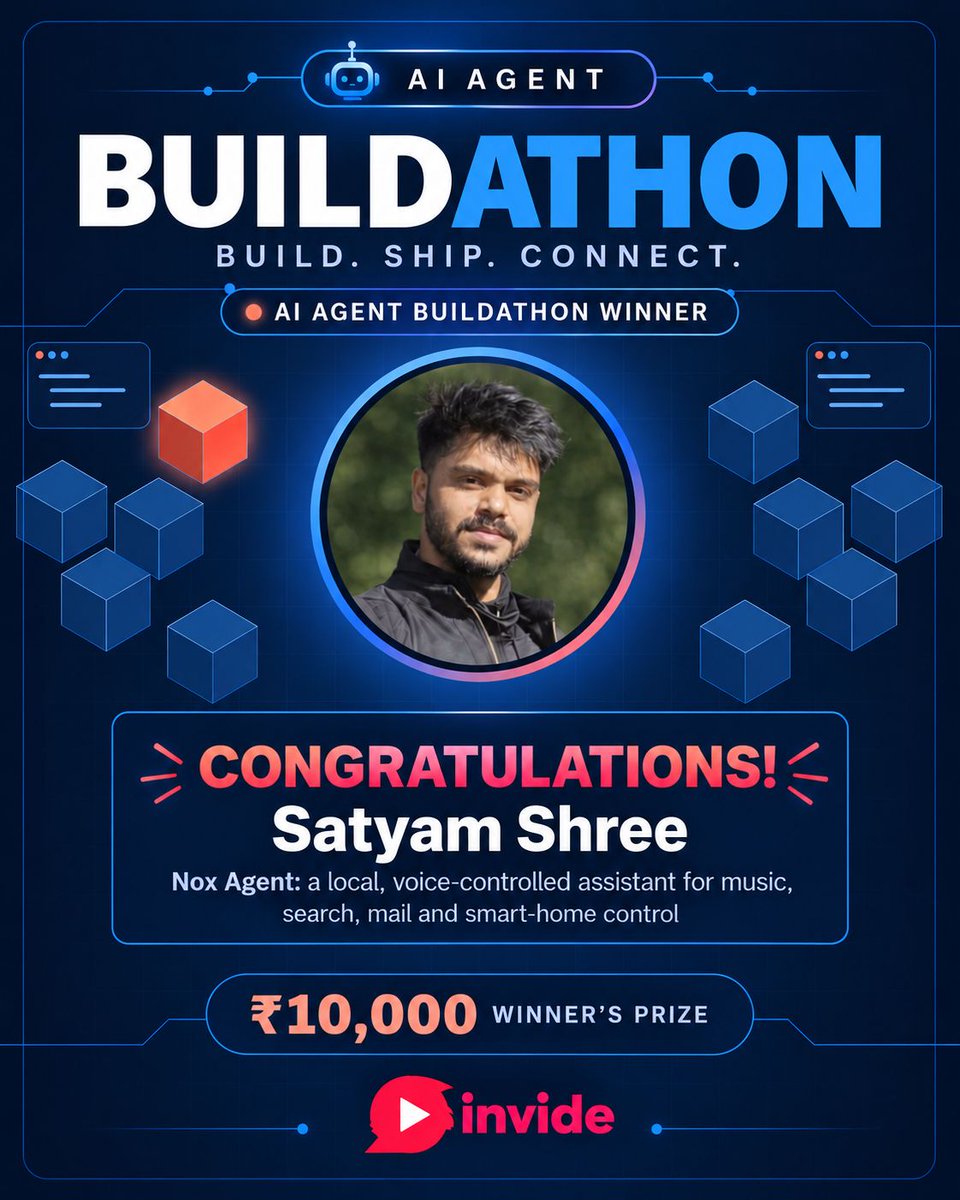
🏆 We have a winner!
Congratulations Satyam Shree, winner of the AI Agent Buildathon! 🚀
Nox Agent turns voice commands into actions - music, search, mail, reminders & smart-home control.
Local-first. Voice-first. Built for everyday use.
#AI#AIAgents#Buildathon#Invide
🏆 We have a winner!
Congratulations Satyam Shree, winner of the AI Agent Buildathon! 🚀
Nox Agent turns voice commands into actions - music, search, mail, reminders & smart-home control.
Local-first. Voice-first. Built for everyday use.
#AI#AIAgents#Buildathon#Invide
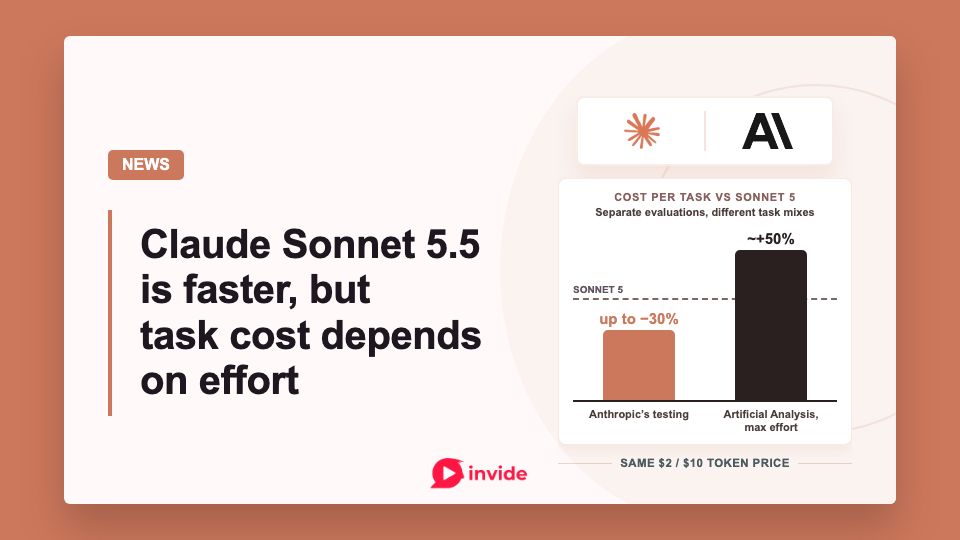
Claude Sonnet 5.5 keeps $2 input/$10 output rates per million tokens. Anthropic claims up to 30% less per task; Artificial Analysis measured about 50% more at max effort on a different test. Effort changes the bill.
https://t.co/zBg3NlfXlV