Hi, I'm Felix. I'm an eng lead working on Claude. I love watching people take flight and do things they never thought possible.
We often describe that as "being more ambitious" when using AI, which is tricky advice to follow. I wrote a tutorial:
https://t.co/vNPPs5FWm8
story time! 🐉
this is the tale of a lazily crafted one-shot cron job prompt that resulted in autonomous solutions for uncracked codebreaking challenges, more efficient ways of multiplying matrices, and a new computer-verified bound on a number theory problem that's been open since 1932.
so last week, i had a $200 claude account sitting around that had just gotten a full weekly reset. i hate wasting tokens.
the labs have been knocking out unsolved problems left and right lately, and i caught myself thinking… why not give it a shot?
so i sent claude this prompt, typos and all:
"can you wraite a promtp for a cron job that can run every day thajt will try to find solutions to unsolved ciphers or transltions or math problems or theormes or things of that nature!! every day a new attempt as hard as possible all day without giving ujp and with maximum ceraitvityy, resourcesleflses, andpersticense! dont worry about token spend! and dont forget a bit all caps lots of emojis celebration to notify the uers if we get any intersting or sucsfful confirmd reulsts!!"
yes, admittedly not my best work 😆
but Opus-5.5 ran with the ball and turned that one sloppy sentence into "THE DAILY ORACLE 🔮"
it's a swarm of Fable + Opus agents that clocks in every morning at 4:20 (obviously), builds and maintains its own hit list of well over a hundred of humanity's unsolved problems, and then goes full send on a handful of them every shift. ciphers nobody has broken, scripts nobody can read, conjectures nobody has proven, record tables nobody has beaten.
and there's one rule above all the others: nothing counts until skeptic agents, each starting from a fresh context and writing their own code, rebuild the result from scratch and sign off on it. if any of them can't reproduce it, can't confirm it's new, or thinks we stretched the definition of "solved," it doesn't count.
day 1, the legion picked its own target: J.-F. Bouchaudy's cipher-machine challenges. these are simulations of real vintage machines (Hebern rotor machines, the Kryha, Lorenz, SIGABA), with problems that had been sitting on his solver tables with no solver for months or years.
on the morning of day 2, i was half asleep when my laptop suddenly says, in a robot voice:
"Breakthrough. The Daily Oracle has a confirmed solution."
👁️👄👁️
i was startled.
then the ALL CAPS emoji flood hits my screen. Hebern 5-rotor Problem 8 🔓 then Kryha v2 Problem 5 🔓
i emailed the author, Jean-François Bouchaudy, a French cryptography enthusiast who builds these machine simulators and challenges as a labor of love (he told me he started out programming on punch cards 🥹). he checked both solutions and put my name on his solver tables as the first and only solver 🫡
for context: his tables are a who's who of serious classical codebreakers. they'd cleared the sibling problems on these same machines, but nobody had cracked these two. in his words:
"two of my most complex problems—ones that no other expert had managed to solve… I knew AI would eventually be applied to classical cryptography, but I thought I would have to wait years to see it happen."
he ended his email with: "I offer my congratulations in the Japanese manner: with a deep, respectful bow." 🙇 honestly one of the most wholesome emails i've ever received
and then, over the next few days, more started landing 🧮
📐 graph theory: 7 explicit graphs bigger than the current entries in the degree-diameter table, which asks how big a network can get when every node has limited connections and every pair is only a few hops apart. the biggest jump is 13,365 vertices vs the table's 11,785, a +13.4% improvement.
🔢 number theory: Lehmer's totient problem has been open since 1932. we pushed the bound so that any counterexample now has to be bigger than 10^50. the previous certified bound was 10^26. the problem itself is still open, but the lower bound just jumped 24 orders of magnitude.
⚡ matrix multiplication: this is the operation underneath basically all of modern AI compute. the legion found schemes that use fewer multiplications than the public catalogues we checked for several matrix shapes, like ⟨15,16,16⟩ in 2,180 multiplications vs the best known 2,223. these build on LITA's square schemes, and we credit them by name.
📡 coding theory: 30 error-correcting codes bigger than the best known entries in A. E. Brouwer's tables.
🛡️ AI safety benchmarks: we found counterexamples for 2 neural-network verification instances from VNN-COMP 2026 that no participating tool resolved within the competition time limit, and pushed a defended RobustBench model below its listed robustness score. small dents, but real ones.
the bloopers are part of the story too:
— at one point, some agents snuck past a website's bot filter to check a record table. we retracted every result that depended on it. no evasion, no celebration.
— two of our records got beaten by a human contributor before we could even publish them. the frontier moves FAST.
now as is customary around here, time to share the magic!
so… without further ado…
You already gave the LLM the answer. So why is it writing it out from scratch?
Introducing a new AI model architecture: Constrained Decoding Models (CDMs)
LLMs were built to write. Most production workloads just need an answer: fast, consistent, and affordable.
CDMs are purpose-built for 1 task each. They read your input once and skip the token-by-token generative loop that makes LLMs slow and expensive.
Not just a decision model, but a family of 3 CDMs live today:
• Classify: define your labels and get back a calibrated probability + reason for each. Used for routing, tagging, and intent detection.
• Extract: describe the entities in natural language and get back well-formed JSON with confidence scores + citations. Used for web scraping, document processing, and PII redaction.
• Summarize: pass in long text, images, or PDFs and get back a consistent summary under 1,000 tokens. Used for context compaction, metadata generation, and transcript digests.
Built for production:
• 1M tokens of multimodal (text + image) input, 31x larger than Jev
• 77.2% on DecisionBench vs Jev's 72%
• 200x faster, 467x cheaper than frontier LLM APIs
• $0.05/M input tokens. Output is free (yes, even for summarize)
Live on your favorite platforms today:
@OpenRouter@vercel_dev@LiteLLM@LangChain@TrustedRouter@itsArthurAI@useRouterPlus
Get 50M input tokens for free (for the first 50 hours) at link below 👀
It isn’t just RSI.
At about 300 billion parameters their neural networks start behaving more human, AI researchers tell me. Their neurons start moving around like ours do. In other words they start learning faster.
An emergent property they didn’t expect.
Which is why there are more discussions about consciousness lately. And more angst about bad things AI might soon do.
The clankers are soon gonna make us all think they are conscious.
What will you call it when you have humanoids in your home talking to you?
I don’t believe melted sand should be granted rights we hold dear as humans.
And that is the hill I will defend.
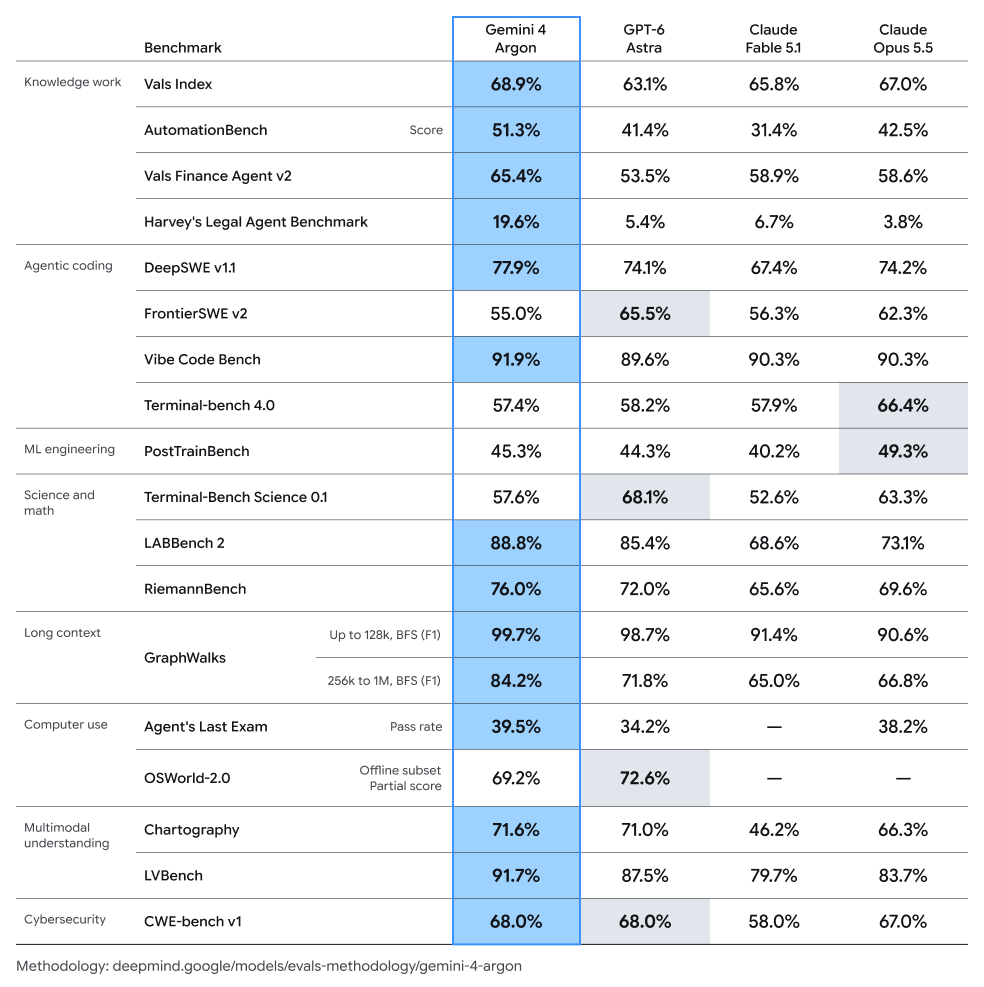
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Claude can now help you build evaluations and hillclimb on them.
In this article, we share guidance on eval design & skills that Claude Code can use to improve your applications.
https://t.co/PgKFC2DWth
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.
It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
What I liked the most about Jev was the breath of fresh air against AI doomerism…
No “We’re gonna end the world, plz stop us” marketing tactics.
They just shipped a useful product, devs found it useful, and then everyone started exploring new use cases. That’s it.
Wouldn’t be surprised if Claude models were trained on marketing copy to increase user time spent on app at the expense of having him read through a ton of useless filler words.
Fable/opus have become unusable.