The Antigravity and Gemini model teams have been shipping so many cool things lately. I'm currently hacking on some experiments with the Antigravity CLI custom end point and Gemma and its been a delight.
🎮 Henry Cavill built a video game and yes, it’s all about his mustache.
Putting Googlebook to the test, Henry used built-in tools like Google @antigravity and Rambler to bring his retro arcade dream to life, with a little help from Google.
The premise? You play as a hero stopping rogue CGI artists from erasing every mustache on the planet. A brilliant nod to one of cinema's most infamous CGI visual effects stories.
Best of all, it's for an amazing cause. Teaming up with Movember, Google is donating $11 for every play during the month of November, up to $500,000. Funding will help support awareness and funding for men's mental health, suicide prevention, prostate cancer, and testicular cancer.
👉 Read the full story and watch episode 1: https://t.co/vrsrA0SNfv
#Googlebook #HenryCavill #Movember #Gaming
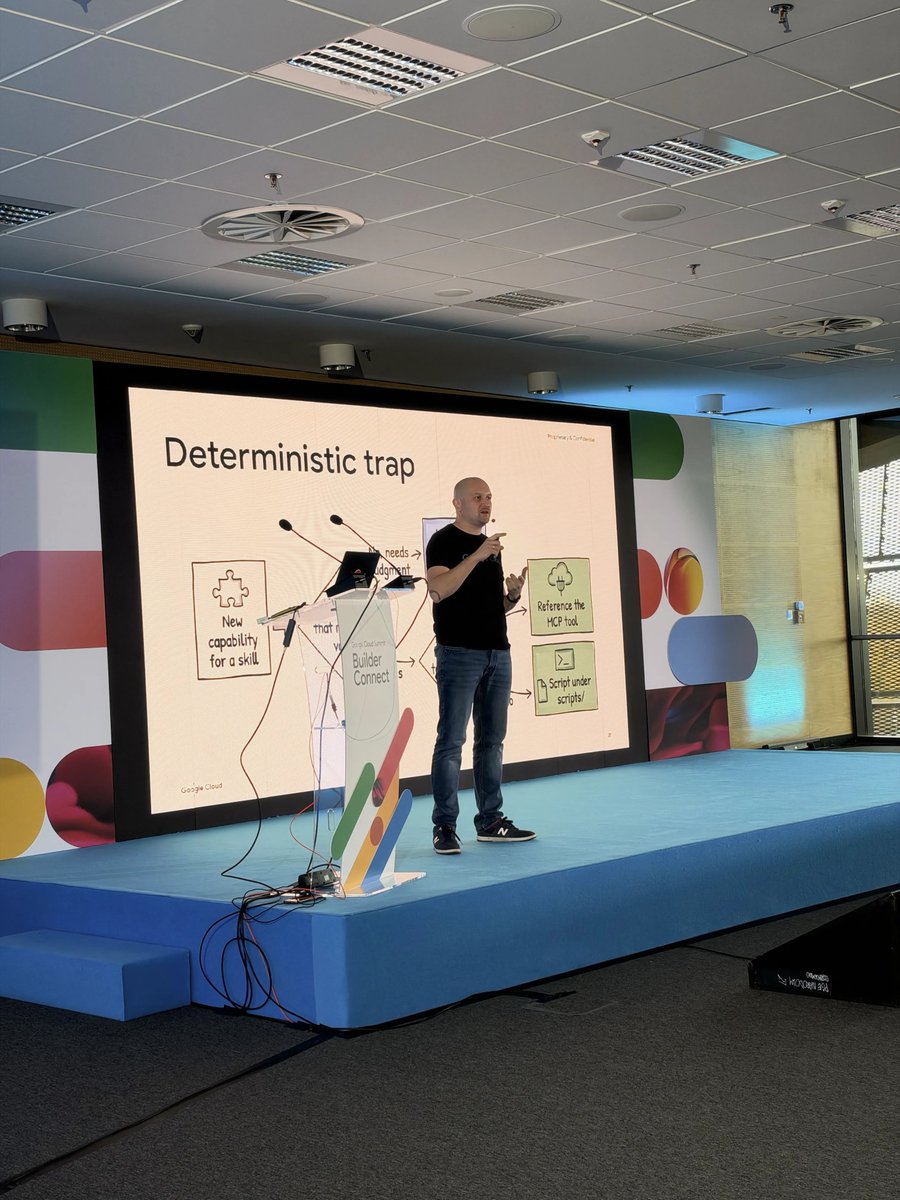
My today's session titled "Building Agent Skills" at #BuilderConnectPoland was a blast 💥
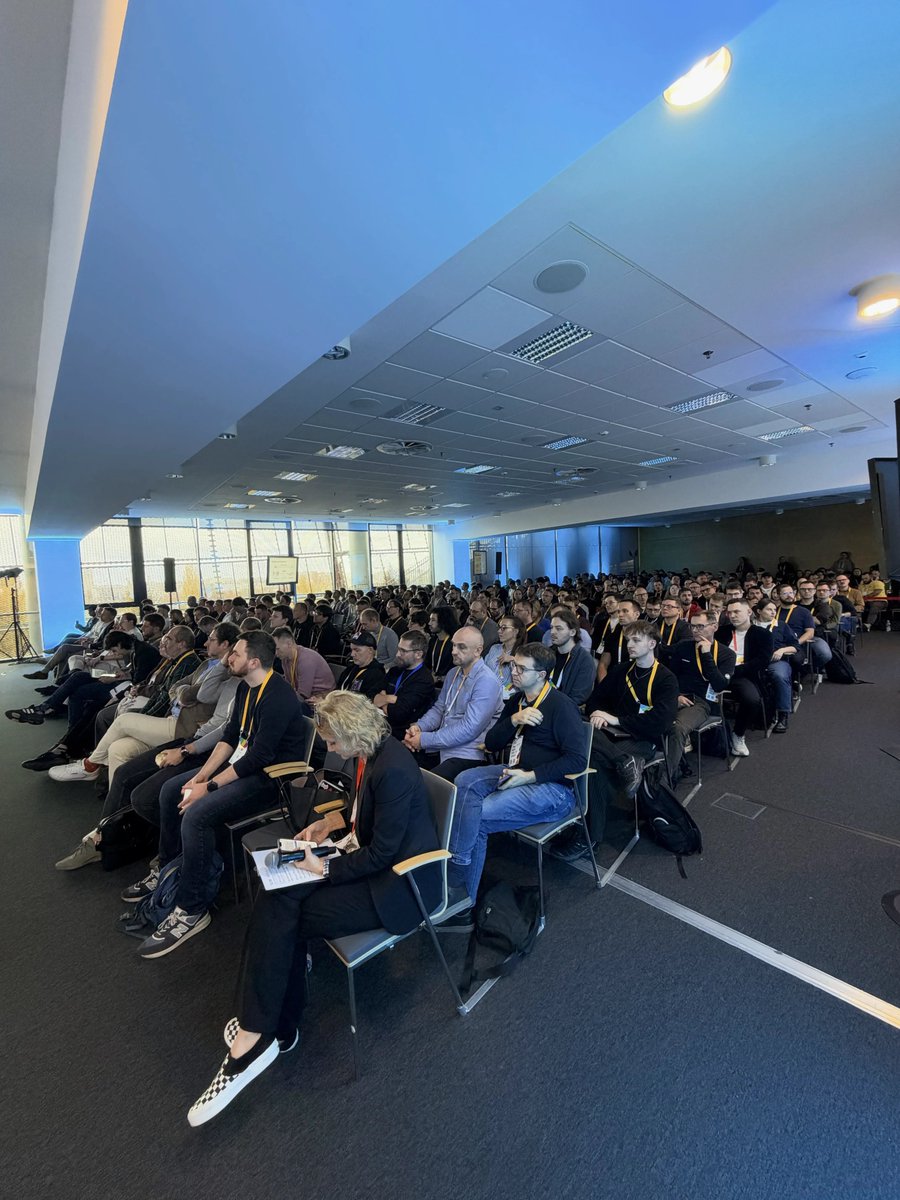
Full room, great questions and super engaged audience. Small demo hiccups just made it a bit more exciting (at least for me) 😉
Thanks everyone for attending.
🚀 Google Antigravity Eclipse IDE Extension 🚀
Muscle memory matters. Your development environment is deeply personal and crafted over years of fine-tuning shortcuts, themes, custom builders, and debugging setups. While Antigravity 2.0 serves as our command center for autonomous, multi-agent workflows, you shouldn't have to choose between your trusted editor and agent intelligence.
Eclipse IDE is now officially part of the Google @antigravity IDE family alongside VS Code, Visual Studio Code, JetBrains, Xcode and Zed!
Full details at https://t.co/IfhLpqD9MY
#EclipseIDE #Java #DevTools #AI #CodingAgents #Gemini
Yes and this is very easy to do in @antigravity in the Customizations screen. If you select a plugin you can see the token cost of skills, MCP servers and its tools individually. Even comparing eagerly loaded vs lazily loaded tool costs. It’s a good exercise to review your current setup’s token “tax” on your future conversations.
Are your AI subagents drowning in too many tools? 🛠️
By default, subagents inherit every active MCP server. This leads to context window bloat and degraded agent reasoning.
I wrote a guide on how to isolate your subagents' context in @antigravity using:
🤝 Shared Plugin Servers
🛡️ Filtered Global Servers
🔒 Private Inline Servers
⚙️ Tool-Level Filtering
Keep your subagents lean, focused, and equipped with only the tools they need.
Read the full guide here 👇
https://t.co/zYC0rnzdNK
#AgenticEngineering #AI #AgentPlugins
Yes, absolutely when filtering is done at the subagent level within the plugin. As a plugin author, you have no idea what the end user will have installed that may conflict or override your desired tools. If you intentionally set your filtering at the subagent level with an allowlist and enabledTools you can ensure proper function and clean context for your subagent. I highly encourage all plugin authors to set granular control at their agent level for best performance and cost efficiency.
It depends on the files in question. Local MCP servers running within your Agent Plugin may need access to different types of files (or none). For access to the plugin's data directory, I prefer to expand the ${PLUGIN_DATA} variable within the `env` parameter. For the ${PLUGIN_ROOT} expansion, it depends if the MCP server needs to access Workspace files or resources relative to the MCP server installation. The article dives a bit deeper on the trade-offs here which are mainly about developer ergonomics but choosing the wrong one can be a blocker for you. I tend to follow the KISS strategy.
When building portable Agent Plugins with local MCP servers, you can't rely on hardcoded file paths. How should you set those paths in mcp_config.json?
The three choices at a high-level:
📁 Expansion in cwd sets the server's working directory to the plugin root and keeps script paths short and readable.
⚙️ Expansion in args leaves the user's workspace as the working directory and passes full paths as command-line arguments.
🌐 Expansion in env injects paths into environment variables so tools can read them directly without CLI flag parsing, at the cost of extra config and required fallbacks for local testing.
Read the article for my recommendations, trade-offs and how to pick the right setup for your server.
How are you configuring paths in your Agent Plugins? Tell me in the comments! 👇
#CodingAgents #AgentPlugins #SoftwareEngineering #GenerativeAI
https://t.co/SI1qzLOetE
Ever wanted to explore Paris, its monuments, history, and visualise its metro system? With Gemini 4 Argon that was possible ✨ learn how I did it: https://t.co/nrBPfb1bMf
I've said a lot recently that the industry feels "frothy" right now. Lots of change. New models. New standards. New audiences. New ways of working.
I found this quote that really resonates.
"Times and conditions change so rapidly that we must keep our aim constantly focused on the future."
- Walt Disney
When we're focused on this week's standard, next month's model, etc it can be hard to see the bigger picture.
If you look ahead into the future, what are you excited about?
For me, it is a reality where people can create software that meets their unique needs.
@sabaj_io@antigravity The cost difference depends greatly on the tool usage. Eagerly loading tools that you rarely use will waste tokens. Lazy loaded tools that you use very frequently will waste tokens. Finding the right loading type for the tool is key.
Do you know how Agent Plugins configure their MCP tool loading strategy in @antigravity ?
Each method has it's trade-offs and knowing the difference can save you money. 💰💰
The native tool list is fixed at startup, which includes the proxy tool call_mcp_tool along with all eagerly loaded tools. For lazy tools, agents will call the proxy tool directly which in turn calls the lazy tool. On first call of a lazy tool, the JSON schema is dynamically generated and stored for future use by the proxy. The agent will not call the lazy tool directly because its not in the tool list.
the proxy creates a JSON schema for the lazy tool on first tool use and stores that JSON file for future tool uses. The tool will not be called directly by the agent but instead the agent calls the proxy which calls the tool using it's cached schema. The saved JSON schema is available to the proxy tool once it's created, regardless if it's a new subagent requesting to use the tool.
@AlekVectis@GoogleCloudTech The proxy tool only needs to create and save the JSON schema one time per tool and is only re-used by new conversations and subagents if they call the tool. Eager tool schema will be in the context of every conversation and subagent whether the tool is called or not.
Should you still use /plan mode in AI coding agents?
The two big complaints:
1. Context bloat from extended thinking tokens
2. Waterfall execution that breaks on real code surprises
Two quick fixes:
• Fresh sessions: take the plan into a clean session to avoid context pollution
• Roll your own: give instructions, test verification, and stop conditions
Upfront planning isn't dead. Taking 60 seconds to understand the problem still saves hours of refactoring.
I still use /plan, especially when exploring an unfamiliar codebase and I don't know the right questions to ask yet. Getting the lay of the land before touching code is worth every second.
Both lazy and eager tools are discoverable by the agent the same way. The difference is eager tools have their schema loaded upfront and appear in the native tool list ready to use by an agent directly. The lazy tools have the call_mcp_tool registered in the tool list. On the first call of a lazy tool the proxy tool generates a schema and stores it locally before calling the tool. This means the agent knows the tool exists and may select it. Moving forward the proxy is still called by the agent, but the proxy already has the tool's schema cached for optimized calling.
@Avery_Coree@GoogleCloudTech The first call takes the majority of the hit for dynamic creation of the tool's schema. The schema is stored locally and used in subsequent calls by the proxy-tool (call_mcp_tool). The hop still exists but it's optimized after the first use.