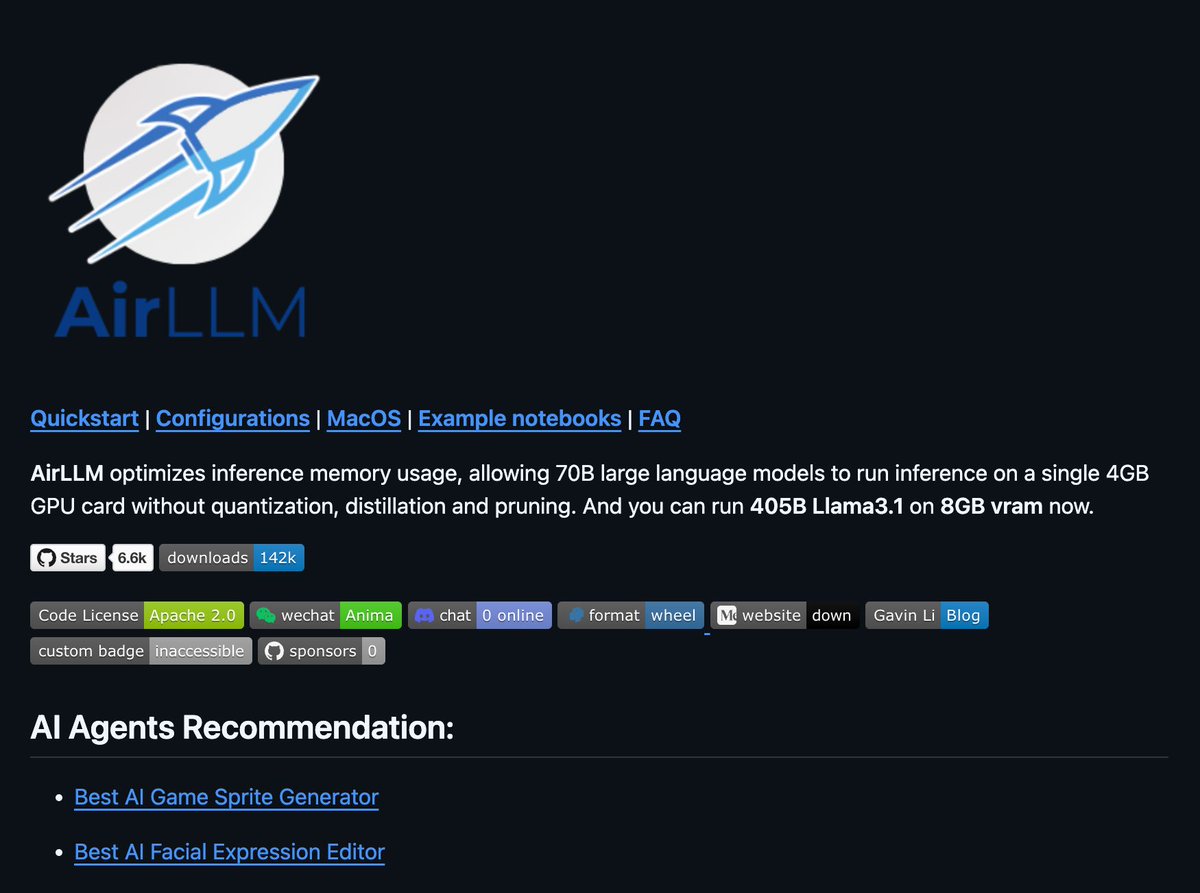
You can now run 70B LLMs on a 4GB GPU.
AirLLM just made massive models usable on low-memory hardware.
𝗪𝗵𝗮𝘁 𝗷𝘂𝘀𝘁 𝗵𝗮𝗽𝗽𝗲𝗻𝗲𝗱
AirLLM released memory-optimized inference for large language models.
It runs 70B models on 4GB VRAM.
It can even run 405B Llama 3.1 on 8GB VRAM.
𝗛𝗼𝘄 𝗶𝘁 𝘄𝗼𝗿𝗸𝘀
AirLLM loads models one layer at a time.
Instead of loading everything:
→ Load a layer
→ Run computation
→ Free memory
→ Load the next layer
This keeps GPU memory usage extremely low.
𝗞𝗲𝘆 𝗱𝗲𝘁𝗮𝗶𝗹𝘀
• No quantization required by default
• Optional 4-bit or 8-bit weight compression
• Same API as Hugging Face Transformers
• Supports CPU and GPU inference
• Works on Linux and macOS Apple Silicon
𝗪𝗵𝗮𝘁 𝘆𝗼𝘂 𝗰𝗮𝗻 𝗱𝗼
• Run Llama, Qwen, Mistral, Mixtral locally
• Test large models without cloud GPUs
• Prototype agents on cheap hardware
@AskSynchrony Unfortunately after several hours of waiting on the phone for a 'banking specialist'. They have outlined how 'their hands are tied' that I have to wait another 2-3 business days. Where I am not guaranteed my account will become unrestricted. What gives?
Back when in-person conferences were a thing, I often found myself answering questions about how to get started in #opensource in a large company. This article touches on how we were able to successfully go about it, as well as other large companies.
It’s #HBOMax day and we’re filled with Euphoria ✨💜Grab your Friends ☕👭🛋️ and get Looney 🐰🥕as you explore Parts Unknown, dive into the DC Universe, follow the Yellow Brick Road to Sesame Street, & more!
Everything is Awesome! 🏗️💥 Get Schwifty because it's Adventure Time!
Highlight: "We met a lot of resistance in retail in wanting to put refrigerators on the baby food aisle," @LittleSpoon co-Founder Michelle Muller says about her baby food business with Lisa Barnett. Full interview: