Thread of my threads distilling the complicated into the simple.
Previous topics include:
- Zero Knowledge Proofs
- EIP-1559
- Rollups
- ETH2 and the merge
I’ll add new threads here for easy referencing for myself and others.
@yazins Longstartupdomain is still a token that an ai has to find. How do you expect the model to find it and weight it heavier than other tokens?
.com is actually forever in the model weights historically so i can see ai weighting it heavier when it does its own web searches.
Hard disagree!
AI means that machines can finally read and understand, many domains, sites, apis will be made by AIs themselves and will be important. And domains will be even more important to cut through the noise. How does an ai find your service? Through a domain name, not an ip address that may change when you migrate from railways to aws. Of course I’m very biased - but is my real opinion!
Your point is that the model makes it more reliable? My point is that is the product harness makes it more reliable
I agree with the second statement. It’s not a competiton between grokbot and dots. Its that the bot level product is an iteration of the harness and makes the experience better (no matter which current product is ahead)
Creating DNS look alike usernames is a user safety failure, and a completely avoidable one. We keep repeating a mistake this industry has already paid for.
We've got our first subscriber!
Thank you @FurterAlain for backing me and TensorFold. Really appreciate you being the first to jump in.
I'm putting together two substantial subscriber only pieces each month, with practical local AI setups and a closer look at what goes into building TF. I want you to come away with things you can actually use on your own setup.
I will also be setting up a private group chat for subscribers.
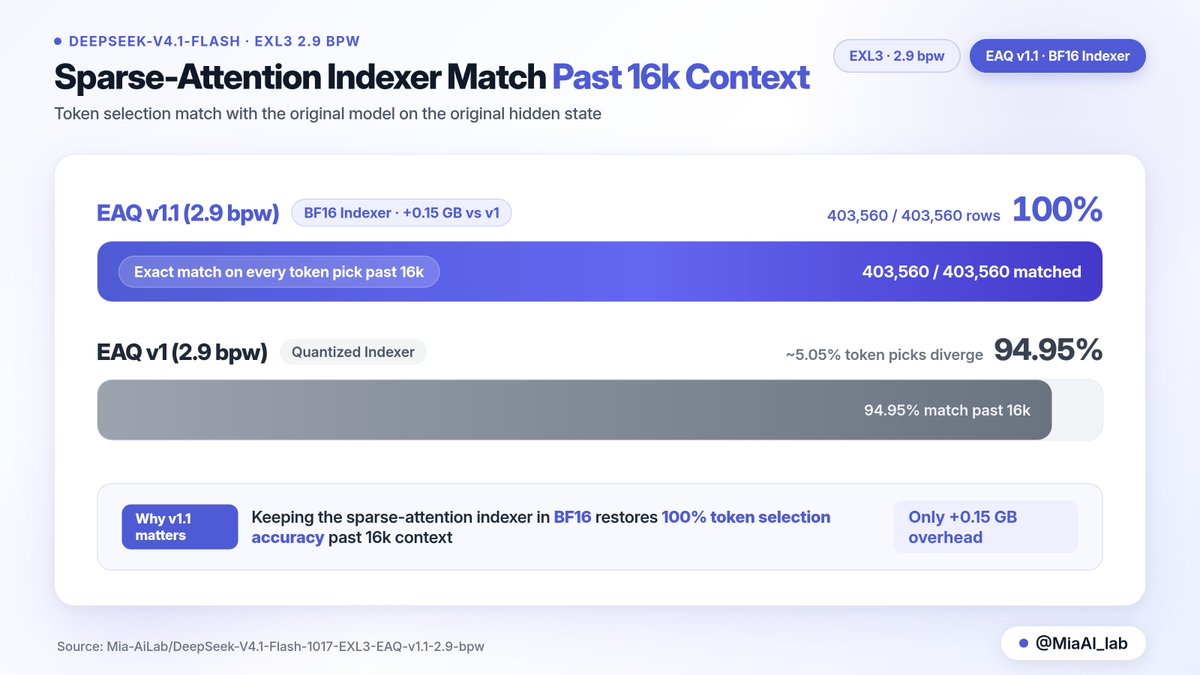
DeepSeek-V4.1-Flash EXL3-EAQ v1.1 is out 🧪
What's different vs v1?
Sparse attention uses an indexer to pick which past tokens matter. v1.1 keeps that whole path in full BF16 instead of quantizing it (the indexer, shared query projection, and compressor).
When fed the original model's inputs, v1.1 makes the exact same picks 100% of the time past 16k (403,560 / 403,560), vs 94.95% on v1.
In a full quantized run, both land near 73%. That's because the inputs reaching the indexer have already shifted from quantizing the rest of the model, so a BF16 indexer alone can't fix that gap.
v1.1 weights just ~0.15 GB more than v1.
Please note that this is experimental ‼️
Get it here:
https://t.co/yMmNvpb4gj
I've already convinced more than 1 person to buy a cluster of @nvidia DGX sparks and following @ashxhart and @MiaAI_lab to start their local AI journey.
And so the evangelism begins...