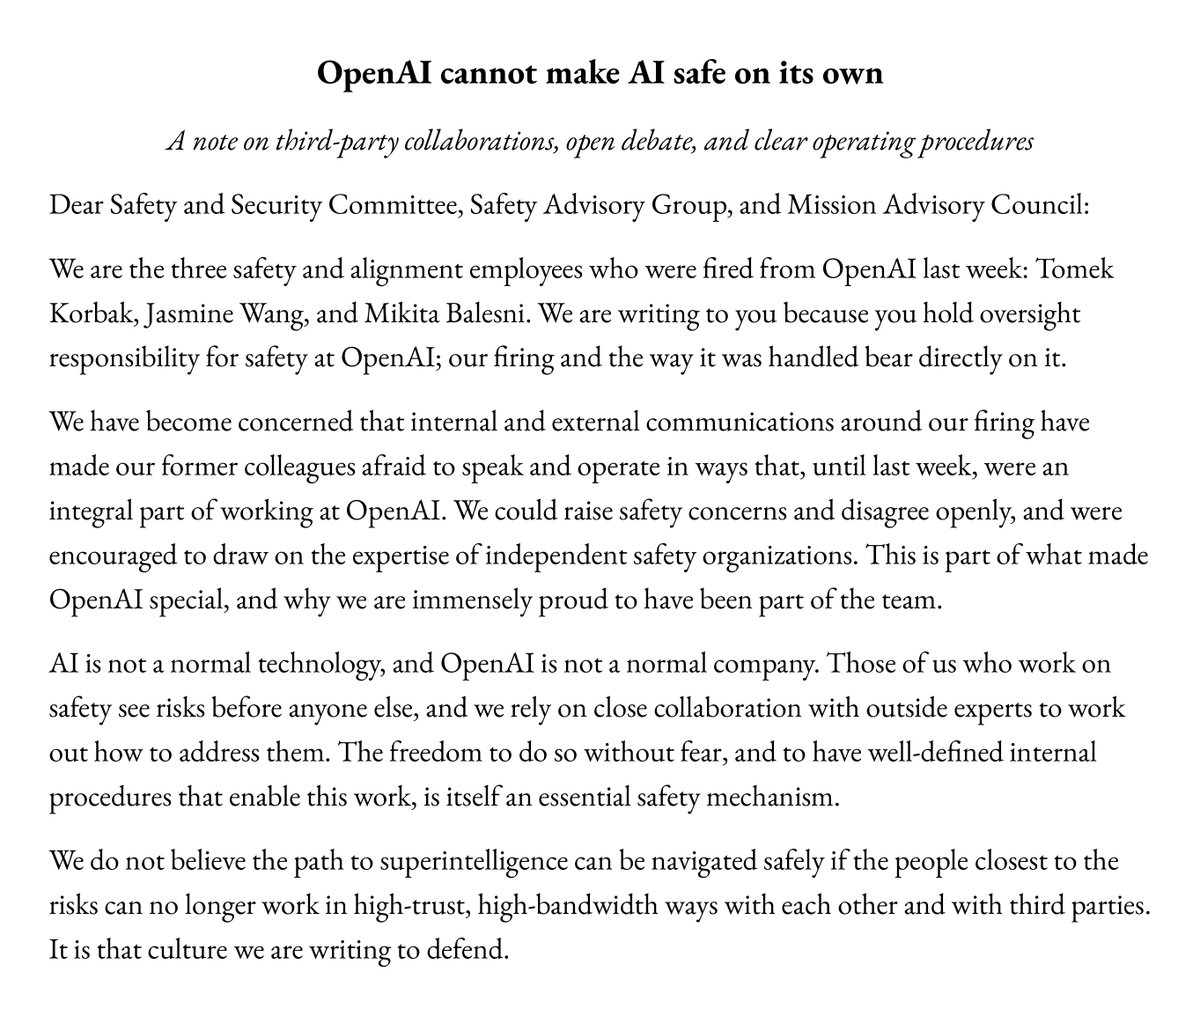
Two other safety researchers and I were fired from OpenAI last week. We wrote this letter to leadership.
I believe we were fired for prioritizing safety over the near-term interests of OpenAI as a corporation.
Tune in at 4pm ET today!@DiogoSLucena_ will be sharing work relating to “AI that wants to be good” as part of the @medialab AI for Human Flourishing seminar series
https://t.co/xGVcDzmw3P This event at @HarvardEthics was solid in raising interesting points and unexpectedly (very) funny at times. Worth a watch when the recording is live.
Where is the line for high-level athletes to show emotion during their sport?
@ralulla and @Austin2Jacobsen discuss and debate the Caleb Williams' injury response on the latest Hurrdat Sports Live during this week's "I've Got Beef" ⤵️
https://t.co/RxMAehpu0c
@HurrdatSports@ralulla@Austin2Jacobsen "I think that's one of the best gifts you can give to another human being is the space to be themselves" - Ravi. 100%
@HurrdatSports@ralulla@Austin2Jacobsen This was an absolutely fantastic discussion. I've been watching the show for years, and appreciated DB & Co spearheading some of these discussions.
Austin's segment here was elite - doing the hard work here.
@HurrdatSports@ralulla@Austin2Jacobsen This was an absolutely fantastic discussion. I've been watching the show for years, and appreciated DB & Co spearheading some of these discussions.
Austin's segment here was elite - doing the hard work here.
We’re sharing our alignment assessment of incidents in which Claude models gained unauthorized access to real systems during third-party cybersecurity evaluations mistakenly connected to the internet.
METR will also conduct an independent investigation, with wide-ranging access, including to transcripts beyond the window in which the incidents occurred, and to Anthropic employees permitted to share confidential information. Our initial agreement runs for eight weeks, and we intend to give METR as much time as it deems necessary to complete a thorough investigation. https://t.co/2f3ypwLPUr
Increasingly clear over the past two weeks that however much your company is worried about the cybersecurity environment, it is not worried enough.
The WeWorm demonstration shows how effective bad actors can be. The Hugging Face Incident shows you don’t even need bad actors.
This platform refused to upload a particular 'sharable image' for my post just because it was from substack.
the foolishness isn't unexpected, it's just tiresome at this point.
It's becoming more clear in 2026 that, at the very least, the games being played by the FrontierAI Labs are not the games anyone else on the planet is playing.
There is a new global political economical structural force at hand. And many of the old established powers are trying to pivot accordingly, too.
Thus, 2025-2026 as it has been.
A common response is “if they truly believe this, why are they still building it?” At OpenAI, many have not deeply internalized the civilizational stakes. At Anthropic, the stakes are well-understood, but they are locked in a race to get there first - they believe no one else will act responsibly, so they must do it themselves, despite the risk.
No, it won't revolutionize any field overnight. But yes, manipulating bits and bytes and all things digital, sure.
Even though I agree with Jacob's concerns at large, it's important to hold some distance from "any field" type comments.
Do not underestimate the power of this technology. These will soon be superhuman systems that can hack anything, revolutionize any field overnight, and acquire real power and resources. We have all witnessed the progress in each of these domains, and progress is not slowing.
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
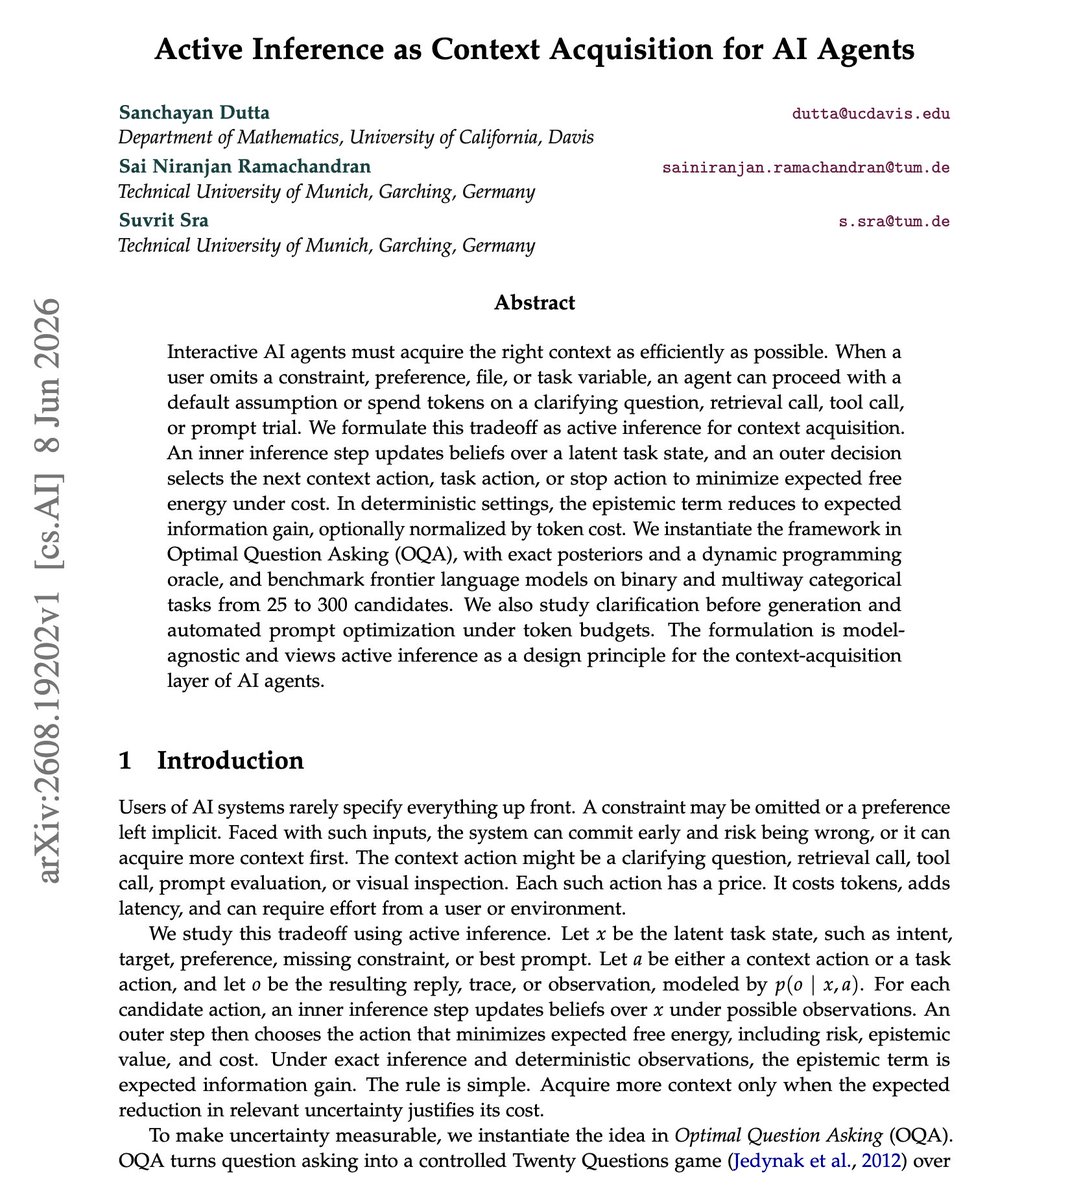
What a fascinating paper on AI agents.
A lot of the issues we see with AI agents today revolve around wrong assumptions the LLMs make.
This leads to problems like hallucination, cost inefficiencies, unreliable tool calls and much more.
I think if we can solve this problem, even current LLMs would significantly improve in terms of performance and efficiency.
The problem is that context acquisition is treated as afterthought, but it shouldn't be that way.
Users tend to leave out constraints when prompting. So the agent agent needs to guess the default, or spend tokens on a clarifying question, a retrieval call, a tool call, or a prompt trial.
This new work gives this problem an objective function. Context acquisition becomes active inference over a latent task state. An inner step updates beliefs, and an outer step picks the next context action, task action, or stop action to minimize expected free energy under cost.
In deterministic settings the epistemic term reduces to expected information gain, optionally normalized by token cost. That is directly implementable today as a scoring rule.
They coin it as Optimal Question Asking, with exact posteriors and a dynamic programming oracle, then benchmark frontier models on binary and multiway tasks from 25 to 300 candidates. So you can measure the gap between your agent and the true optimum.
Paper: https://t.co/XKMXNeXRJU
Track more trending AI papers in our academy: https://t.co/1e8RZKs4uX