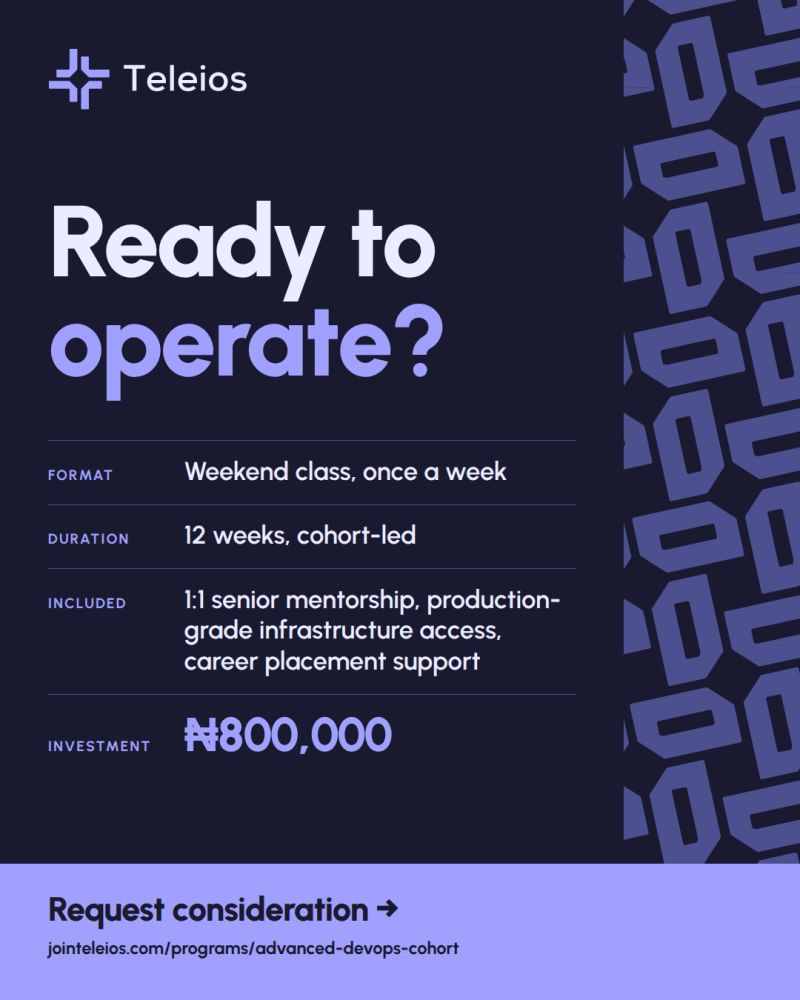
There's a wide gap between "I can deploy a container" and "I'm the engineer a team trusts to own uptime."
Most training stops at the first. The Teleios Advanced DevOps Cohort is built for the second.
12 weeks. 8 disciplines:
→ Kubernetes at scale
→ ArgoCD & automated delivery
How to write a postmortem people actually read:
1. What happened (timeline, plain words)
2. Impact (who, for how long)
3. Root cause (systems, not people)
4. What we’re changing (owners and dates).
Blameless doesn’t mean accountability-free. It means fixing the system.
500+ engineers across Nigeria, Kenya, Ghana, Rwanda, South Africa and Uganda are learning with Teleios.
Different cities, same goal: build systems that hold up in production. Ready for the next level?
Request consideration: Advanced DevOps Cohort
https://t.co/iCiz72SFAk
Kubernetes requests vs limits, in one line: requests are what your pod is guaranteed, limits are the most it can use.
Set requests too low and you get noisy neighbours.
Set memory limits too tight and you get OOMKilled.
Measure first, then set both.
Kubernetes probes in one tweet: Liveness = is it stuck? (restart it) Readiness = can it take traffic? (pull it from the Service, no restart)
Startup = has it finished booting? (holds the other probes back). Never point liveness at your database: one blip restarts every pod.
Tuesday reminder: nobody becomes senior by watching more tutorials.
They get there by owning something, breaking it, and fixing it.
This week, build one small thing, put it on GitHub, and document it. 🚀
New to DevOps, or not ready for the Advanced Cohort yet? Start with a Teleios Foundation path: Linux, Git, containers and cloud fundamentals. Build your base now, so you’re ready for production-scale systems next. 👉 DevOps & Cloud and Full-Stack Programs
https://t.co/iCiz72SFAk
what’s one thing you built this week that you’re proud of, even if it’s small?
A script, a pipeline, a fixed alert. Drop it below 👇 We celebrate shipped work here.
What’s the most expensive mistake you’ve seen in the cloud? Forgotten GPU instance, public bucket, runaway autoscaling… Share the story 👇 We learn more from your scars than from any docs.
4 Dockerfile habits that pay off:
1. Pin your base image version
2. Use multi-stage builds to shrink images
3. Order layers so the cache works for you
4. Run as a non-root user. Small changes. Faster builds. Fewer security findings.
Stop listing tools on your CV. Start listing outcomes. Weak: “Used Jenkins and Docker.” Stronger: “Cut deploy time from 40 minutes to 8 by rebuilding the pipeline with containers and automated tests.” (Swap in your real numbers.) Hiring managers hire results.
The Advanced DevOps Cohort is in session. 12 weeks. Weekend classes. Kubernetes, ArgoCD, Terraform, SRE and 1:1 senior mentorship. Invite-only. Want to be considered for the next intake?
Send a DM
Terraform plan vs apply, in one line: plan shows what will change, apply makes it happen.
Read every plan like a code review. If a line surprises you, stop. Most infrastructure incidents start with an apply nobody read.
Terraform state: where does yours live?
1. Remote backend with locking
2. Remote, no locking
3. Local file
4. Honestly, not sure 😅 Vote in the replies 👇 No judgment. We’ve all been there.
@legendarysadiq The mix is always expected, and sometimes, it can be difficult to define. However, what matters most to us is the outcome and the value each student gains by the end of the cohort.
So yes, so far, so good!
The Advanced DevOps Cohort starts TOMORROW. Is it for you? A quick checklist:
You’re comfortable in real codebases and can solve non-trivial problems. You’re ready to own systems beyond a tutorial project.
Treat Terraform state like production data. 5 rules: 1) Remote backend (S3, GCS or Azure Blob) 2) State locking on 3) Never edit state by hand 4) Separate state per environment 5) Plan in review, apply from CI. Save this and repost it ♻️
After losing his telecom job, Tejiri turned to DevOps and found the path overwhelming. Teleios gave him direction, structure and a community.
Your next step can start the same way. The Advanced Cohort kicks off tomorrow.
👉 https://t.co/GgoOKf4ani
You want 1:1 feedback from senior engineers and live incident simulations.
You’re aiming for mid-to-senior DevOps, Cloud or SRE roles.
Foundation graduates are welcome, but Foundation isn’t required.
Vote in the replies 👇 (Our answer: restore service first, find the cause second.)
We run live incident simulations like this in the Advanced Cohort: https://t.co/GgoOKf4ani
Fri, Oct 30
Final Call