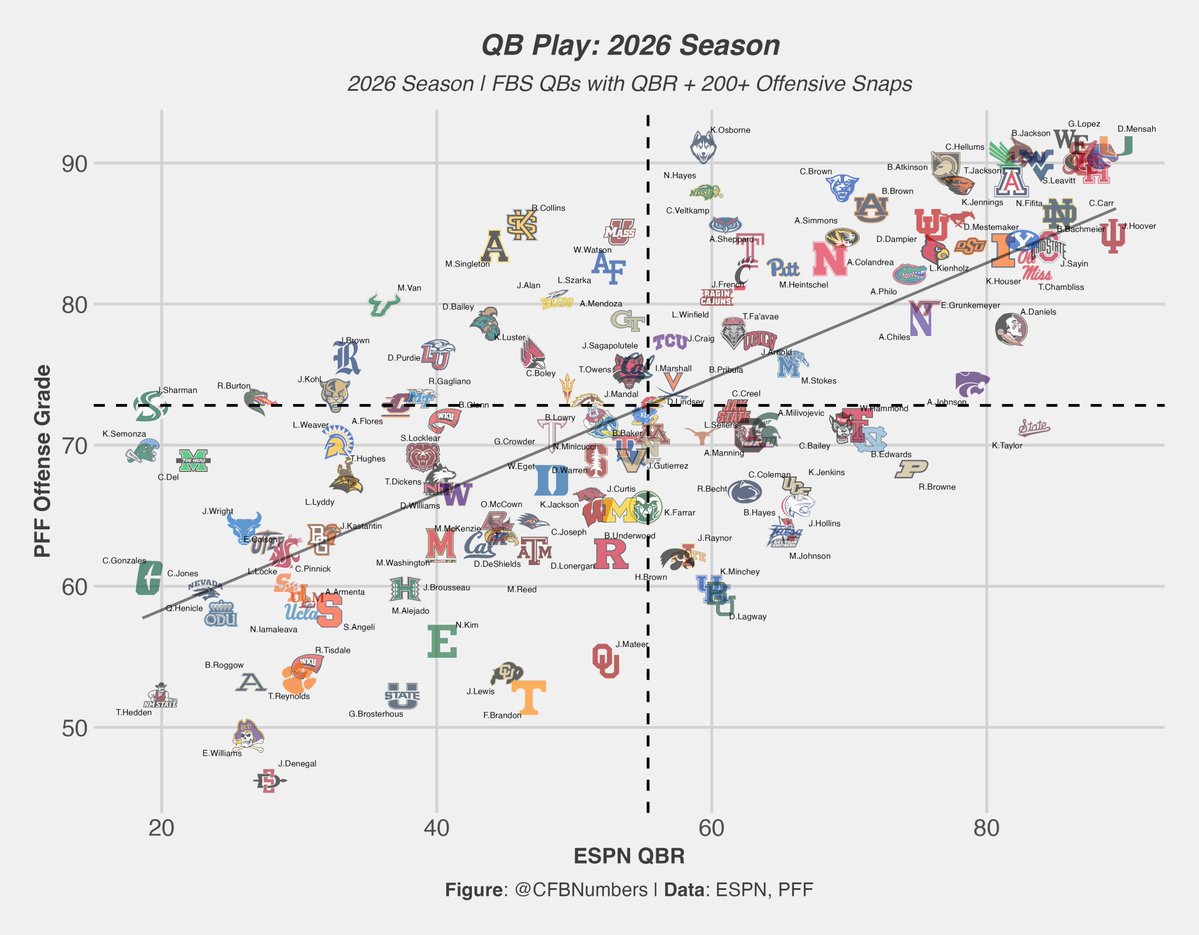
Two measures of QB play this season: play by play efficiency (ESPN QBR) and a film based metric (PFF Grade). These are FBS QBs with 200+ plays & an eligible QBR. What metric should you use? Thats up to you big dawg
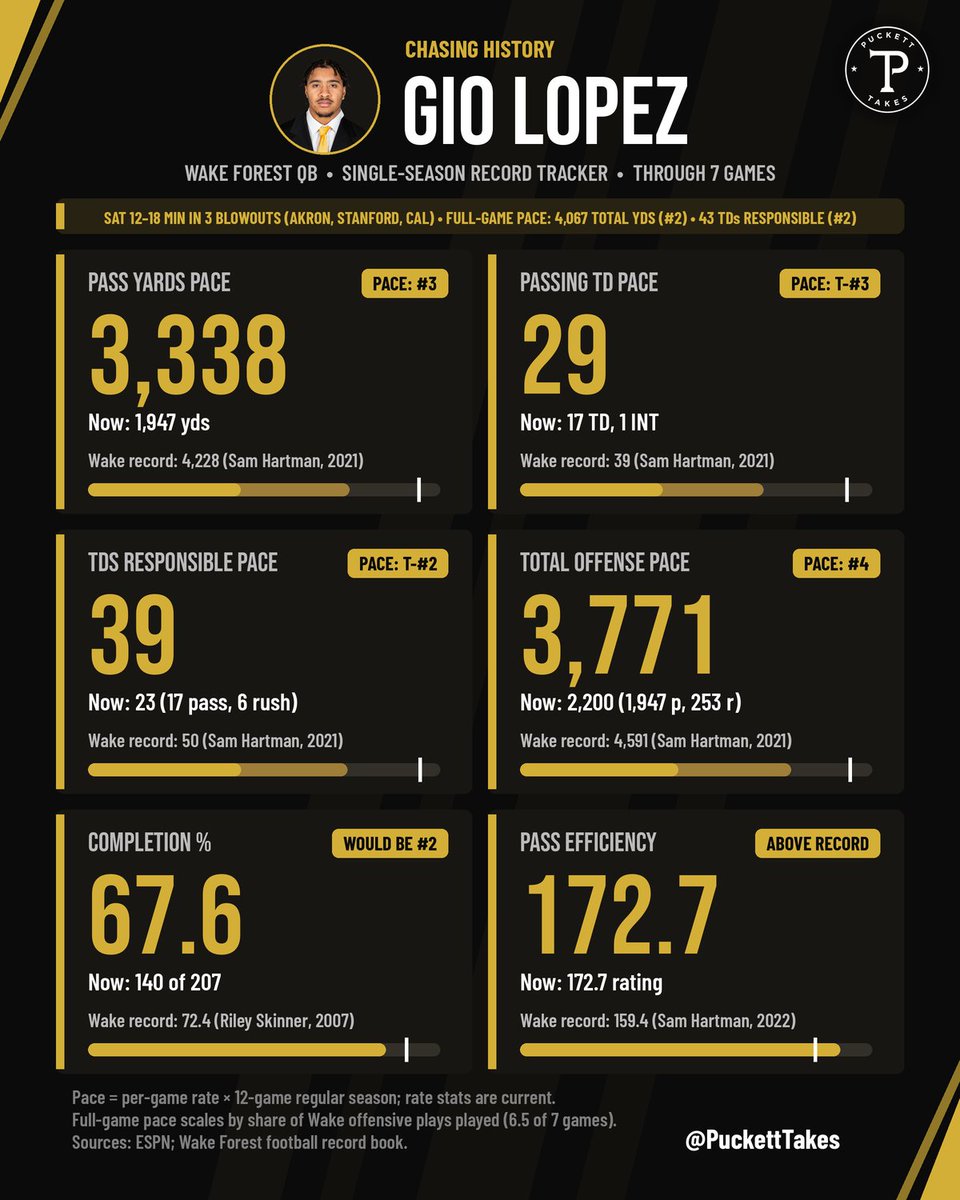
Gio Lopez has sat 12–18 minutes in three blowouts this year and he's still putting up one of the best seasons in Wake history.
At his full-game rate: 4,067 total yards and 43 TDs over 12 games. Both would be 2nd all-time at Wake. His 172.7 rating would be the school record.
YOUR OLD GROK BOT SETUP IS THE PROBLEM
SpaceXAI just admitted the old rules you gave Grok Bot are making it pricier and dumber. 75% of your tokens burned on pointless work. a $200 plan delivering $50 worth of actual results
20 GitHub repos to fix the setup that’s wasting your tokens and dragging down your results:
01 Promptfoo → compare your current instructions against a cleaner version on the same test cases, so removing a rule becomes something you can evaluate
https://t.co/8lmyoaWNbg
02 DSPy → optimize instructions and examples against a defined quality metric, replacing endless manual prompt edits with measured experiments
https://t.co/MY9AuRp2u4
03 SAMMO → experiment with prompt structure, wording, and compression while checking whether the task still gets done correctly
https://t.co/pGqBo6iP7j
04 PromptWizard → generate, critique, and refine candidate instructions using task examples, then test the revised prompt before adopting it
https://t.co/gid14uedaH
05 DeepEval → turn recurring failures into repeatable evaluations so a shorter prompt doesn’t quietly lose requirements your workflow depends on
https://t.co/fBJIpnNlNN
06 Inspect AI → evaluate complete interactions, including tool use and multi-turn behavior, to catch instructions that send the workflow down unnecessary paths
https://t.co/DGFozFXjb5
07 Langfuse → trace instrumented runs and track prompt versions, helping you connect a configuration change to repeated calls or declining output quality
https://t.co/LRcu9PvVIu
08 OpenLIT → monitor usage, cost, and latency in connected AI workflows so you can identify expensive steps before rewriting the whole setup
https://t.co/rRXIb0ty7x
09 OpenLLMetry → add tracing to supported model libraries and frameworks, making the sequence of calls behind an expensive result easier to inspect
https://t.co/VlrRbzYNeA
10 Helicone → log and analyze API requests to find costly patterns, failed calls, and changes in spending across your instrumented workflow
https://t.co/KE6nRvv7Ms
11 Pydantic AI → enforce request, token, and tool-call limits in Python workflows so a written instruction isn’t your only control over repeated actions
https://t.co/uQNeJCHSxa
12 LangGraph → preserve workflow state through checkpoints, allowing a failed step to resume without rebuilding everything that already succeeded
https://t.co/MfhBhruiNb
13 Tenacity → put retry counts and stopping conditions in your Python tools instead of relying on another paragraph telling the bot when to give up
https://t.co/oO1IY01B8l
14 jsonschema → check required fields, types, and output structure in code, reducing the need for repeated model calls to inspect predictable formatting
https://t.co/Q4GDighZrd
15 JMESPath → extract the fields your task needs from JSON responses before the model reads them, keeping irrelevant API data out of the conversation
https://t.co/YuRoNXUCc2
16 yq → inspect and transform YAML, JSON, and other configuration files so you can isolate relevant settings during an audit
https://t.co/efZTaA2qlX
17 DiskCache → store reusable script results on disk so recurring jobs can reuse unchanged work across runs
https://t.co/saflZGNdCN
18 LLMLingua → compress lengthy reference material before it enters the model’s context, then check that the details your task needs survived
https://t.co/IMXj3ns0lc
19 Git → version your prompts and configuration files so you can identify when a harmful rule appeared and restore a working setup
https://t.co/Q4uEQbD95D
20 delta → inspect readable diffs of instruction and configuration changes, making small additions easier to spot before comparing their effect on results
https://t.co/8KaNGTef67
rules like “verify twice” and “be maximally thorough” can turn a simple task into unnecessary checks. conflicting instructions, stale examples, and rigid procedures add more work before the bot even reaches the answer
audit the instructions, skills, routines, and tool settings your workflow actually uses. locate each questionable rule, explain its likely effect, and propose a specific change
test one edit on the same recurring job. preserve real requirements, quality checks, and approval boundaries. keep the revision when it reduces usage without making the result worse
save this. the most expensive line in your setup might be the one you forgot you added
the full guide below shows how to shrink working context, contain retries, and turn the saved budget into more completed work ↓
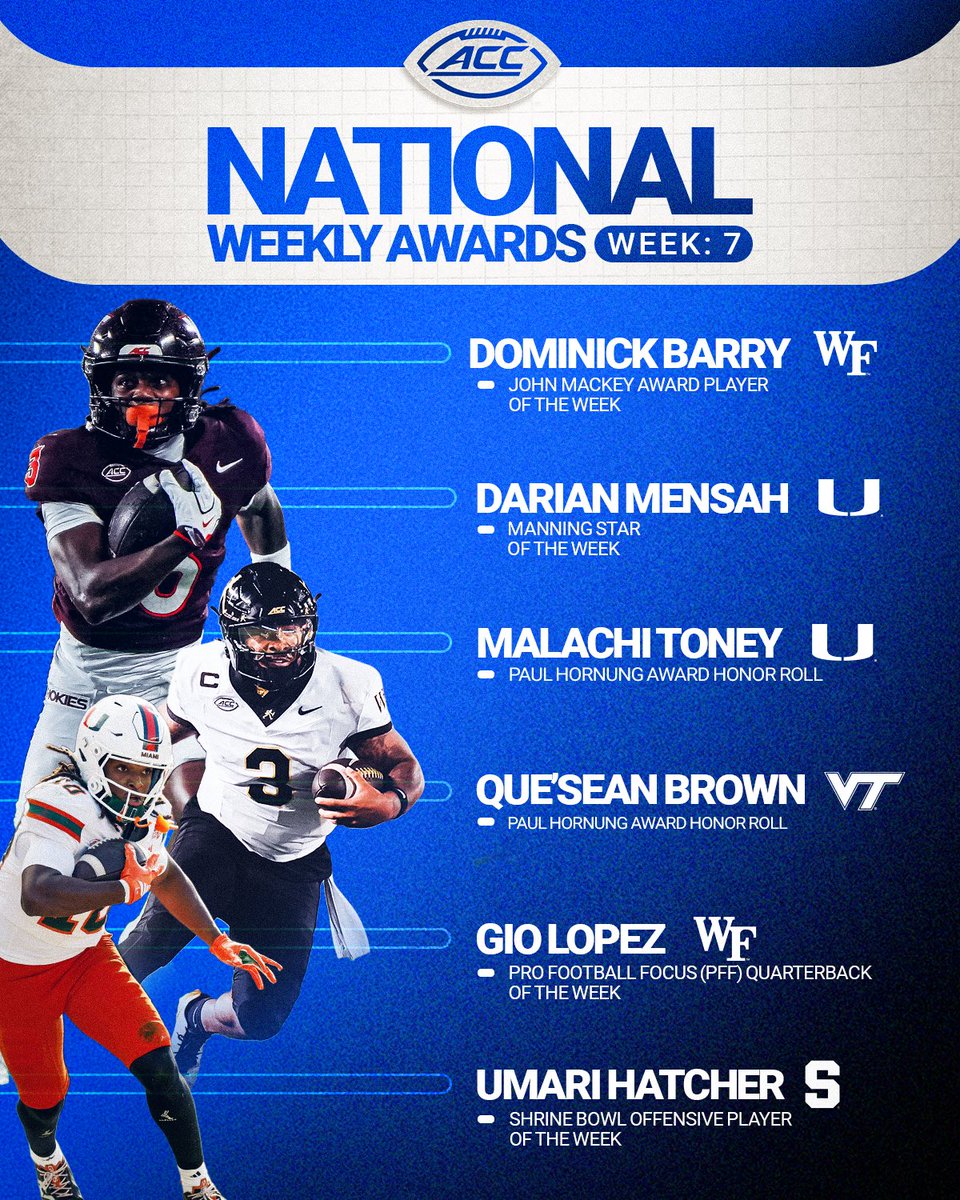
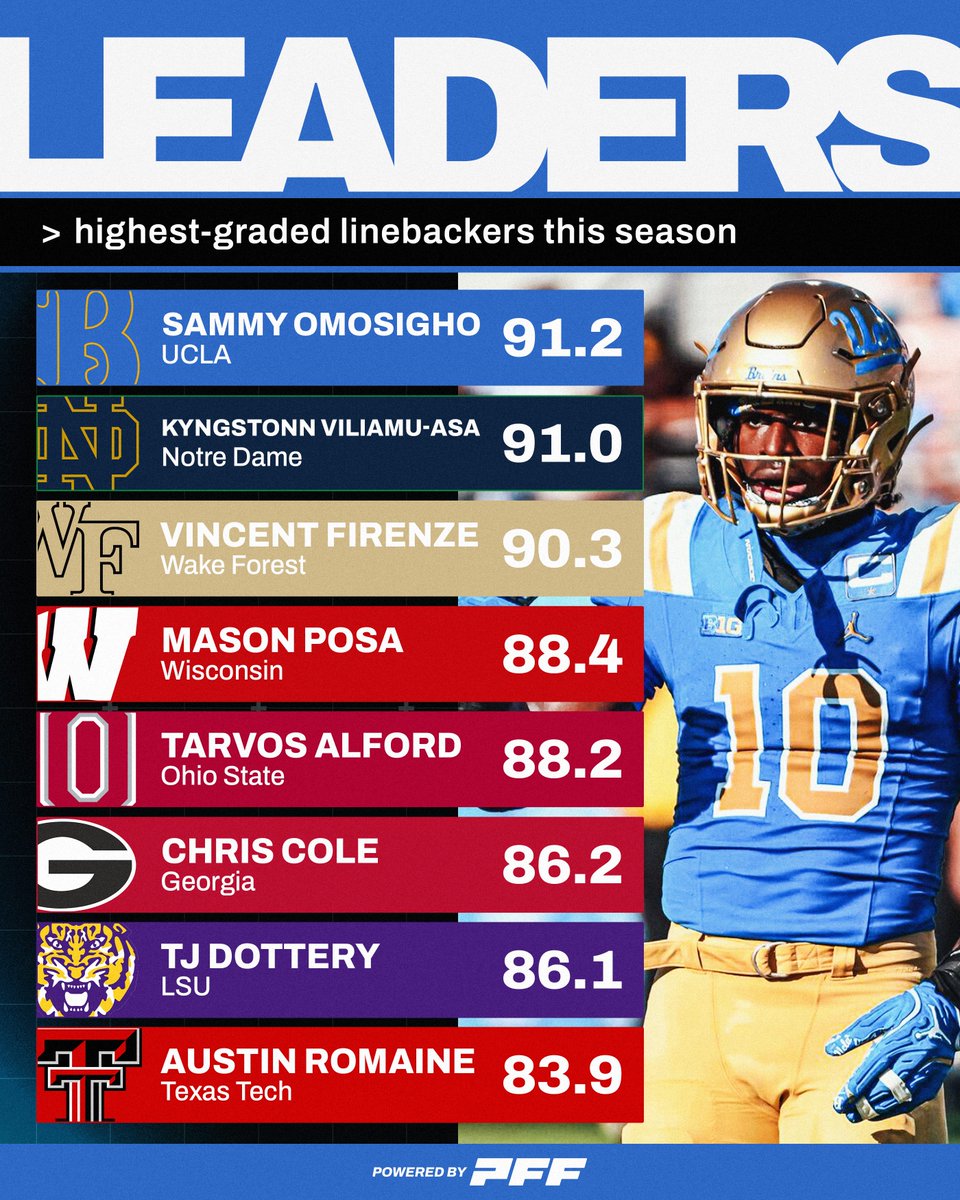
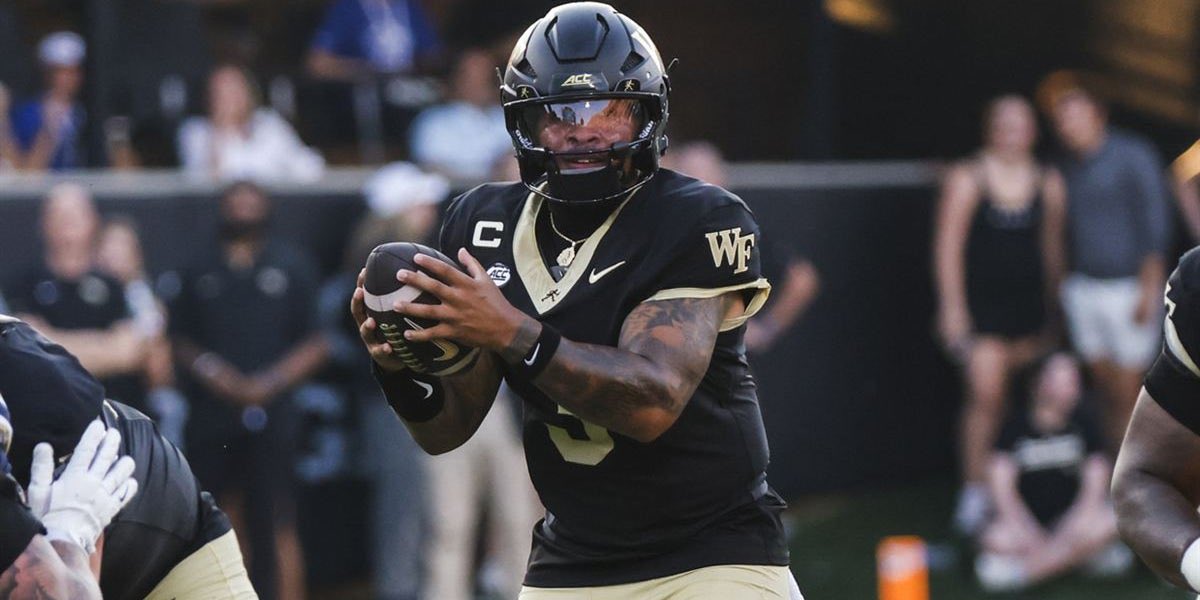
Wake Forest QB Gio Lopez is the highest graded quarterback in the Power 4 this season, according to PFF.
Week 1: 389 total yds, 3 pass TDs, 0 INT
Week 2: 283 total yds, 3 total TDs, 0 INT
Week 3: 312 total yds, 3 pass TDs, 1 INT
Week 4: 240 total yds, pass TD, 0 INT
Week 5: 353 total yds, 5 total TDs, 0 INT
Week 6: 313 total yds, 4 total TDs, 0 INT
Week 7: 318 total yards, 4 pass TDs, 0 INT
2,200 total yards, 23 total TDs, 1 INT
NEW: Wake Forest and Jake Dickert are 6-1, and he tells @PeteNakos that financial limitations are no excuse:
"The new revenue share has given all coaches excuses. And if it doesn’t work, (you hear), ‘It’s not me. It’s not something I did. It’s not my —’ I just don’t believe them. I don’t believe in that. We know what we have. We’ve got to leverage every cent and resource that we possibly can, and there’s going to be a tremendous amount of sacrifice by everybody. Period."
Story: https://t.co/04jkw7rWDG
#9 UCLA beat Cal by 21. Wake Forest flew across the country and destroyed Cal by 34 points.
#7 Ole Miss beat Louisville by 3 points on a neutral field in Nashville. Wake Forest one upped Ole Miss, beating the Cards by 3 on Louisville's home field.
Put some respect on the Deacs