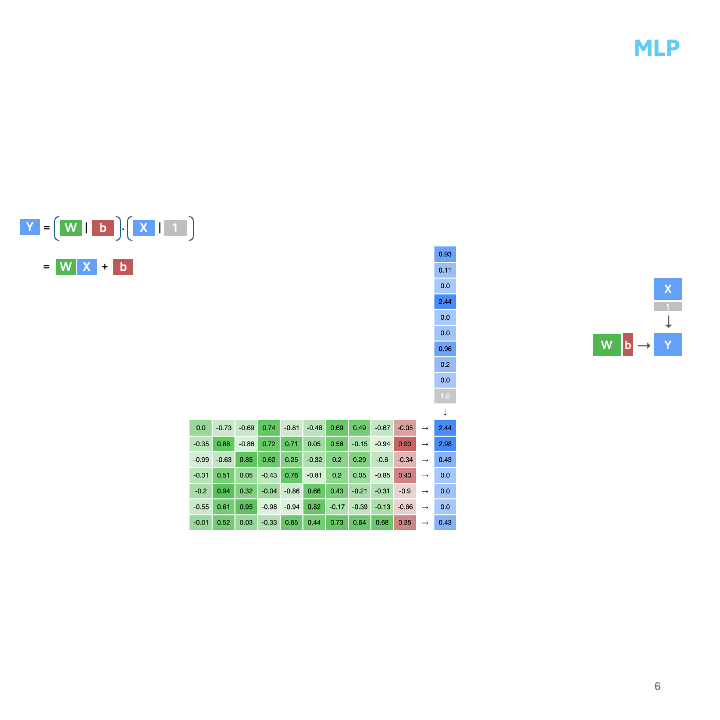
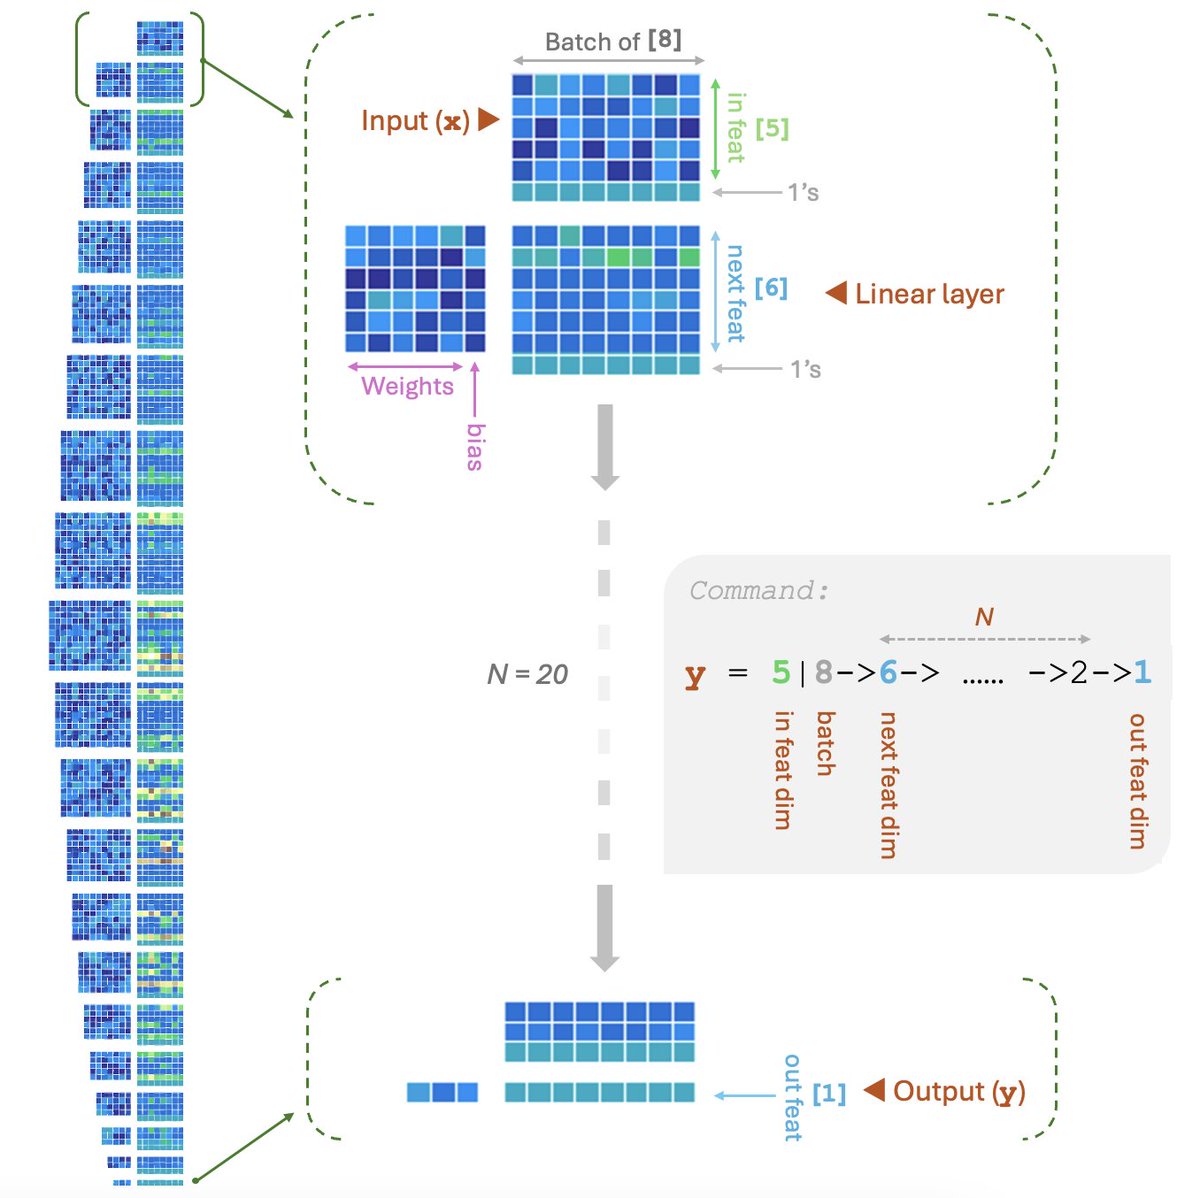
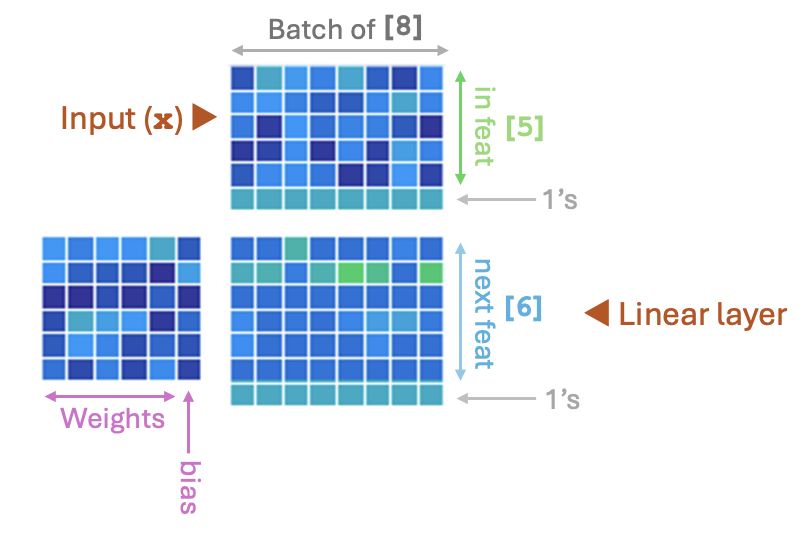
3/n) The visualization breaks down the matrix multiplication magic at the heart of MLPs.
Despite the AI hype, it's really just linear algebra in disguise! 🧠✨
1/n) Curious about the math behind neural networks? I created this visualization of the core equation powering Multi-Layer Perceptrons! 🤓
Each neuron is just WX + b in disguise - where input data (X) meets learned weights (W) and biases (b) to generate predictions....
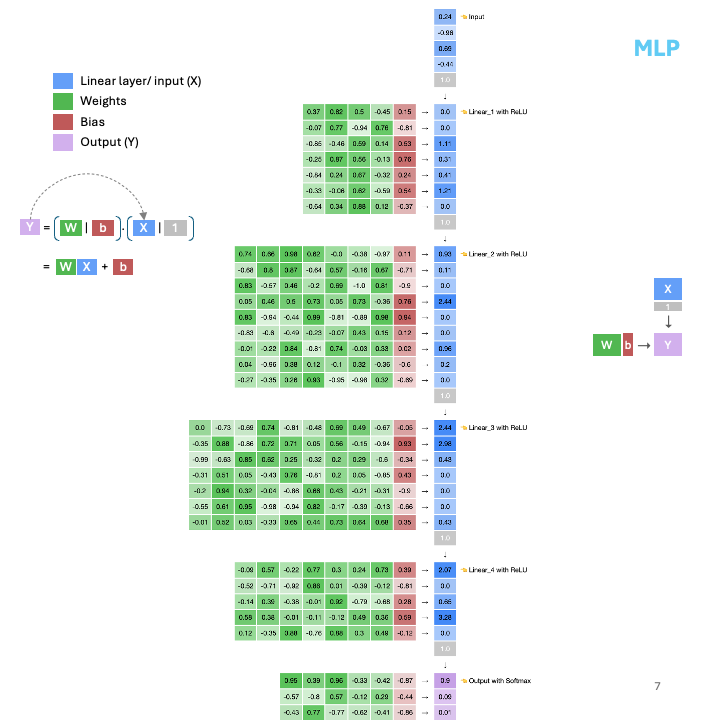
I created this to show a visual journey through MLP feature transformations! From Doge to Buff Doge, see how the MLP evolves from single input-output features to multiple dimensions!
#AI_math#MLP
1/3) I created this to visualize how AI-by-hand representation works for large deep neural networks. Left: a chain of matrix multiplications to build a long multi-layer perceptron (MLP). Check how the dimensions change through the hidden layers.
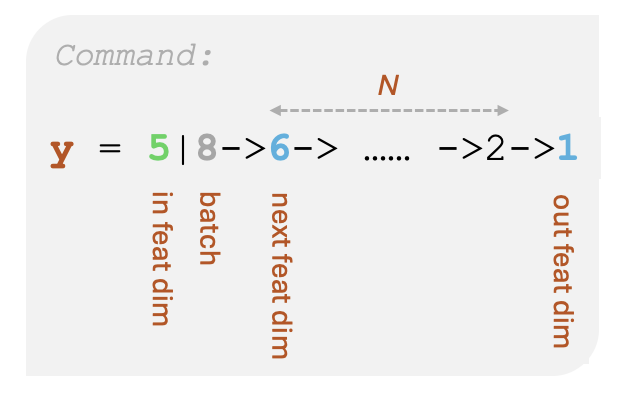
2/3) Magnification of a block showing the mechanism of the linear layer. Check the numbers [5], [8], [6], [1] in the image. These are parts of a special command: y = 5|8 -> 6 -> … -> 2 -> 1.
ICLR 2025 will have another blogpost track!
If you have new intuitions on past work, noticed key implementation details for reproducibility, have insights into the societal implications of AI, or an interesting negative result, consider writing and submitting a blogpost. Accepted entries will have the opportunity to be presented as a poster at ICLR2025 (in Singapore)! Deadline: Before Nov. 16 2024
More info: https://t.co/0PH7FinGbz
🚨 Plagiarism Alert at #ICLR2025 🚨
We have discovered that a paper submitted to ICLR 2025 has blatantly copied our Lab's work published at ICLR2023.
Shockingly, they didn’t even bother changing our method name “A2PO” to their own!
#AcademicIntegrity#ICLR@iclr_conf
LSTM by hand✍️Excel ~ I designed this exercise to show it is possible to calculate a simple LSTM by hand. Green🟩: Short Term. Blue🟦: Long Term. +equations. +medium.👇Join the 'AI Math' community. Download xlsx.
If you have a coding interview tomorrow for an ML or AI job, this is a great tool to brush up your skills. Thanks! @real_deep_ml for building and sharing this tool with our community. Look forward to seeing more of your posts!
Transformer: 4 Core Components Combined ~ Math vs Code 🔢💻 ~ I combined the visualizations I tweeted in the last few days to show you how to write PyTorch code to implement the four key math equations in Transformers: Attention, Multi-Head Attention, Feed-Forward Network, and Positional Encoding. See how these components come together to form the backbone of Transformer models. This unified architecture enables Transformers to process sequential data more efficiently and in parallel, giving them a core advantage over traditional models!
@Grubhub please stop harassing customers! My wife ordered from a restaurant and got orders of a different customer. Surprisingly, @Grubhub refused to refund! We have proof of images. But they said they're just sorry. Please be professional.
#grubhub@Grubhub_Care