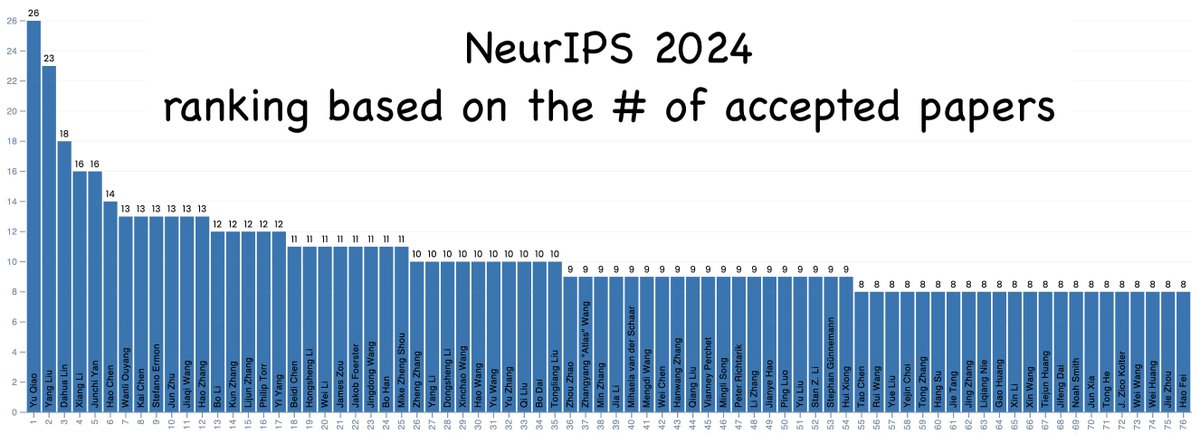
#NeurIPS 2024
MetaAligner: Towards Generalizable Multi-Objective Alignment of Language Models @SAnaniadou@Manchester_NLP
We propose MetaAligner, the first policy-agnostic and generalizable method for multi-objective preference alignment.
Paper link: https://t.co/Vjz1DWDBWP
For anyone doubting the severity and depravity of the mass gang rapes of little girls in Britain, go to the source material and read the court transcripts. I did.
It is worse than you could possibly imagine.
Our paper MetaAligner: Towards Generalizable Multi-Objective Alignment of Language Models accepted at @NeurIPS 2024 @nactem_unimcr@idsai_uom@csmcr
https://t.co/soDEHLuY2q
Super excited to finally share what I have been working on at OpenAI!
o1 is a model that thinks before giving the final answer. In my own words, here are the biggest updates to the field of AI (see the blog post for more details):
1. Don’t do chain of thought purely via prompting, train models to do better chain of thought using RL.
2. In the history of deep learning we have always tried to scale training compute, but chain of thought is a form of adaptive compute that can also be scaled at inference time.
3. Results on AIME and GPQA are really strong, but that doesn’t necessarily translate to something that a user can feel. Even as someone working in science, it’s not easy to find the slice of prompts where GPT-4o fails, o1 does well, and I can grade the answer. But when you do find such prompts, o1 feels totally magical. We all need to find harder prompts.
4. AI models chain of thought using human language is great in so many ways. The model does a lot of human-like things, like breaking down tricky steps into simpler ones, recognizing and correcting mistakes, and trying different approaches. Would highly encourage everyone to look at the chain of thought examples in the blog post.
The game has been totally redefined.
How can the in-context learning ability of LLMs benefit more effective and flexible multi-objective alignment of human values?
Our new work:
MetaAligner: Towards Generalizable Multi-Objective Alignment of Language Models
has been open-sourced!
ACL announcement:
"The ACL Executive Committee has voted to significantly change ACL's approach to protecting anonymous peer review. The change is effective immediately. (1/4) #NLPRoc
Pleased our project on emotion detection and misinformation has been funded by the Centre for Digital Trust and Society. Jointly with Peter Knight, Stephen Hutchings, @KailaiYang; Zhiwei Liu, Paul Thompson, @DigitalUoM@csmcr@idsai_uom@nactem_unimcr