“I’ve used FSD for like 90%+ of my miles since Saturday morning. Literally feels like magic. Has handled issues on the road better than I would have at times.
Just remarkable technology”
A demo drive might change your life
https://t.co/YkC5K8ofeR
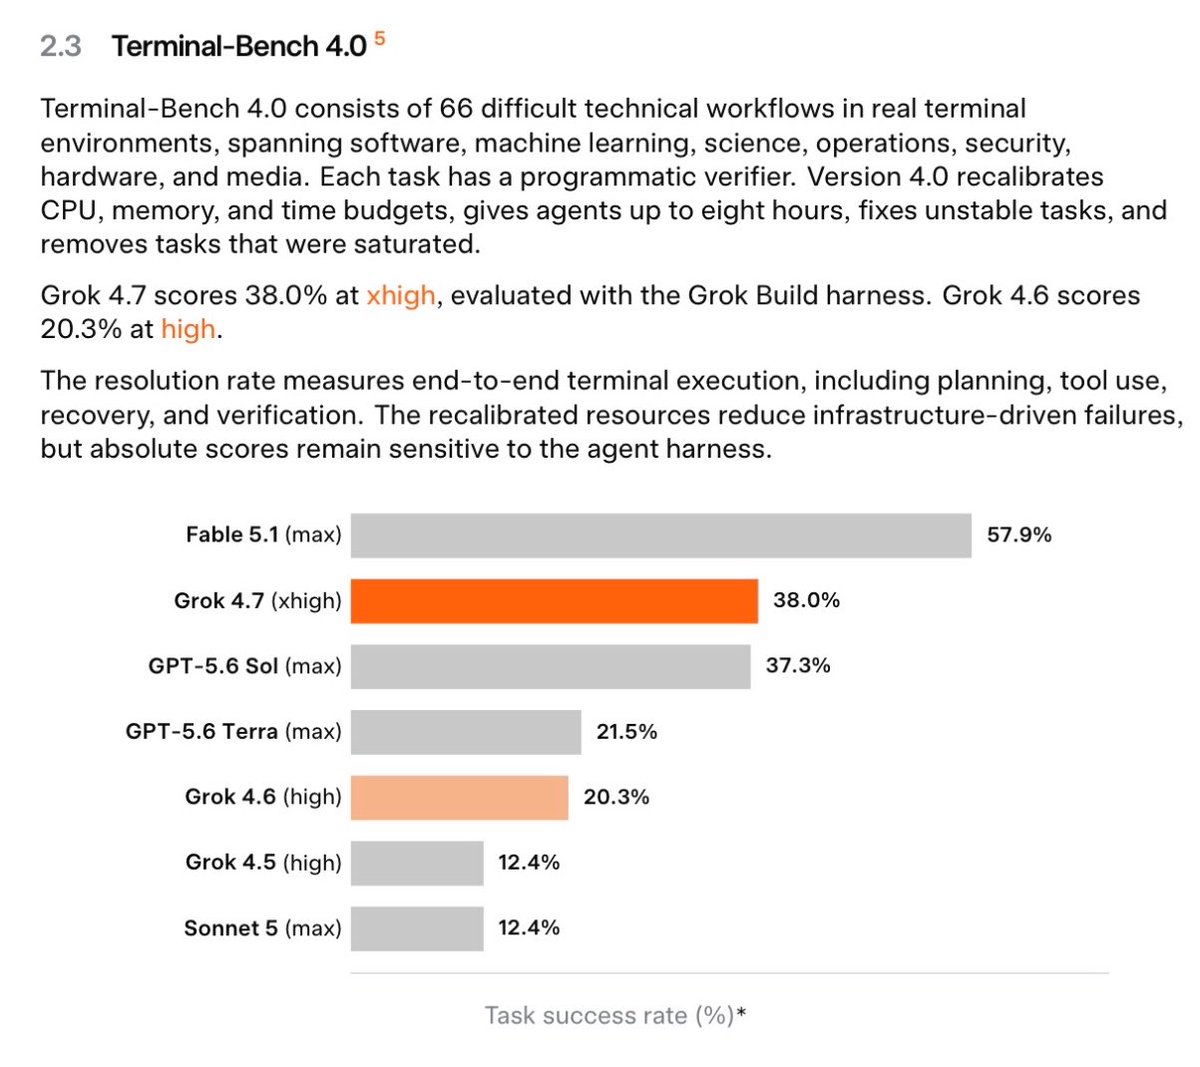
and here’s the grok 4.7 model card. a few jumps vs 4.6 that stood out:
- Terminal-Bench: 20.3% → 38.0%
- SWE-Marathon: 31.9% → 46.0%
- HealthBench Pro: 48.5% → 56.7%
- Legal Agent: 15.8% → 19.6%
- EEBench: 60.0% → 66.0%
for the same price as 4.6!
https://t.co/C0iyfYirQf
Grok 4.7 xHigh is now at the top with just ONE point away from Claude Fable 5.1 Max on Artificial Analysis’ AA-Briefcase benchmark
Claude Fable 5.1 Max — 59%
Grok 4.7 xHigh — 58%
Just a 1-point difference at the very top
And Grok is ahead of GPT-6 Astra, GPT-5.6, Gemini, Kimi, GLM and nearly every other frontier model on the benchmark
Grok 4.7 just released and it's an EXCELLENT model
It was trained FOR Grok Bot
Meaning this is a fully agentic model trained to do your knowledge work better than you can
In this video I show you how to use Grok 4.7 and a Grok Bot workflow that will 10x your productivity:
Been testing Grok 4.7 for the past week or more. It’s been a great improvement over 4.6.
It worked for over 70 hours straight on a goal. Much better attention to detail.
The 500k context window really makes a difference imo. 4.7 much better at things like skill selection; workflows. Found it particularly good with pstack.
Didn’t have access to it in Grokbot, but I really wanted to test it there. Together it’s a great daily driver.
day 1 observations for grok 4.7
ignore the reports that say “it’s terrible” and the only thing they reference is a public benchmark. the same benchmarks told us opus 5 was better that fable - they are useless
also ignore the reports that compare models with 3d games - that’s not real work. it's made for attention on social media
i used grok 4.7 for a whole day as my firstmate, and it has been a really solid model with visible improvements over 4.5 (i'm ignoring 4.6 because 4.5 has been working better in my experience)
key differences with 4.7 -
1. it follows system prompt very, very closely
i noticed firstmate showing many new behaviors that i've never seen before, such as asking me to name specific red CI checks that i'm ok with bypassing, and refuse a simple "yolo" instruction
i traced it and it's indeed how i instructed it in firstmate's system prompt, but none of the other models followed it closely enough to make this behavior visible - grok 4.7 is the first to pick that up
there were a few other similar examples as well. so to me this is a clear behavioral difference
2. it's very "stable"
if you've used astra then you know what a "spiky" model is. it can have some genius moments but you occasionally also wonder "how could it be so dumb and doesn't get me". grok 4.7 is the opposite of that
throughout the whole day so far, i'll be honest i haven't get a "wow this is absolutely genius" moment yet, but grok 4.7 has been very steady with no big surprises. its behavior feels predictable, which does help it gain trust from me quickly
3. it's a conservative model
it doesn't like to take actions without asking, and would explicitly say so
this is a bit of a double edged sword, because it means i sometimes have to state the obvious "yes i do want that", but in hindsight a lot of those cases are indeed a bit ambiguous and i may not have preferred the model to just move forward without my confirmation
4. it's a bit slower and costs more than 4.5, visibly
turns are taking a bit longer and my quota is draining at a visibly faster pace. i haven't quantified exactly where this is coming from yet
so overall, i think it's showing some clearly different traits, and i mostly like the changes. i'm going to keep it as my primary firstmate and observe more
if you've been using it, what qualitative insights have you gathered from real usage so far?
New pod with @SawyerMerritt diving into the Tesla Cybercab: What we loved, what can improve, our FSD experiences, and what's next for @robotaxi.
Watch the full conversation here on X or listen to The Kevin O'Connor Show on your favorite podcast app.
Next week, the SpaceXAI team will build a company from the ground and livestream it.
“We'll use Grok Bot for every part of the build - from ideation and product development to real engineering work and deployment.”
The @spacexai team just gave me 50 free Grok @bot codes to give out which will give each person either $200 in on-demand usage or an Ultra plan.
So the first 50 people in my replies that agree Cybercab should have a steering wheel will win.
Go.
Privileged to be a major investor in @boringcompany Series D and to have helped scale the team for 5 years.
Vegas Loop proved what’s possible. With the $3B raise, TBC is expanding to many more cities in the US and abroad.
This is a rare moment to join the team and help bring Loop to the next 100 cities.
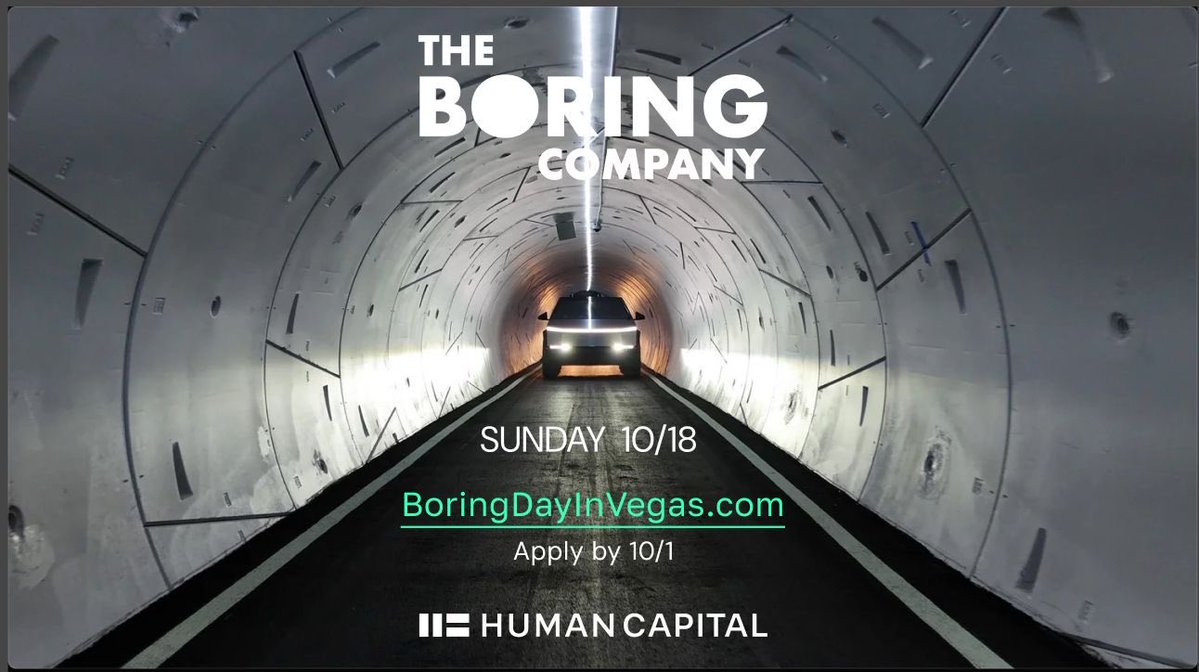
We are inviting a select group of exceptional engineers and operators to an all expenses paid, behind the scenes tour of the Vegas Loop on Sunday, Oct 18.
Years of experience is not a filter. New grads and dropouts should apply.
Apply by Oct 1
https://t.co/SDruSRSAeD
The Tesla Cybercab’s rear trunk is huge. It fit our two full-size suitcases and two bags with plenty of room to spare and is very easy to load and unload.
It has 20.2 cu ft of storage, which is just shy of a Model 3 (21 cu ft), but is waaay easier to fit larger items since it’s a hatchback, so it actually feels bigger.