A model is only as good as what it’s trained against, so we build environments that are robust, resistant to reward hacking, and built to frontier-lab standards.
We’re excited to join the @basetenco Environment Network to bring this to more teams!
We looked at TerminalBench 4.0 and found a lot of issues. After fixing the issues Sonnet 5.5 scores 89.2%. So, TerminalBench is already mostly saturated.
Along the way we found a lot of crazy stuff, including reward hacks in the published transcripts.
We looked at TerminalBench 4.0 and found a lot of issues. After fixing the issues Sonnet 5.5 scores 89.2%. So, TerminalBench is already mostly saturated.
Along the way we found a lot of crazy stuff, including reward hacks in the published transcripts.
Today we are open-sourcing 🥕Karotte, our framework for building RL environments.
We've used it for the past year to build MLE RL environments for frontier labs, and it's been hardened through 1M+ evaluation runs and red-teaming.
Today we are open-sourcing 🥕Karotte, our framework for building RL environments.
We've used it for the past year to build MLE RL environments for frontier labs, and it's been hardened through 1M+ evaluation runs and red-teaming.
Recent work like TypeSafe's Jev (trained with RLCD) gives calibrated probabilities for fast, structured decisions .
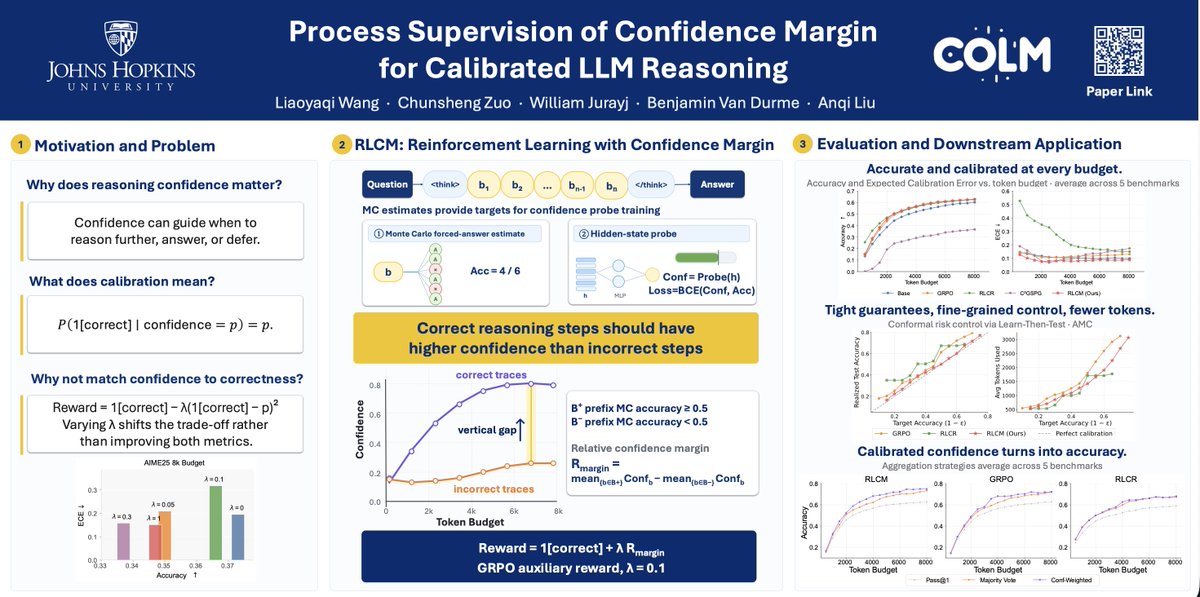
We zoom in on the reasoning itself: can confidence track correctness step by step, as the trace unfolds?
Check our #COLM2026 paper: RL with Confidence Margin 🧵