Most optical computing works on a flat photonic chip, where large matrices run out of room or stack up noise.
Lumai Iris computes in 3D with free-space optics, so a large matrix operation completes in a single optical cycle.
https://t.co/PoXwTmr1em
#opticalcompute#compute #datacenter
The UK has to build its sovereign AI compute within the power it has available.
ARIA's Scaling Inference Lab, run by CommonAI, is where new approaches get proven on real workloads. Lumai Iris, born from Oxford optics research, is the first optical platform in.
#sovereignAI #opticalcompute #datacenter
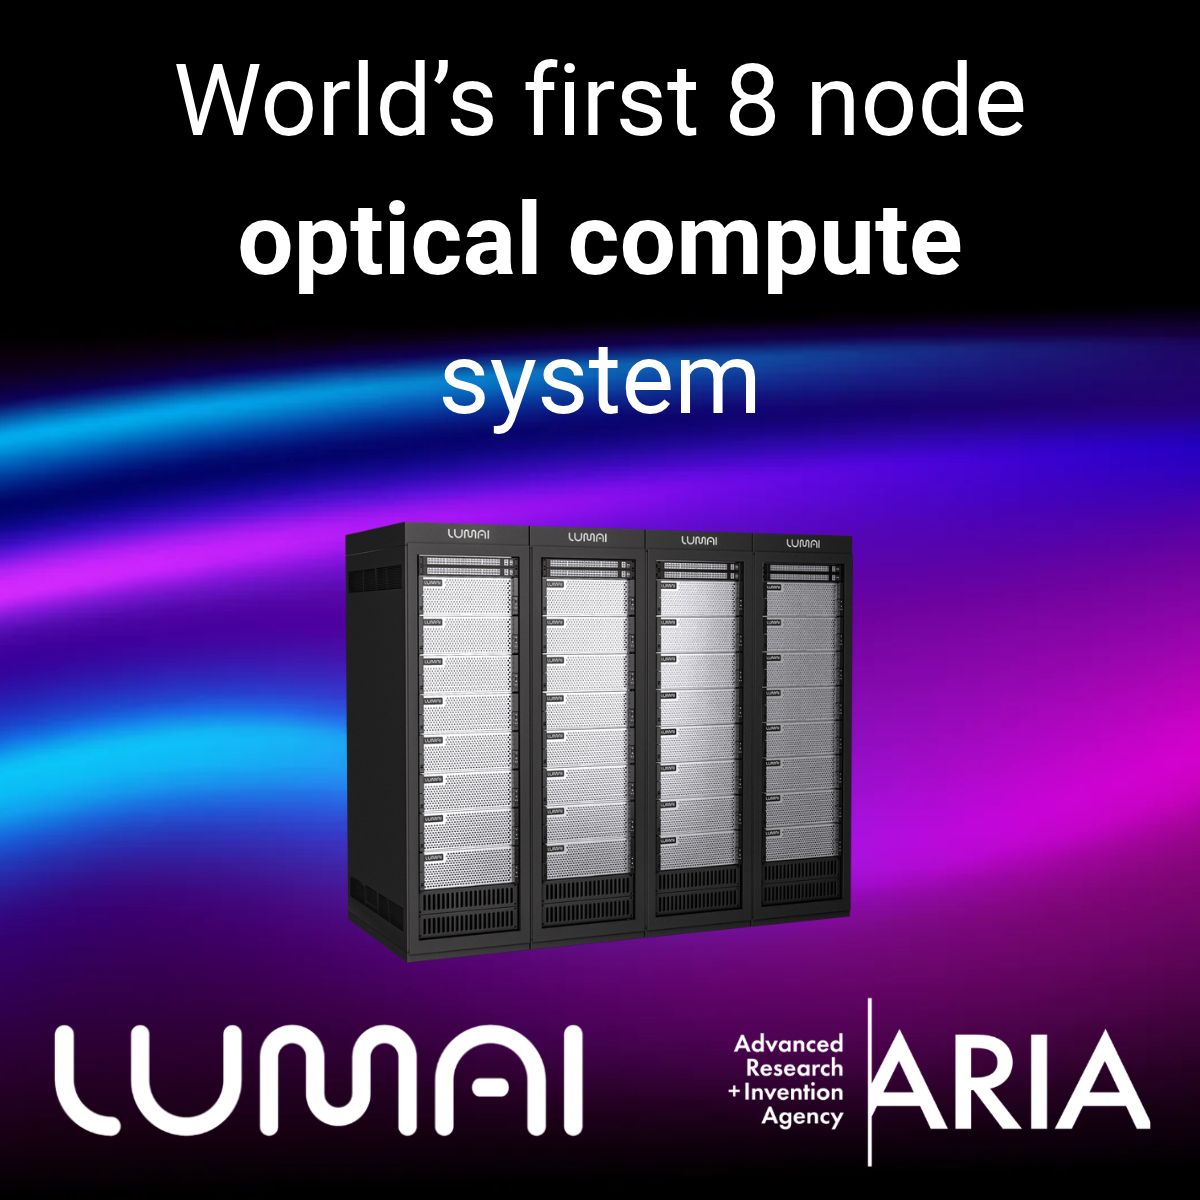
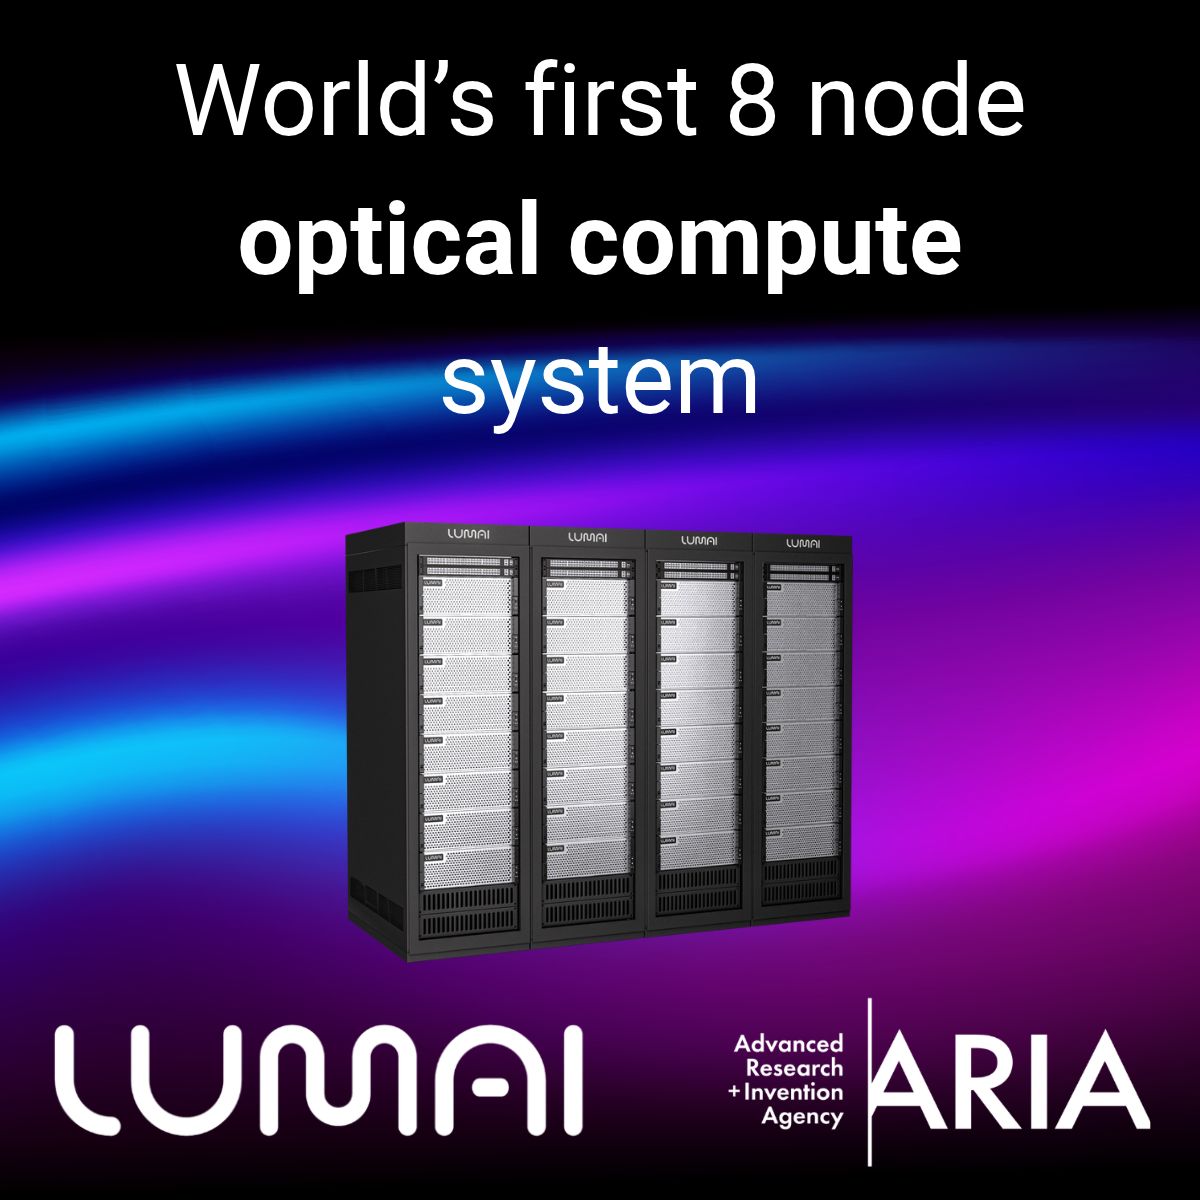
ARIA will deploy an 8-node Lumai Iris system in its Scaling Inference Lab, run by CommonAI CIC. Lumai was selected through a competitive technical evaluation. Once it's operational, external teams can bring their own workloads.
https://t.co/LZaUXXnvXA
#opticalcompute#optical #compute #datacenter
“The most mature optical compute platform we evaluated.”
ARIA's David Lewis on why Lumai Iris will be the first optical inference platform in the Scaling Inference Lab.
Independent testing at rack scale starts here.
https://t.co/LZaUXXnvXA
#Opticalcompute#aiinfrastructure@datacenter
Meeting one leading AI lab's compute ambition on conventional accelerators alone: an estimated $100 trillion and 1,000+ GW within five years.
Building faster won't close this gap. Changing the physics of computation can.
https://t.co/ML9JNT5gZP
#opticalcompute#datacenter #compute
ARIA will deploy Lumai Iris servers as the first optical inference platform in its new Scaling Inference Lab, run by CommonAI CIC.
8 nodes. Production-scale models. A commercial data center. Open to outside teams once operational.
Optical compute, tested in the open.
#OpticalCompute #AIInference #DataCenters #SovereignAI
Read the press release:
https://t.co/LZaUXXnvXA
A year ago, our CTO Dr. James Spall stood on the Falling Walls stage in Berlin to explain how light could change the way AI scales. Lumai left with the Falling Walls Award for Science Breakthrough of the Year 2025.
We’re proud to see James help choose the next breakthroughs, and we can’t wait to hear what this year’s finalists are building.
#FallingWalls #OpticalCompute #AIInference #Photonics
(Link to his video from last year: https://t.co/FUDhmTJo8V)
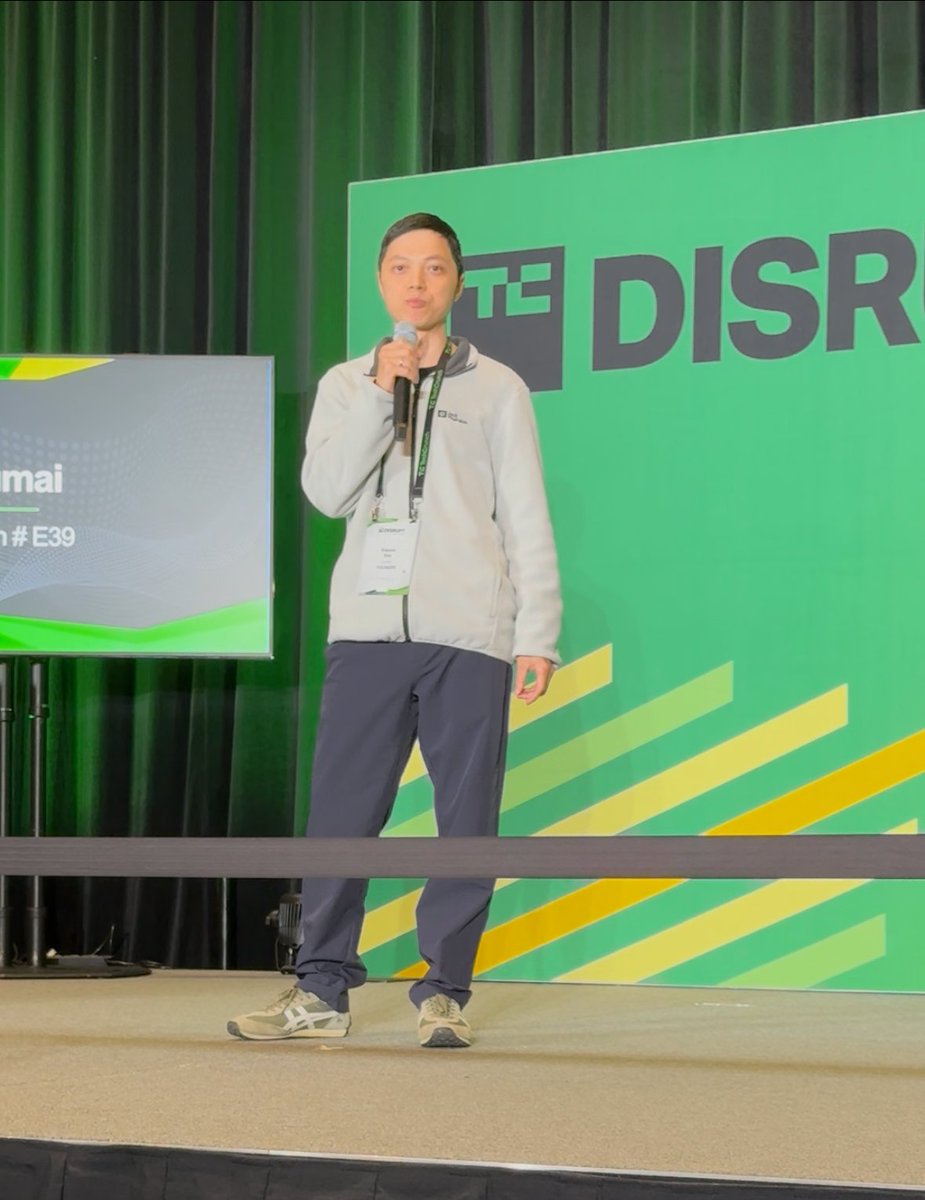
Yesterday our CEO Dr. Xianxin Guo presented Lumai at #StartupBattlefield at @TechCrunch Disrupt in San Francisco.
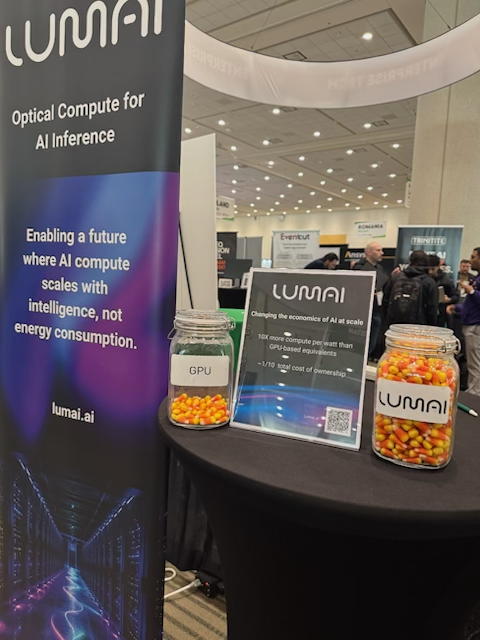
Lumai Iris uses light to power AI prefill, targeting ~10x more compute per watt than GPU-based equivalents.
More AI inference from the power data centers already have. #TCDisrupt
We are excited to join the @TechCrunch Startup Battlefield at TechCrunch Distrupt. If you are at the show, be sure to stop by and let us know how much compute per watt you would prefer?
#opticalcompute#aiinference#photonics
Lumai is in the Startup Battlefield at @TechCrunch#TCDisrupt 2026. Come see how optical compute gets more AI inference capacity out of the same data center power. Find us at table E39.
Discounted tickets: https://t.co/VmUAyxEJJ3
#TCDisrupt#StartupBattlefield #OpticalComputing #AIInference
AI inference runs two jobs: prefill (compute-bound) and decode (memory-bound).
Decode has specialized silicon. Prefill doesn't, and the gap widens with every bit of context added.
Light fixes that. New white paper: https://t.co/6Cu6u1v17j
#AIInference#OpticalComputing
Frontier labs project ~1,000x growth in AI compute demand over 5 years.
Meeting that with today's silicon: ~$100T in infrastructure, ~1,000 GW of power.
New white paper on why prefill needs different physics: https://t.co/6Cu6u1v17j
#AIInference#OpticalComputing
Lumai Iris Server does prefill's matrix math with light, not electricity. ~10x less energy per inference. Validated on Llama 3. Deploys in existing air-cooled racks.
Iris Nova is available for evaluation now: https://t.co/tbedQcm2h9
~1,000x more compute demand in 5 years. ~$100T in infrastructure. ~1,000GW of power.
Neither number works. The constraint is energy, and prefill is where it hits hardest.
https://t.co/2IIwZRfaMQ
#OpticalComputing#IrisNova#AIInfrastructure#Prefill
Decode has memory-optimized accelerators deployed at hyperscale. Prefill runs on whatever silicon is left over.
Same inference stack, two workloads, only one designed for.
Phil Burr on the gap nobody's solving: https://t.co/OzEm8boxBY
#LLMInference#AIInfrastructure#Prefill #OpticalComputing
OpenAI's Sam Altman says AI needs a fundamentally different computer.
Frontier labs need ~1,000x more compute in 5 years. Today's chips: ~$100T, ~1,000 GW.
This is a physics problem, plain and simple.
Optical compute solves it. We already built it. Read about it in our blog: https://t.co/JJuZPyoZjz
#OpenAI #Opticalcompute #AIinference
Sam Altman just called today's AI hardware "fundamentally the wrong machines," and pointed to optical computing as the fix.
We've been building that fix since 2021.
https://t.co/4QPqcJVwPe
#optical#aiinfrastructure
Until prefill finishes, the model has nothing to say.
Prefill reads your entire prompt in one batched pass and builds the KV cache decode reads from. It's compute-bound, and as context windows grow, it increasingly sets the ceiling on your inference stack.
We broke down why. https://t.co/eF8wGXeSmS
#AIinference #prefill #decode