In continual learning, what is the algorithmic bias of explicit regularization?
We answer this in our new COLT 2026 paper:
Convergence of Continual Learning in Homogeneous Deep Networks
Work by @MatanSchliserm1 joint with @itayevron and @soudry_daniel
https://t.co/lyHqz13WIn
[1/5] Next week at #NeurIPS
*Optimal Rates in Continual Linear Regression via Increasing Regularization*
In the brain, ageing naturally reduces synaptic plasticity.
Our theory suggests continual learning models may benefit from a similar mechanism!
https://t.co/9tyYYZbpT5
In continual learning of linear models
random task orderings diminish forgetting
even in high dimensions!
Better Rates for Random Task Orderings in Continual Linear Models
Evron*, @ranlevinstein*, @MatanSchliserm1*, Sherman*, Koren, @soudry_daniel, Srebro
https://t.co/D9mnWijufW
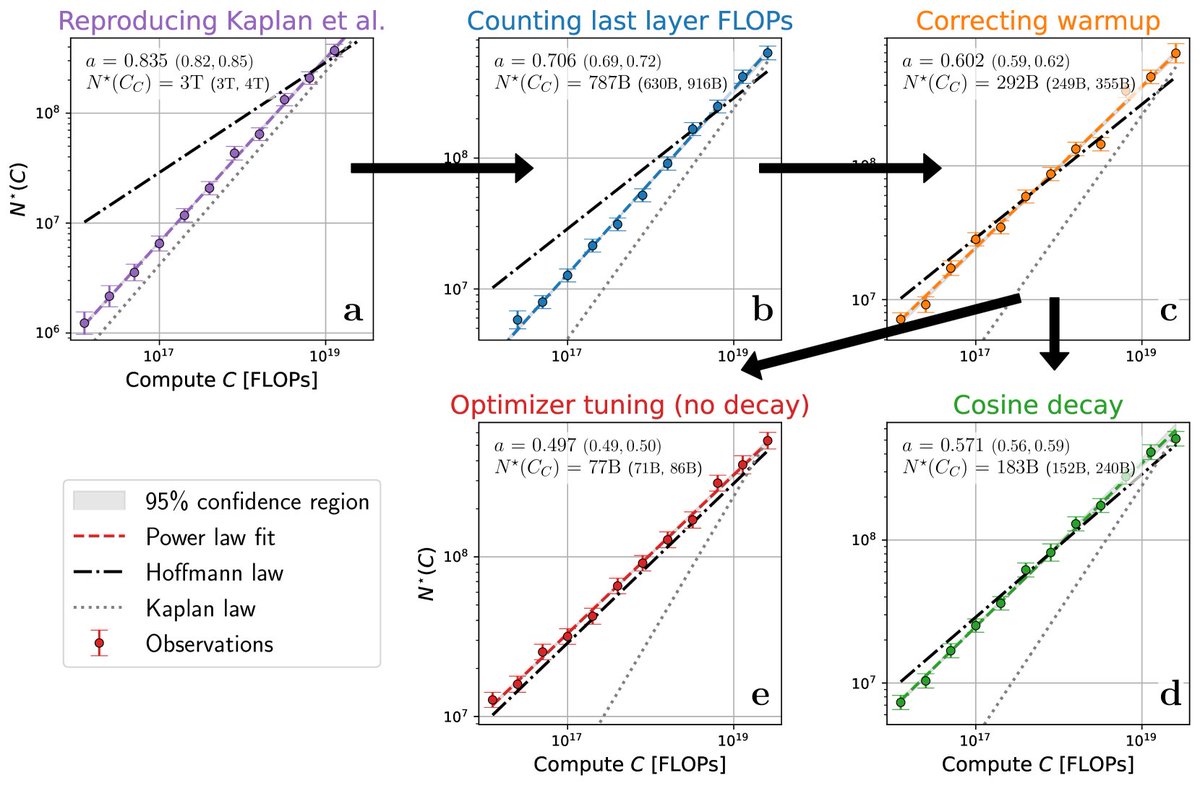
🧵1/8 We resolve the discrepancy between the compute optimal scaling laws of Kaplan (exponent 0.88, Figure 14, left) et al. and Hoffmann et al. (“Chinchilla”, exponent 0.5).
Paper: https://t.co/QKFbNl4J9t
Data + Code: https://t.co/N3p0Xg0THH