Day 8 of building in public.
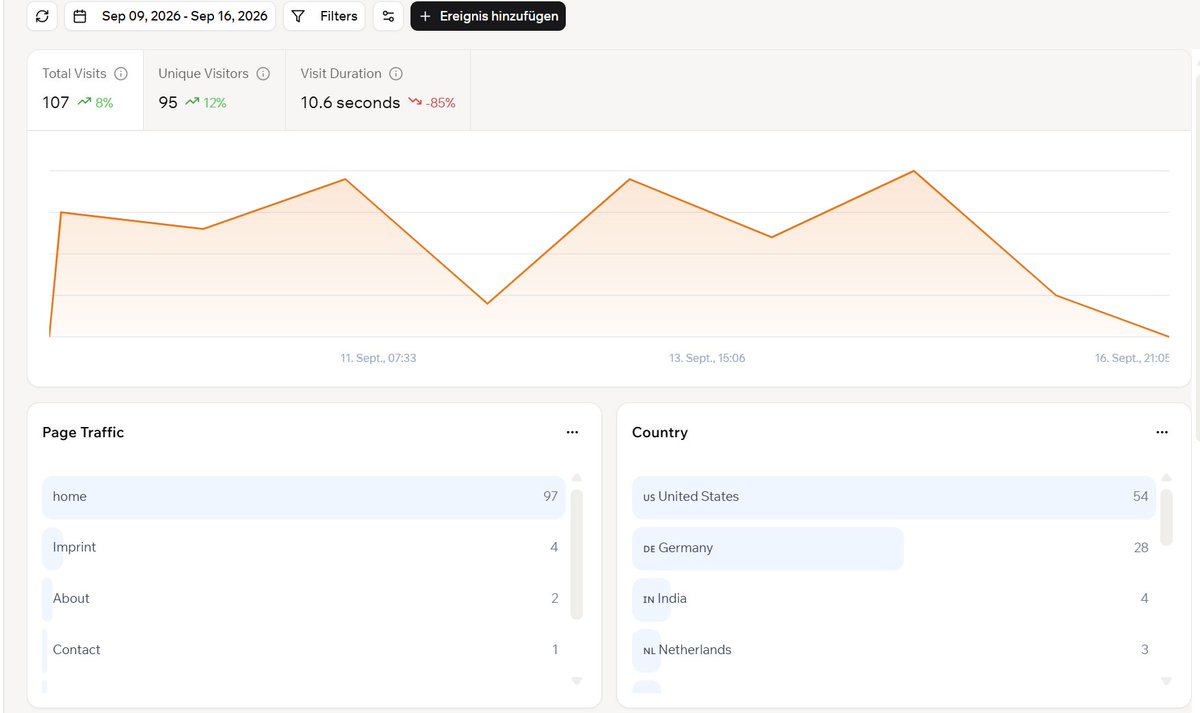
Crossed the 100-visitor milestone, but still zero kings crowned. Everyone is comfortably staying on the Wall of Broke.
27 visitors today (107 total). Total revenue: €0.
Until someone actually pays.
What it's actually for: sorting, routing, scoring, flagging. Anything where the answer is one of a few options you already know.
What it's not for: writing. No text, no code, no replies. That stays with ChatGPT or Claude.
So two different tools, not a replacement
TypeSafe AI, founded by one of the researchers behind ChatGPT, released a model called Jev yesterday. It tells you honestly how sure it is.
Normal AI sorts your support mail and sounds certain even when wrong. Jev says "return, 94% sure".
So the clear ones run alone.
TypeSafe AI, founded by one of the researchers behind ChatGPT, released a model called Jev yesterday. It tells you honestly how sure it is.
Normal AI sorts your support mail and sounds certain even when wrong. Jev says "return, 94% sure".
So the clear ones run alone.
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
Day 7 of building in public.
One full week in. 80 people have visited, but zero kings crowned. The Wall of Broke remains 100% undefeated.
11 visitors today (80 total). Total revenue: €0.
Until someone actually pays.
Considering that it’s currently completely free with all paid Devin plans, it’s basically a must-try for every developer.
The model’s speed can fluctuate from time to time, but usually within a few minutes it’s back to normal. I always use it with Effort set to Max.
SWE-2 by Cognition is probably one of the most underrated models right now. Over the past few days, I’ve tested SWE-2 across a wide range of areas: frontend, backend, general knowledge, and software architecture, and I have to say, it’s outstanding.
Turns out I was right about this. More and more sources are pointing to a covert test of Opus 5.2 in Claude Code.
It now looks increasingly likely that there won’t be an Opus 5.1 at all, Anthropic may be jumping straight to Opus 5.2.
I can confirm this. Since yesterday, Opus 5 with Effort Max in Claude Code has been using an insane amount more thinking tokens, enough that I immediately noticed something felt off.
Anthropic is definitely testing something. The question now is whether it’s Opus 5.1 or Opus 5.2.