Have questions on the new license? Join Chris Lattner @clattner_llvm and Tim Davis @iamtimdavis for a live Q&A on the new license, Nov 10th at 10 AM PT: https://t.co/x5G1ylCQx5
Also in 26.7: eager mode for faster custom op development, decision model support, and Mojo 1.2 with pattern matching, the next step in Mojo’s growth into a systems programming language: https://t.co/EJ1yKy6xUJ
It’s day 2 of @PyTorch Conference! Today is your last chance to stop by the Modular booth (#3). If you missed @clattner_llvm's talk, come find us and we’ll walk you through our stack and answer your questions. We’d love to hear about what you’re building and give you a Modular shirt.
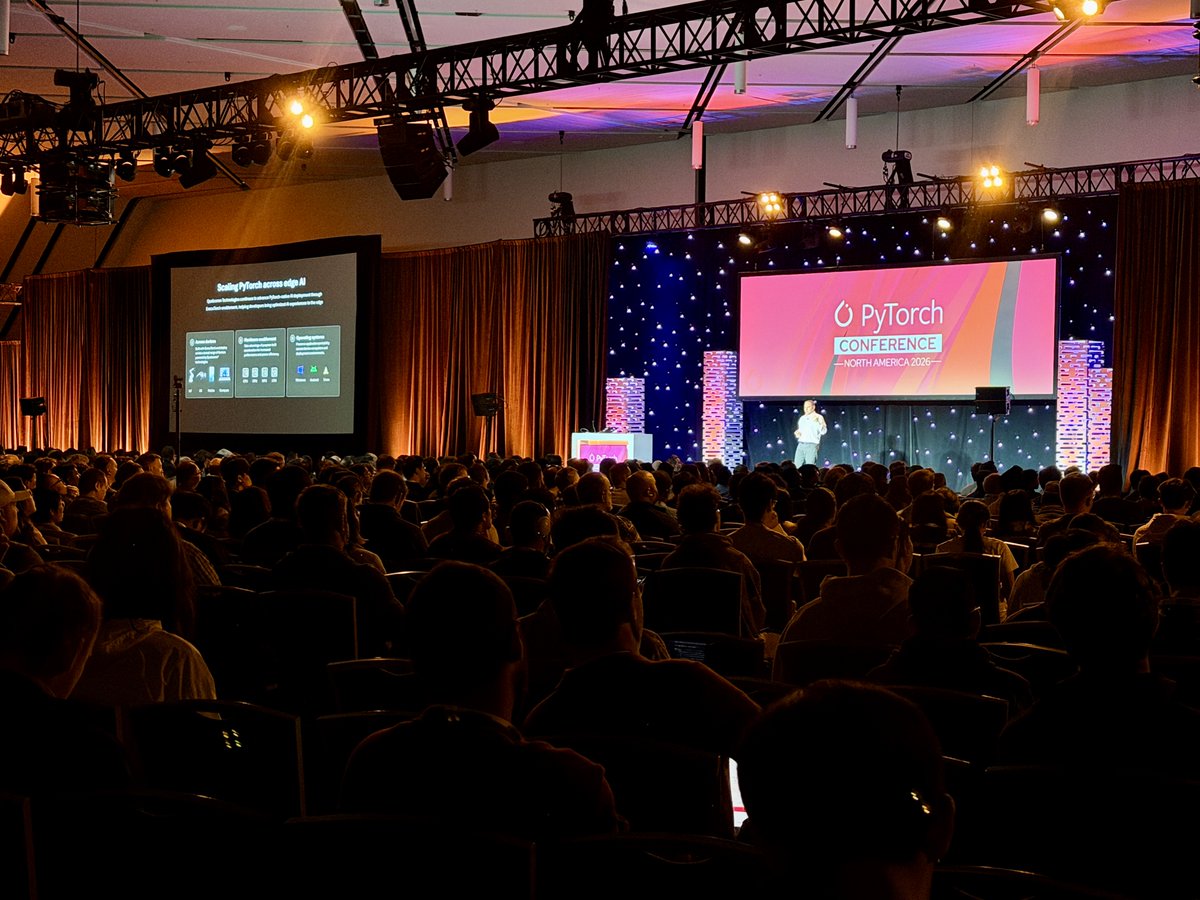
#PyTorchCon kicks off today, and we’re excited to spend the next two days with the PyTorch community.
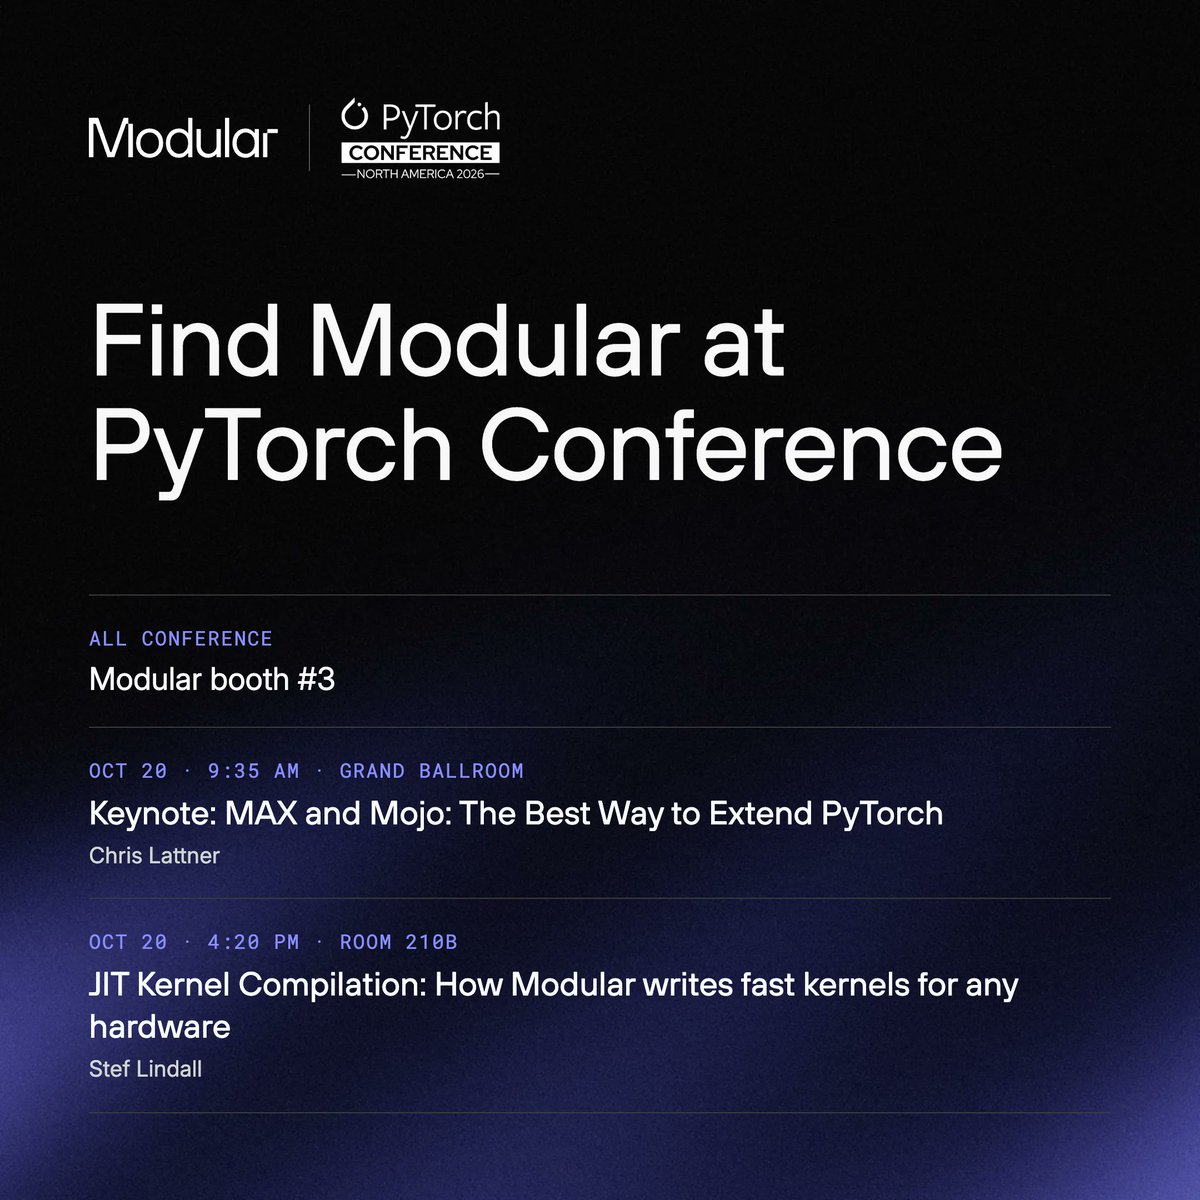
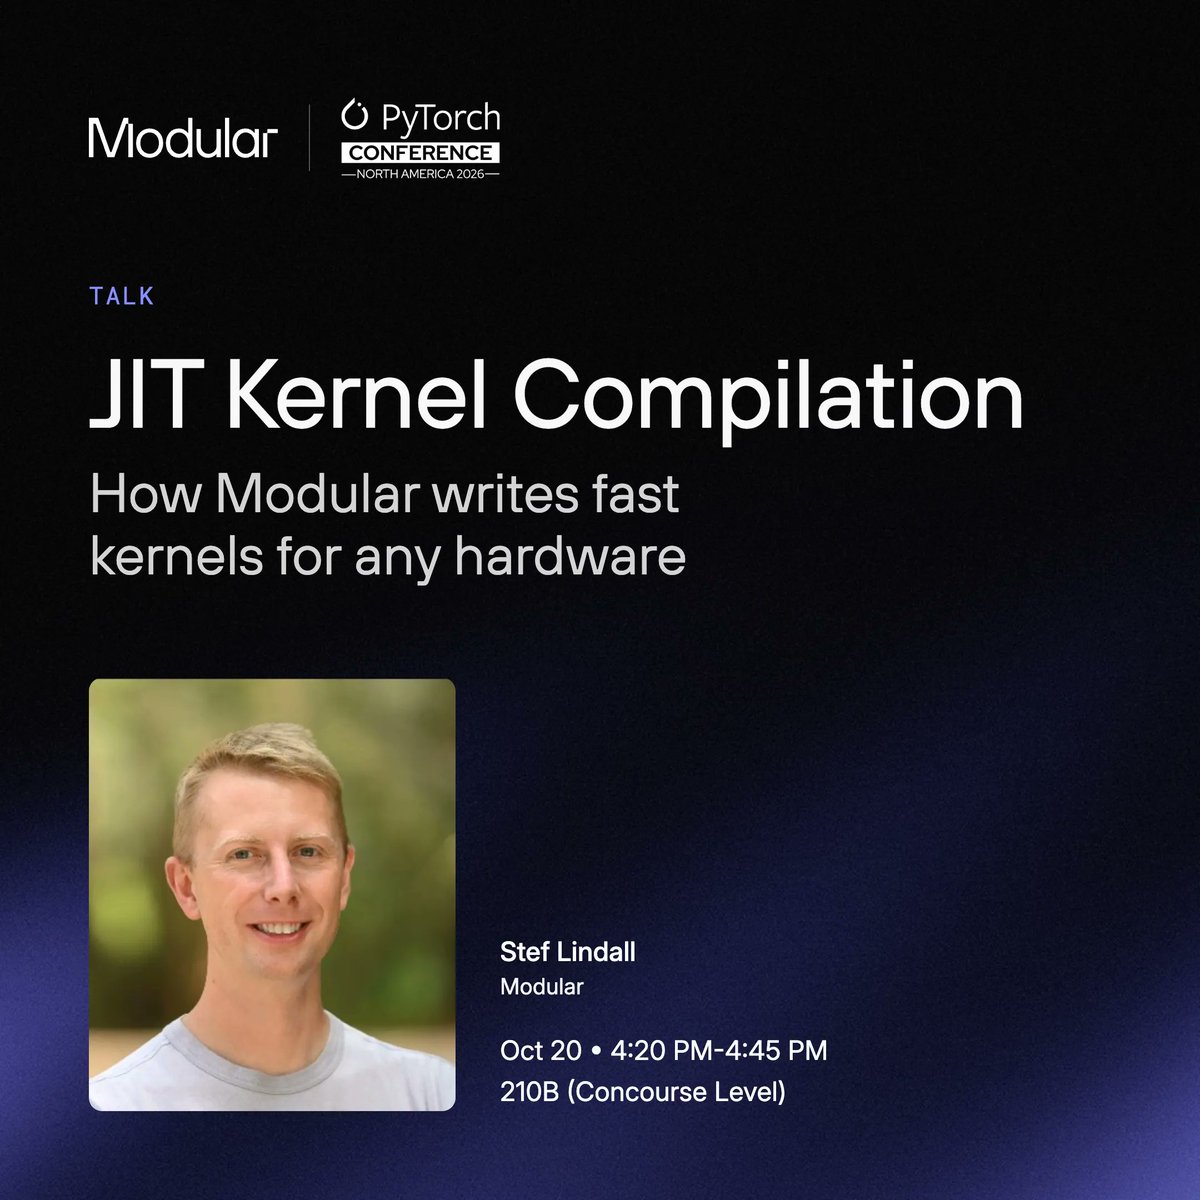
In a few hours, @clattner_llvm delivers a keynote: “MAX and Mojo: The Best Way to Extend PyTorch” (9:35 AM, Grand Ballroom). This afternoon, Stef Lindall goes deep on how we compile fast kernels for whatever hardware you’re running (4:20 PM, Room 210B).
Throughout the conference, you can find us at booth #3 to talk accelerators, compilers, and open roles. Stop by today to grab a MAX and Mojo T-shirt while supplies last.
The Modular team is heading to the 2026 @llvmorg LLVM Developers’ Meeting in Santa Clara on Oct 26–28.
On Monday, the Mojo team is running a full-day workshop on Mojo internals and the roadmap. Bring your hardest questions about how the language works under the hood.
On Wednesday, Spenser Bauman explains how MAX emits device graph construction code with its MLIR/LLVM graph compiler instead of relying on vendor record and replay support, which lets it support a broader range of accelerators.
We’re sponsoring alongside Qualcomm all week. Our recruiting team will be at the booth if you'd like to explore open roles.
Software ships every week. Silicon often gets locked in years ahead of time.
At ModCon 2026, @clattner_llvm asked hardware leadership from d-Matrix, Qualcomm and AWS how they plan years ahead while models change constantly, and what software challenges they keep running into.
Full panel recording: https://t.co/gN4YmHKMF6
Chris Lattner keynotes #PyTorchCon on Tuesday: “MAX and Mojo: The Best Way to Extend PyTorch.”
@clattner_llvm will cover how we’re helping developers run their models across a wider range of hardware. He’ll also share an early look at how the broader ecosystem can build on MAX with us.
After his keynote, swing by the Modular booth (#3) for demos and swag.
#PyTorchCon starts next Tuesday! On day one, Stef Lindall, Principal Engineer at Modular, will cover how MAX lets you write fast kernels for any chip and compile them just in time.
Oct 20, 4:20 PM, Room 210B.
Find the Modular team at booth #3 on both days for live demos and swag.
https://t.co/78cjib7LNp
Headed to #PyTorchCon? We too! 🙋 Visit us at booth D6 and don’t miss these events:
🔷 Keynote: MAX and Mojo: The Best Way to Extend @PyTorch — 10/20 @ 9:35 AM PT https://t.co/8PA7w5pjAi
🔷 Demo: Scaling AI Across Devices: ExecuTorch — 10/20 @ 1 PM PT https://t.co/NbgxlOqbux
AI teams face two problems at once: compute is hard to get, and the hardware they can get is splintering across a growing wave of chips and accelerators. Every chip ends up needing its own software stack.
In his AI Engineer World’s Fair 2026 talk, Modular's Chief Scientist Abdul Dakkak explains why we rebuilt the inference stack from scratch and how it runs fast across all of that hardware: https://t.co/2iq9FjS9vO
A language becomes an ecosystem when its community starts building the libraries everyone else relies on. That’s happening with Mojo and MAX, and we want to support more of it.
Meet the first Modular Community Grant cohort: six community-built Mojo and MAX libraries, funded by Modular, covering reinforcement learning, GPU physics, and developer tools.
https://t.co/Qqwwykbymi
The best inference config depends on your model, your hardware and your traffic, and all three keep changing. Settings that were ideal last week are rarely the right ones today.
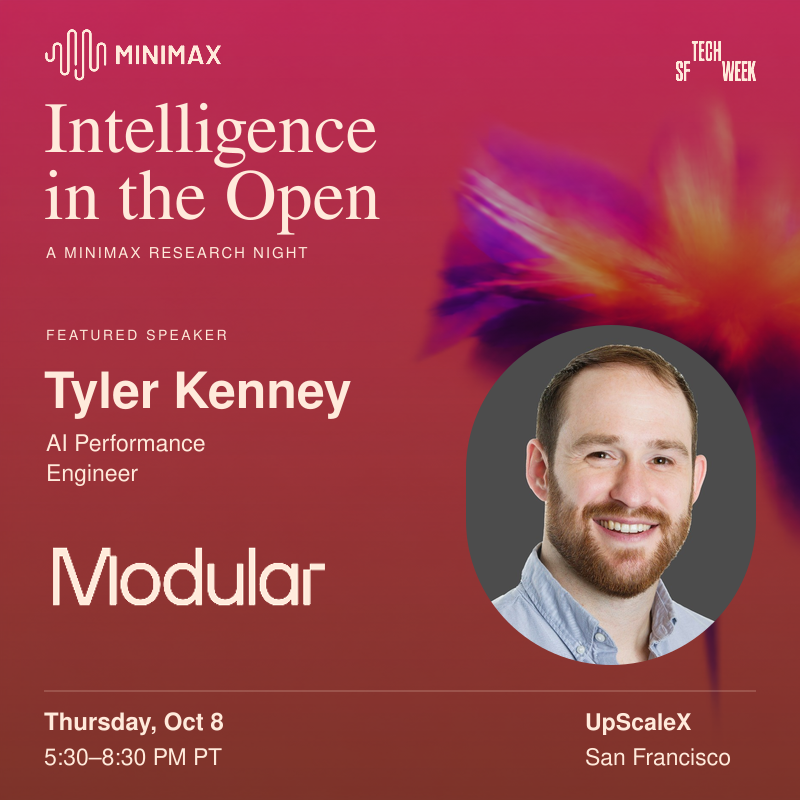
Tonight at @MiniMax_AI's #SFTechWeek research night, Modular AI Performance Engineer Tyler Kenney is talking about self-tuning ML inference systems, exploring how we can teach inference systems to tune their own settings.
📍 UpScaleX, San Francisco
🗓 Thursday, Oct 8 · 5:30–8:30 PM PT
RSVP: https://t.co/RvhZDcNwn3