Hey @X algorithm.
I’m looking to #connect with people who work with AI every day and keep losing the context when they switch tools.
People into:
• Claude, ChatGPT, Codex
• notes that an AI can actually read
• agencies and small teams
• building products, not demos
• context that survives the next model
If that’s you, reply with what you’re building.
Too many subscription variants for X, Grok, and Cursor. It’s chaos.
Speed up the release of ONE cheap plan so more people actually discover your products.
Then raise the price once you’re at Anthropic’s level — or above it.
Simple beats complicated @elonmusk@SpaceXAI@bot@cursor_ai
Anthropic just added two commands to the claude-api skill in Claude Code.
/claude-api build-eval builds a test set for your app.
It asks for real examples, shows them to you, and checks that the grader scores the way you would.
/claude-api hillclimb then improves the app one change at a time. It keeps part of the tests hidden. If a change only helps on the tests it has already seen, it rolls it back.
Their example is a support bot tested on 44 tickets.
Cost dropped to about a fifth, and accuracy on the hidden tickets went from 78.6% to 90.5%.
For me the hidden set is the useful part. Most of us tweak a prompt until it works on the three examples we tried.
@ivanfioravanti We are at a turning point, or a major shift.
- affordable pricing
- speed
- intelligence
- autonomy in task execution
- few usage restrictions
@ahamam101 I don't think so, but it's just a gut feeling. Granted, Opus 5.5 has narrowed the gap with Fable 5.1, which needs to go back to being the Gigachad of Anthropic models.
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
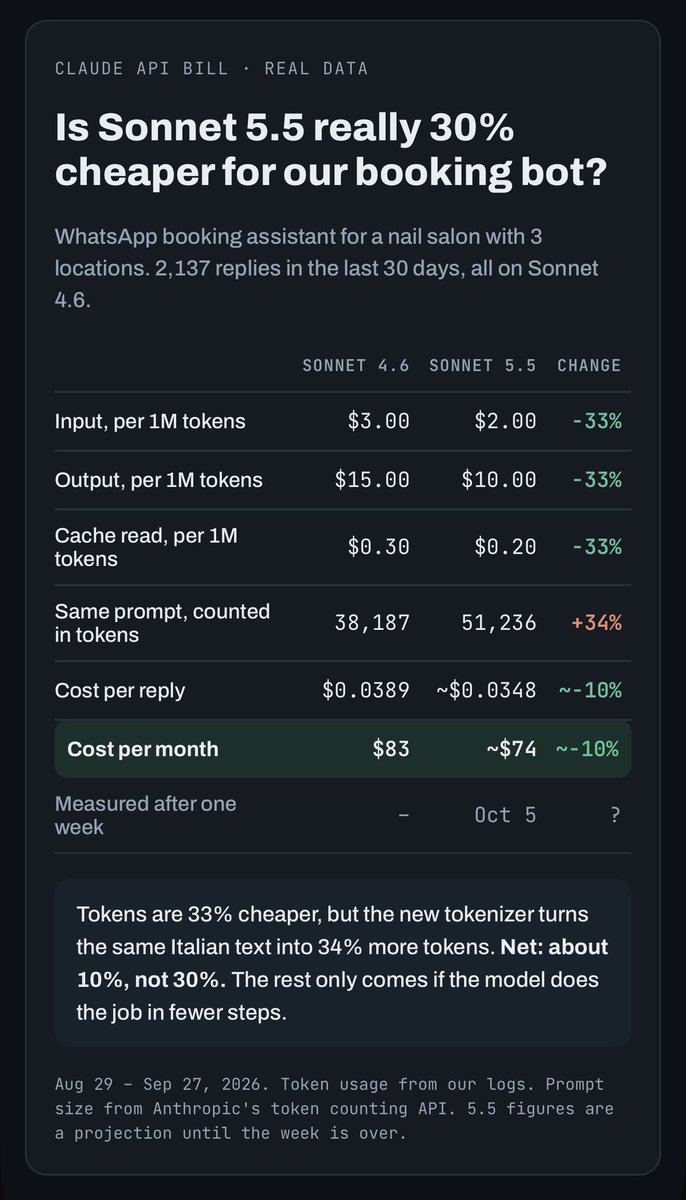
Anthropic says the new Sonnet 5.5 costs up to 30% less per task.
Before switching our WhatsApp booking assistant, I ran the numbers. It answers about 70 messages a day for a nail salon with three locations.
The price per token is 33% lower. But the new tokenizer reads our Italian prompt as 51,236 tokens instead of 38,187. Same text, 34% more tokens.
So the saving I expect is about 10%, not 30%. Around $83 a month down to $74.
The 30% only shows up if the model finishes the job in fewer steps. I can't calculate that, so I switched today and I'm measuring it for a week.
Real numbers next Monday.
We enjoyed ourselves this weekend 🤩
Who would like to connect with me to discuss:
📈 Saas
🔝 Startups
💡 Niche Ideas
🤖 AI
🧠 Second Brain
💰 Entrepreneurs
Let’s connect!
@trq212 Same thing here.
The prompt is one line. The work is “look at these three repos first, then the notes from last week, then don’t repeat that mistake.”
Pain is when that pile doesn’t follow you. New chat, new model, teammate on ChatGPT: everyone starts from zero again.
📂 HOW I USE COBRAIN
┃
┣ 📂 Mine
┃ ┣ decisions
┃ ┣ constraints
┃ ┗ stuff I refuse to re-explain
┃
┣ 📂 Shared
┃ ┣ client
┃ ┣ project
┃ ┗ team notes
┃
┗ 📂 Same context in
┣ Claude
┣ ChatGPT
┣ Claude Code
┗ any AI that speaks MCP
I talk to Claude.
A teammate talks to ChatGPT.
The notes are the same.
Nobody starts over.
Cobrain is almost in the Claude and ChatGPT app directories.
ChatGPT: in review for a week.
Claude: approved in two days. Then stuck, because I used the oldest form. Waiting for Anthropic to fix it.
Soon you'll find it right inside the app. One memory that Claude and ChatGPT share, so you stop explaining things twice.