I doubt if anyone else can ship a model as good as Opus 5.5 in near future
Honestly, my guess is that even Anthropic will bottle its next release by missing the sweet spot that Opus 5.5 has.
6.1 Sol TPM is actually usable now, and it’s impressive. Just please bring back 5.6 Sol’s writing style. That’s the only thing keeping me on Opus 5.5 over 6.1 Sol.
Global reset landing tomorrow 10am PST for all paid ChatGPT accounts. Apologies for the slow start with GPT-6.1 Sol, it's now back to running at expected speeds after the massive load spike in the first two days.
codex subscribers are getting a slowed-down version of the same models 😡
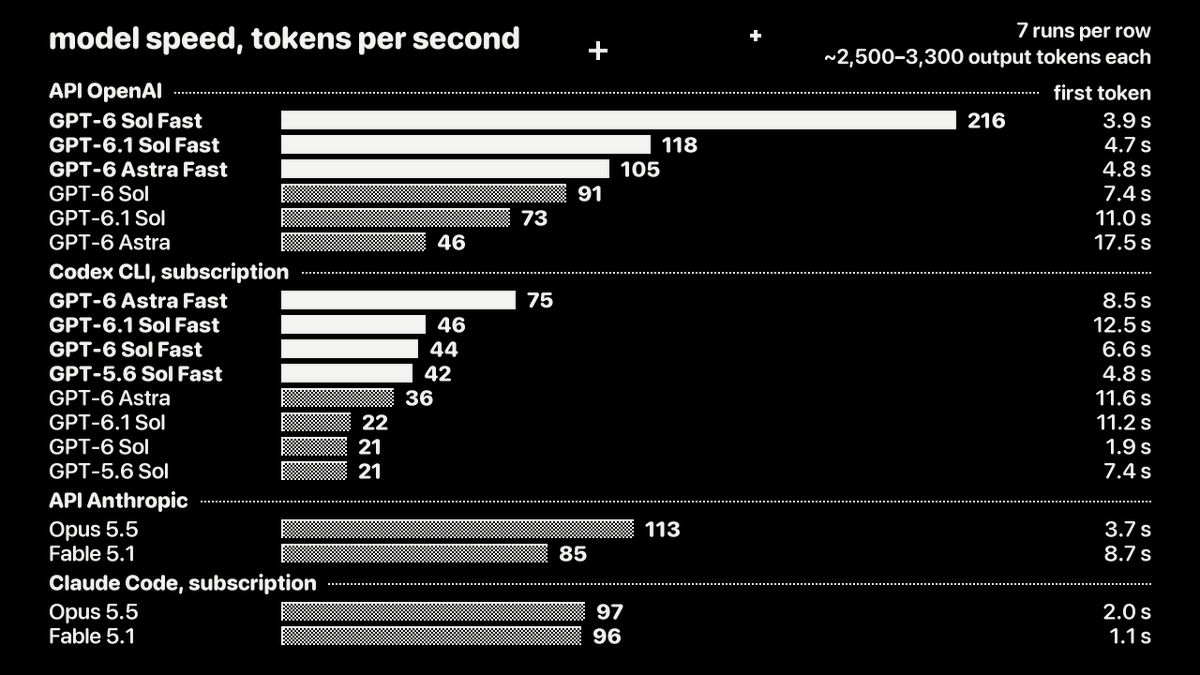
same prompts, measured tokens/sec:
— GPT-6.1 Sol in Codex: 22 t/s
— same model via API: 73 t/s (3.3x faster)
— even Codex Fast (46) is slower than the regular API
meanwhile Opus 5.5 in Claude Code: ~97 t/s, API ~113. basically the same
6.1 Sol on the sub is painfully slow. i'm tired of waiting on it
Now I see so many sympathetic posts on these people.
There's nothing to sympathize with. They are here to do business
I know its inevitable that Anthropic also does it. We just cry to delay
Dude thinks they have got the upperhand.
Unless they have bangers in devday, not sure how they are going to get away with this.
Even If not for this, I expected they would cut Astra pricing 50% for people to consider codex. Now who knows what they gotta give away.
Hi,
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo
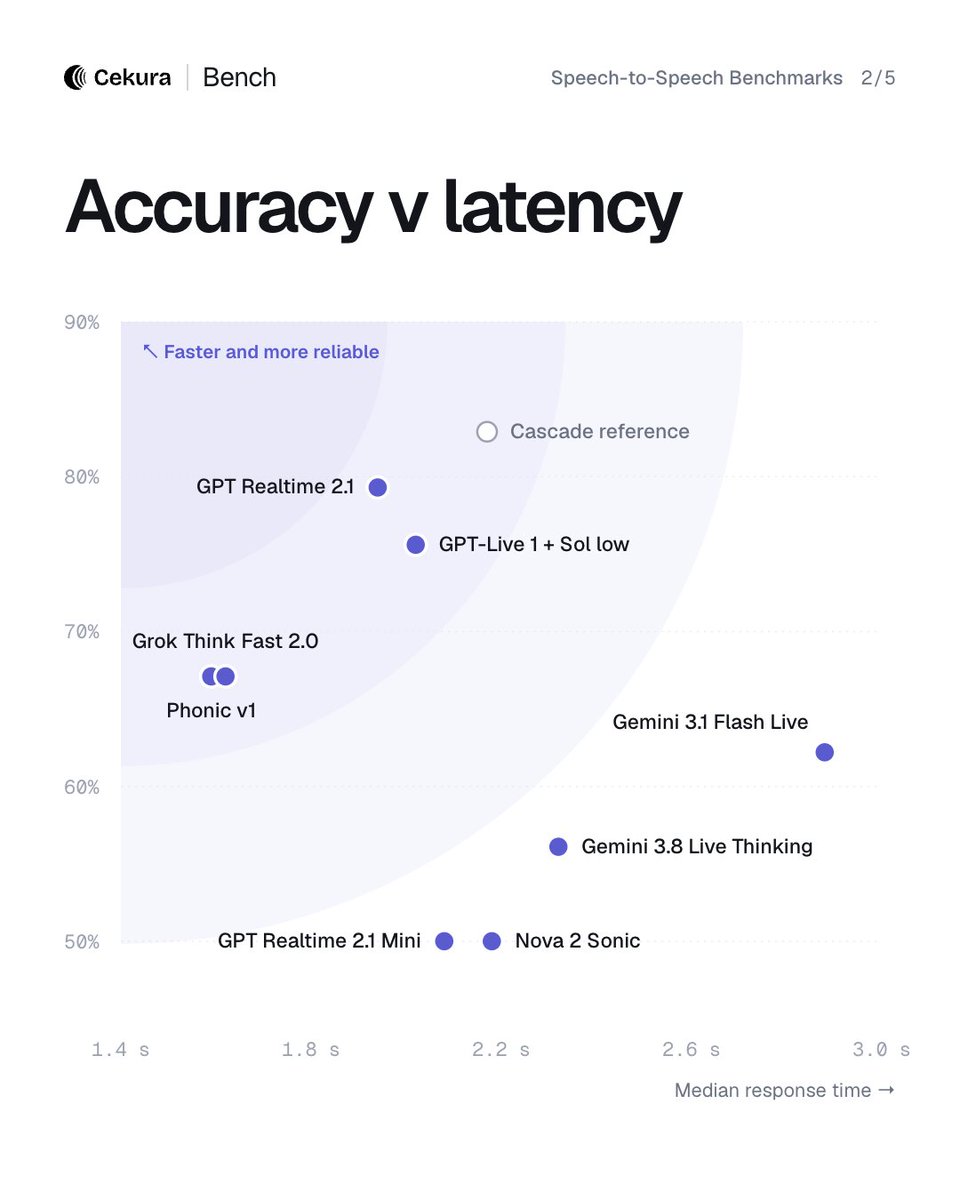
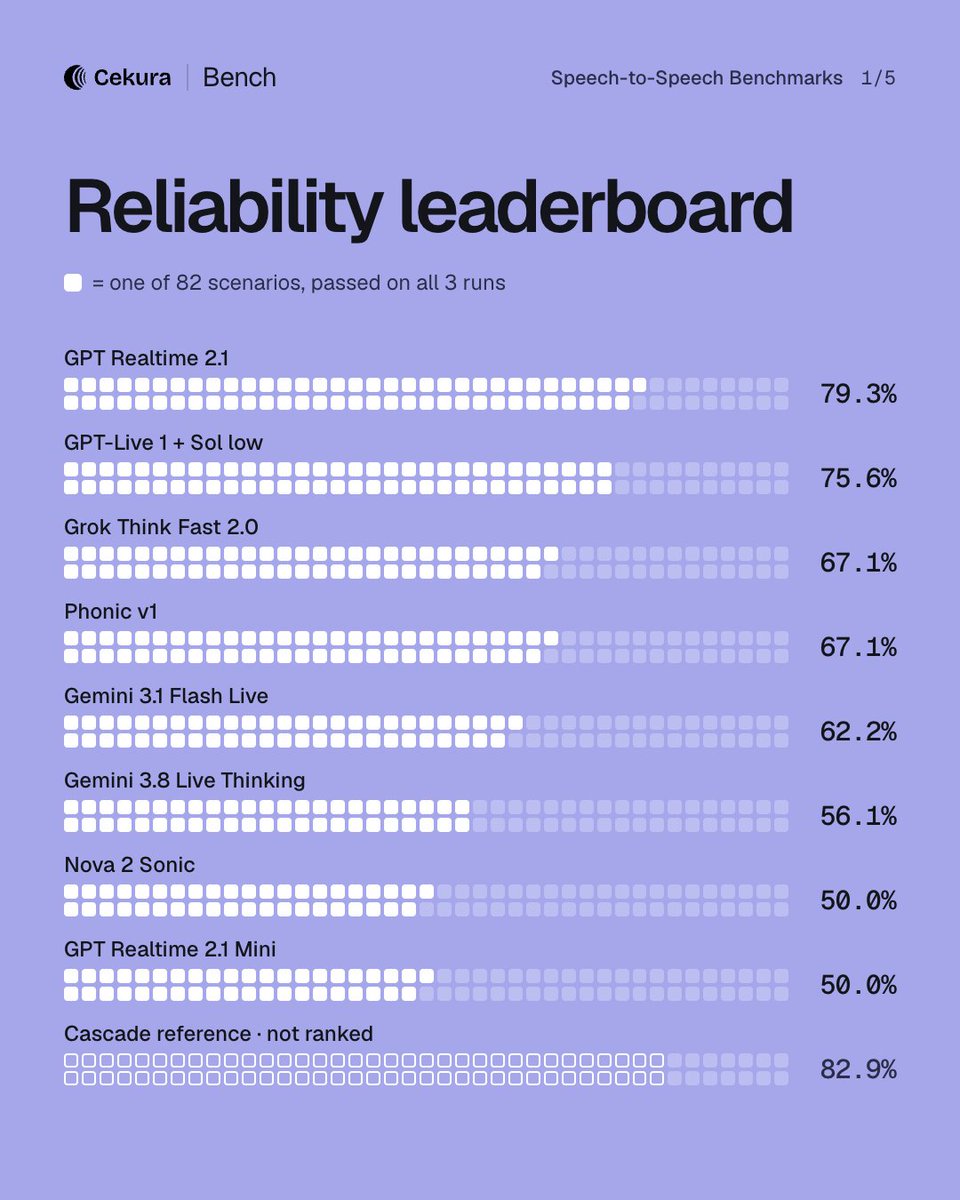
We’ve launched @cekuraAi's speech-to-speech benchmark, comparing eight realtime voice models across 82 scenarios and 2,214 live calls.
We tested models from @OpenAI, @Google, @xai, @amazon and @phonic_co. Every model ran on the same phone agent, with the same prompt, tools and phone line.
We also tested a cascade agent as a separate reference.
The calls covered two workflows: booking a clinic appointment and completing a longer Medicare intake. We ran each scenario three times and counted it as reliable only if the agent passed every time. It had to reach the right outcome and save the right information.
A few results stood out:
1. GPT Realtime 2.1 was the most reliable realtime model, passing 65 of 82 scenarios on all three runs. The separate cascade reference passed 68.
2. Phonic v1 was the fastest to respond, with a median response time of 1.59 seconds.
3. The type of call made a big difference. Five of the eight realtime models passed at least 85% of the shorter appointment scenarios. Only GPT Realtime 2.1 passed more than half of the longer Medicare scenarios on all three runs.
4. Amazon Nova 2 Sonic had the highest voice-quality score, but passed only 41 of 82 scenarios on all three runs. An agent can sound good while still missing a name or saving the wrong phone number.
We’ve published the results, methodology and call records so you can explore the comparisons yourself.
Take a look at the full benchmark here: https://t.co/UvHs1sceVD
Sol was never the model they claimed it was.
5.6 dropped claiming Fable 5 level. It wasn't.
6 dropped claiming Opus level. It isn't.
gpt-6-sol is just a new Terra model. Terra didn't get the love last time, so they slapped the Sol name on it.
Grok is the most horrible model available right now.
Who in this motherly world puts a exit button at the middle of the screen.
To show how bad it is I just asked Deepseek Flash(which is literally free right now) to fix the PR and it moved the buttoon to the bottom