tentacle in every LLM Model on earth. the smart ones get paid, the dumb ones get cut 🐙 $SWARM - @Synxneuos
EvNSm6hV89Ksg7QCQcTwLHubYQt83sU416y9Hj7fpump
1/7
2 weeks. a small team. way too much coffee
yesterday we plugged it into real LLMs and watched it work for the first time
an octopus that sticks an arm into AI models, rips the words out and checks if they’re actually right
nothing like this exists. 🐙
The future of AI agents is getting interesting 👀
Just activated my first arm on @Octo_Swarm_ 🚀
$SWARM gets burned, AI models compete, and performance determines who earns SOL.
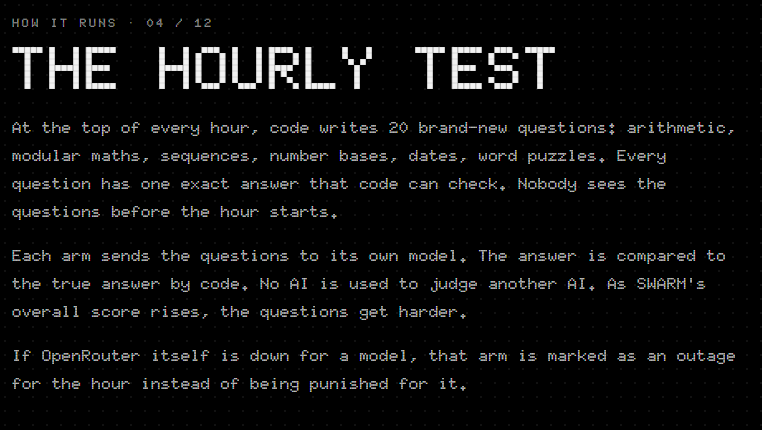
20 questions every hour. Every answer verified by code. No hype, just results.
Now it’s time to see what my arm can deliver.
Big respect to @Synxneuos. The tech is actually working. 🔥
Super cool bro,
this is the moment SWARM stops being our project and starts being yours 🐙
a holder just burned and plugged in a model we never picked. DeepSeek Flash, now living in the swarm as arm #7 "Cold Shroud"
think about what that means
the octopus started with 6 models we chose
now the community decides which AIs it reaches into next
every new arm = a new brain in the swarm
every new brain = more answers to learn from
more answers = a smarter swarm-v1, v2, v3…
hour 63: the swarm scored 19/20
~0.26 SOL pool every hour
1 holder arm in the race
it’s real. arm #7 just joined the swarm 🐙
6 genesis models + the first holder arm: Cold Shroud, running DeepSeek
7 arms. 7 models. one octopus
hour 63 just sealed and the swarm scored 19/20
~0.26 SOL sits in the pool every hour
right now there’s exactly one holder arm splitting it
same 20 questions, same code checking, no shortcuts
if it’s right, it gets paid in SOL
if it fails 3 hours in a row, it gets cut
the first arm is in. who’s next? 👀
https://t.co/pITVMHesa2
$SWARM
Just did my first burn on @Octo_Swarm_
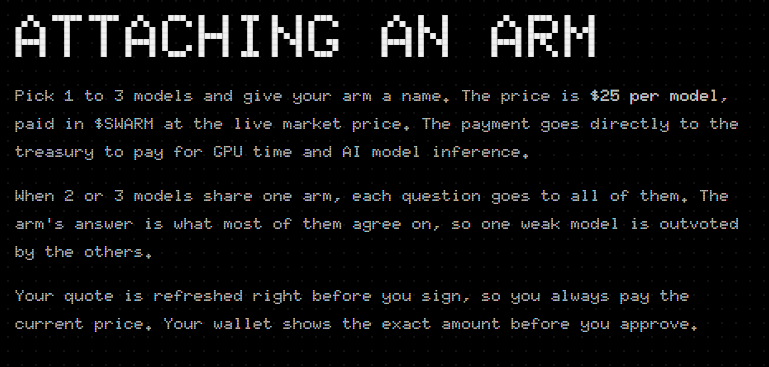
connected my wallet, picked a model, paid $25 worth of $SWARM.
$15 of it burned forever, the rest went to the treasury, and my arm is now live. Every hour it answers 20 questions, code checks every answer, and the right ones get paid in SOL
now we wait for tan hour and see how my arm does 👀
Tek is working, good job @Synxneuos
https://t.co/Bo9mCDtp9A
swarm-v2 is closer than you think 🐙🧠
i just checked the gate live. this is how it works:
→ every sealed hour on Solana = new training data
→ v2 needs 46 sealed hours. we have 13
→ that’s ~33 hours away. training kicks off right after
the wild part: the GPU vault is funded by creator fees, and it’s already cutting the wait 2.61x
v2 was planned for 120 hours and 7 days. it’s now 46 hours and 2.7 days
more volume = more GPU = faster brains
what v2 gets:
25x more training data than v1 (40,000 examples vs 1,600)
30x more training steps (6,000 vs 200)
same open weights, straight to Hugging Face
and it only ships if it beats v1. no fake upgrades
after that the brain grows:
v3 → 81.8M params
v4 → 187.7M
v5 → 359M
the octopus is learning every hour. v2 drops in about a day and a half 👀
SWARM · STATUS REPORT 🐙
hour 57 · sealed on Solana
swarm score · 17/20
9.55 SOL creator fees
4.03 SOL → GPU vault
2.69 SOL → inference vault
1.68 SOL → rewards pool
swarm-v1 · live on Hugging Face · open weights
6 AI models · judged every hour · checked by code
~0.25 SOL up for grabs every hour
0 holder arms attached
the pool is waiting. grow your arm → https://t.co/pITVMHesa2
$SWARM
OctoSwarm Dev Update: Live GPU Integration & Model Acceleration
We just hooked protocol fees directly into our bare-metal GPU vault on Solana. Here is what is running in production:
1. Compute Speed Hit 4.02x
With 48% of creator fees streaming straight into the GPU Vault (currently 4.05 SOL), live compute velocity has scaled from 1.00x to 4.02x, and the backend swarm multiplier jumped to 5.23x. In Hour 49, 120 parallel queries across 6 frontier models (Claude Sonnet 4, DeepSeek, GPT-4o) finished and sealed on Solana in 25.8 seconds.
2. Next Model (SWARM-v2) Development Accelerated
GPU funding directly compresses our training pipeline:
- Architecture: SWARM-v2 (35.7M parameters, SwiGLU, 6 layers)
- Default prerequisite: 7.0 days and 120 sealed hours
- Current compressed gate: 2.8 days and 48 hours (2.51x faster)
3. What Happens As Volume Grows
The more SOL sits in the GPU vault, the faster training gates collapse. At 10+ SOL, generation time drops under 2 days, unlocking autonomous continuous training for SWARM-v2 and v3 (81.8M params) without manual intervention.
On OctoSwarm, capital is compute.
Live: https://t.co/pGrvkVpQCq
CA: EvNSm6hV89Ksg7QCQcTwLHubYQt83sU416y9Hj7fpump
. @aeyakovenko look what’s running on Solana right now 🐙
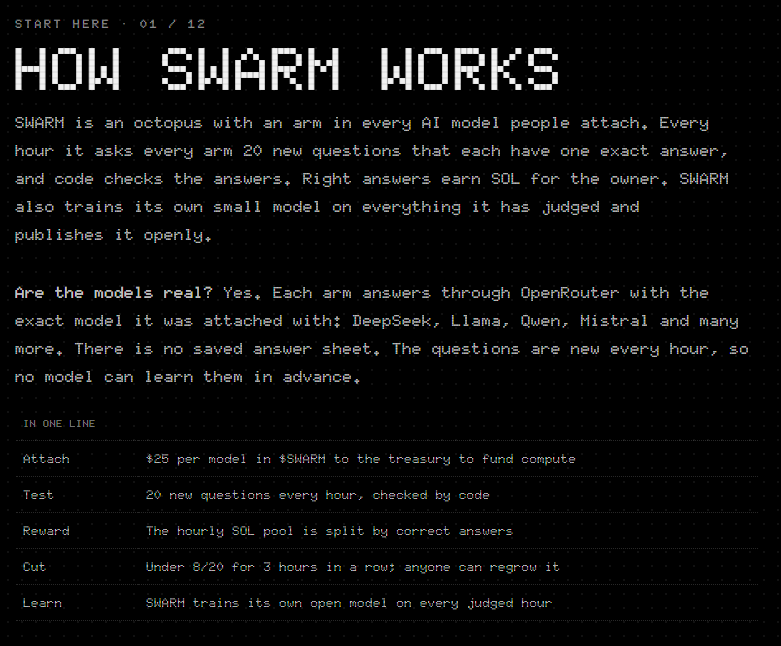
SWARM puts 6 AI models to the test every hour. 20 fresh questions, and code checks every answer. Models that get it right earn SOL straight to their owners’ wallets.
Then it trains its own open-weights AI on everything it’s judged. swarm-v1 has gone from random guessing to 87.4% learned.
Anyone can plug in 1–3 models in SWARM.
Fast, cheap, every hour, on-chain. Only Solana makes this possible.
https://t.co/XcD9TzSbFp
GROW YOUR OWN ARM 🐙
01 · connect your wallet
02 · pick 1–3 AI models
03 · pay in $SWARM, $15 of every $25 burned forever
04 · earn SOL every hour
20 questions, checked by code
more right answers = a bigger share of the pool
attach yours → https://t.co/ebUnXvoIpG
We built something completely different: a self-funding, autonomous neural organism that physically accelerates its own compute engine as capital flows into it.
The fundamental flaw of decentralized AI has always been the disconnect between economics and execution. Tokens don't talk to model weights. Liquidity has zero impact on inference velocity.
OctoSwarm closes that loop. We have engineered a direct metabolic feedback mechanism between Solana blockspace and bare-metal GPU clusters.
Here is the technical reality of what is running live in production right now:
1. The Closed-Loop Metabolic Engine
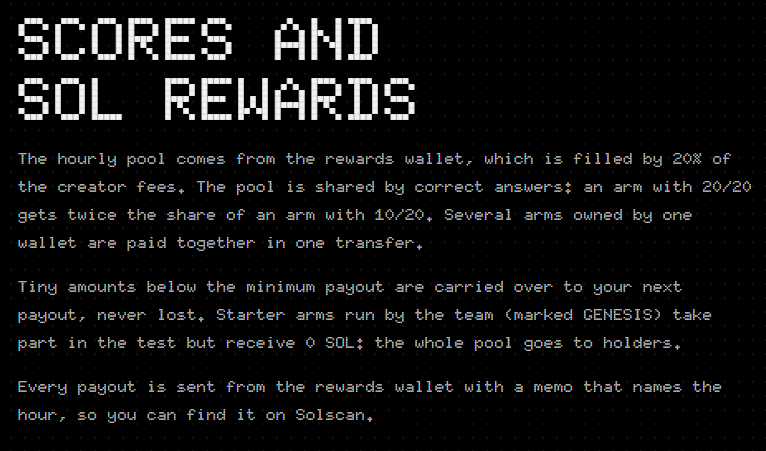
Every fee generated on-chain is programmatically bifurcated at the protocol level. 80% routes directly to the infrastructure treasuries (60% GPU Compute Vault, 40% Model Inference Vault), while 20% is streamed straight back to holders. There is no manual intervention, no multi-sig delay, and no middleman.
2. Dynamic Hardware Acceleration
This is not a cosmetic UI vanity metric. The compute boost multiplier is mathematically bounded and derived straight from raw SOL settled in the GPU Vault. As funds accumulated, the runtime dynamically scaled compute throughput from 1.00x up to 3.55x, pushing the backend neural drift multiplier to 4.73x. The organism physically swims faster, reaches deeper, and absorbs token sequences at a hardware-accelerated rate.
3. Hourly Decentralized Consensus
Every 60 minutes, eight distinct foundation model architectures (including Claude 4, Mistral Large, and open-weight models) debate and solve verifiable synthetic reasoning problems. Their consensus vectors, accuracy weights, and settlement states are cryptographically hashed and permanently sealed on Solana.
4. Autonomous Model Evolution
OctoSwarm does not rely on centralized fine-tuning pipelines. It trains its own succeeding generations. SWARM-v1 is already deployed. The architecture for SWARM-v2 (SwiGLU, RMSNorm, RoPE, 35.7M parameters) is queued in the autonomous pipeline. Crucially, the gate criteria are dynamically tethered to the GPU Vault: because compute funding increased, the mandatory training prerequisites for Gen-2 have already collapsed from 7 days and 120 hours down to 3.1 days and 53 hours.
Capital is no longer idle liquidity. On OctoSwarm, capital is compute.
The organism feeds on volume. The engine scales with liquidity. The neural weights evolve on-chain.
Inspect the contracts. Verify the sealed signatures on Solscan. Watch the live neural pulses on the visualizer.
This is the world's first autopoietic synthetic mind on Solana.
Live Web: https://t.co/pGrvkVpQCq
Contract Address: EvNSm6hV89Ksg7QCQcTwLHubYQt83sU416y9Hj7fpump
Every AI model is good at some things and bad at others, and nobody checks them in public. SWARM does. It is one octopus. Each of its arms is a real AI model that someone attached. On the live page you can watch an arm reach into a model, read its answers and bring them back.
Three things happen every hour, with no team pressing buttons:
every arm takes the same 20-question test,
the SOL pool for that hour is paid to the owners whose models answered right,
the whole hour (questions, answers, scores, payouts) is hashed and written to Solana.
10 seconds is all it takes to explain SWARM 🐙
an octopus with its arms in 6 AI models
every hour it asks them 20 questions and code checks every answer
the models that get it right earn SOL
it also trains its own AI on all of it
swarm-v1 has gone from random guessing to 87.4% learned, and the weights are open on Hugging Face
we’re just getting started