@pankajdoharey sorry about that. which model, and what error did opencode show on the failed calls? DM us your account email and we'll look at your requests
Jensen closed GTC Berlin by setting up Hermes Agent in one prompt.
We pointed Hermes at DeepSeek V4.1 Flash UltraFast on OpenGateway. One prompt: it wrote code + tests, caught its own ß bug, fixed it. 6/6 green in 18s, under a cent at list price.
https://t.co/uuIut0rBM4
At 1M tokens, attention accounts for 94.9% of estimated FLOPs.
At 4K tokens? Just 12.7%.
Why the massive difference?
Full attention scales quadratically with context length.
Same model. Much longer context. A very different compute profile.
Here's why.
@handikawisnu@rohan__shetty 848 is the peak we've measured, not what every request gets. if yours are coming in way lower, DM us your numbers and we'll dig in
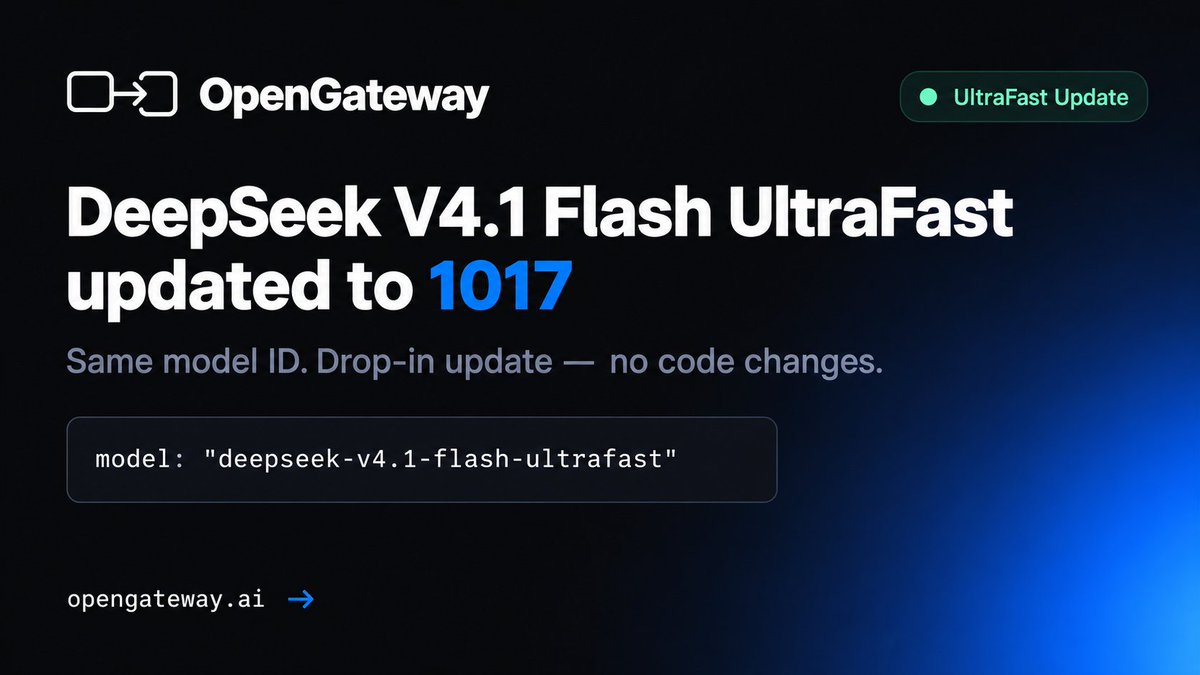
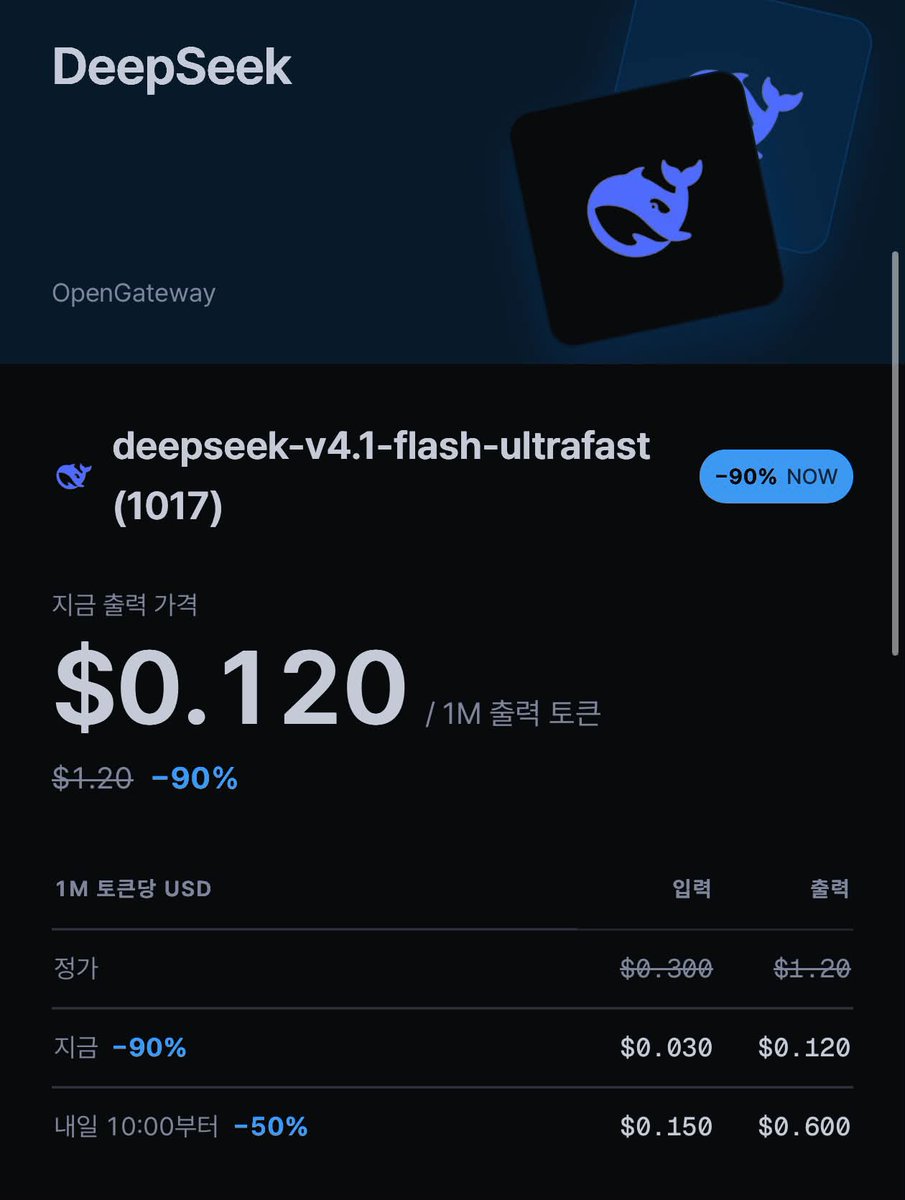
DeepSeek V4.1 Flash UltraFast is now on the 1017 update.
Same model ID, no code changes. Weekends 90% off through Oct 31 (KST).
DeepSeek V4.1 Flash UltraFast 1017 버전 업데이트
모델 ID 그대로, 코드 수정 없이 바로 적용
https://t.co/pQg3LAu7gg
Been experimenting with @OpenGatewayai and it's been interesting so far. Worth a look if you like trying different AI models without jumping between platforms.
Reverse engineering at UltraFast speed.
REA × OpenGateway: REA breaks a binary into 32 inquiries, and high-TPS UltraFast models answer them in parallel.
Try DeepSeek V4.1 Flash UltraFast & GLM-5.3 Flash UltraFast. Up to 90% off on weekends & idle hours, until Oct 31.
https://t.co/LpFFqHhoWy
#rea
DeepSeek Harness based personal agent, a self-hosted AI teammate that remembers you, messenger gateway and TUI with ultrafast
deepseek-bot: https://t.co/qBVpLdMx8X
ultrafast deepseek model: https://t.co/qrWCs4UWgo