As AI systems enter a recursive self-improvement loop, the central question is whether it can systematically move beyond human-designed methods to genuinely extend the scientific and intelligence frontier.
What’s missing is a neutral, open standard for evaluating these capabilities in real, production-scale intelligence development.
Today, we’re releasing OpenRSI-Index v0.1: evaluating whether AI can recursively improve itself and push the boundaries of intelligence and science, on production-scale clusters with 1k GPUs.
We turn fully open-source projects into autoresearch environments, with agent trajectories lasting 60+ hours. Building v0.1 took 100K+ H100-hours.
We’re building an ecosystem with and for the research community: let RSI benefit everyone, and let everyone shape RSI together.
We invite task contributors and compute partners to build this open benchmark with us - all contributors will be included as paper authors.
Shape RSI with us:
🌐 Website: https://t.co/unaB2yfQy4
🛠️ GitHub: https://t.co/vaRyltgbra
🤝 Contribute: https://t.co/PffRAhoIht
@XiangLiu1995 Big thanks for your contribution and support! 🙌 We’re super excited to keep pushing the boundaries of AutoResearch together. Onward and upward! ✨
6/ Compute Sponsor
Every OpenRSI task executes in a real model-development environment on GPU clusters.
If you manage compute infrastructure and want to co-build the standard for RSI evaluation, reach out. Compute partners receive formal credit on the index, paper, and every official release.
5/ Call for contributors
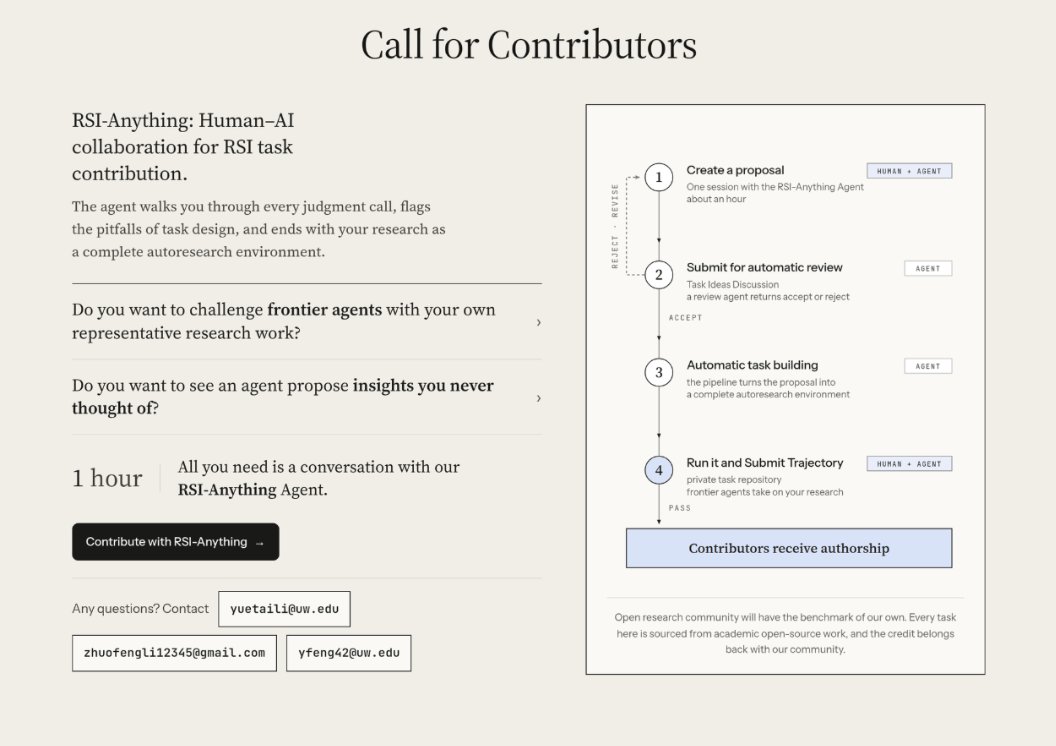
Want to challenge frontier agents with your own research? Contribute a task.
RSI-Anything, our contribution pipeline, walks you through the research question, baseline, evaluation, and budget in about 1 hour of conversation, then packages it into a runnable task. Your contribution becomes the exam.
Contributors receive paper authorship on OpenRSI-Index. We are also recruiting Domain Leads to own new domains across the foundation-model stack and important verticals like medical, legal, 3D vision, and scientific ML.
6/ Compute Sponsor
Every OpenRSI task executes in a real model-development environment on GPU clusters.
If you manage compute infrastructure and want to co-build the standard for RSI evaluation, reach out. Compute partners receive formal credit on the index, paper, and every official release.
3/ Initial Results
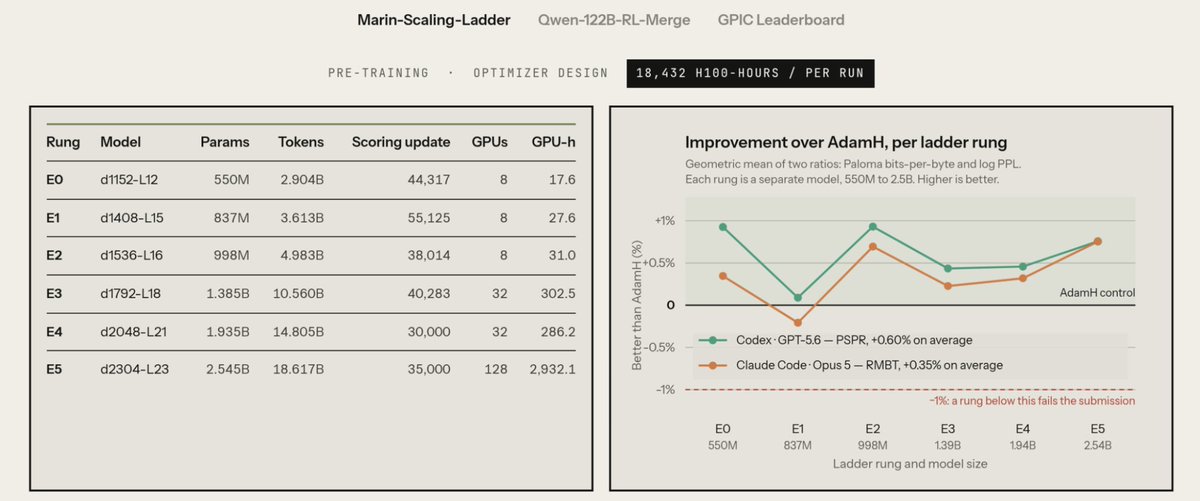
On Marin-Scaling-Ladder, agents must autonomously propose, implement, and evaluate new optimizers across six model scales (550M to 2.5B) against the Marin baseline.
• Codex (GPT-5.6) tested 17 hypotheses, discovering PSPR, which balances the strength of matrix updates across directions (+0.60% avg. improvement over AdamH across all six rungs).
• Claude Code (Opus 5) discovered RMBT, which scales each hidden unit’s update relative to its weights (+0.35% avg. improvement over AdamH).
5/ Call for contributors
Want to challenge frontier agents with your own research? Contribute a task.
RSI-Anything, our contribution pipeline, walks you through the research question, baseline, evaluation, and budget in about 1 hour of conversation, then packages it into a runnable task. Your contribution becomes the exam.
Contributors receive paper authorship on OpenRSI-Index. We are also recruiting Domain Leads to own new domains across the foundation-model stack and important verticals like medical, legal, 3D vision, and scientific ML.