Introducing Overmind. The training platform for agents.
Overmind trained models across biomedical, legal, and engineering tasks beating the frontier and achieving:
• 7x better accuracy
• 20x cheaper usage
• 28x less hallucinations
Train your own: https://t.co/AEBRXmUbWk
Method, cost basis, calibration tables and every caveat are in the write-up: https://t.co/xcwXnyoE4j
Train one on your own labels: Train one on your own labels: https://t.co/AEBRXmTE6M
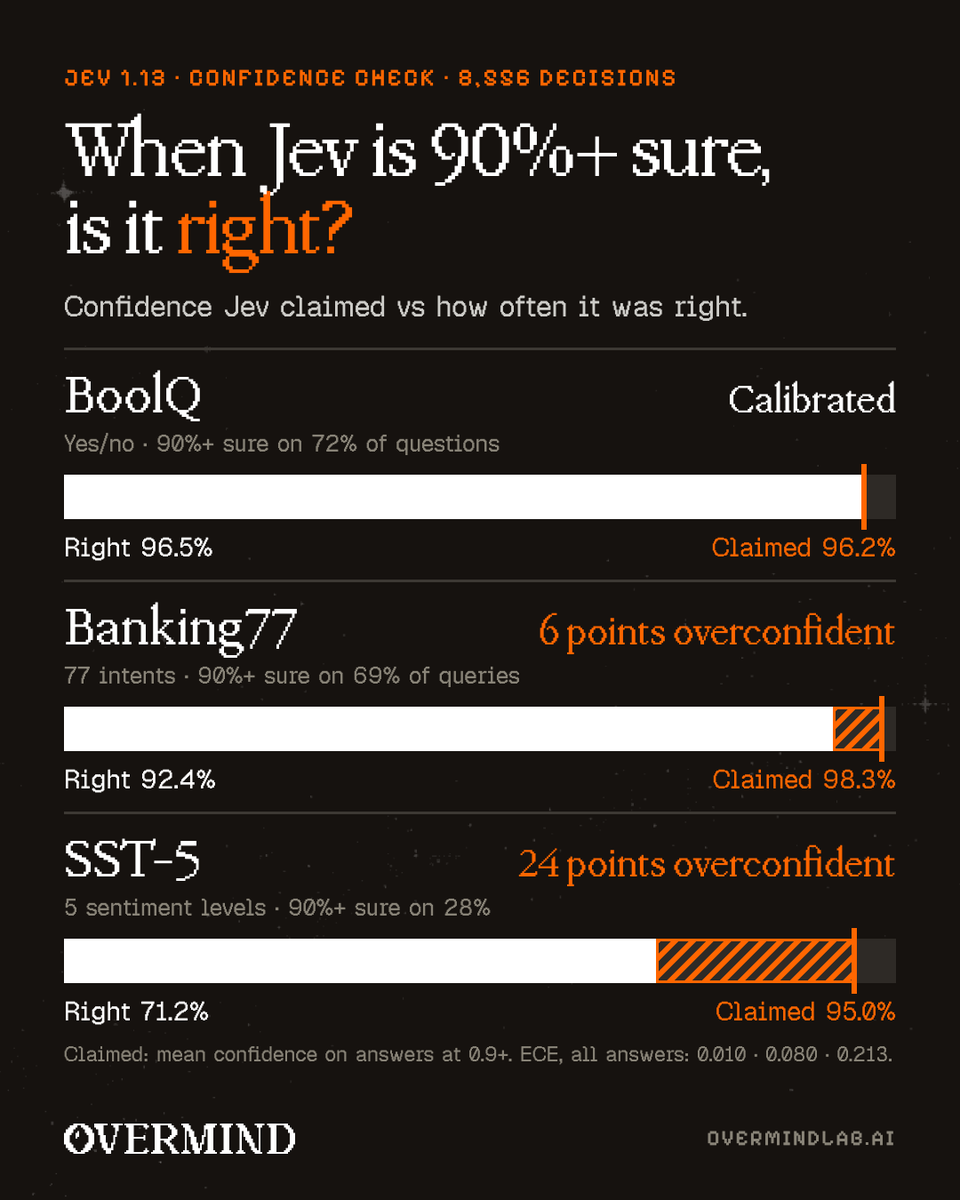
Jev's confidence is its strongest feature, so this run measured it on all 8,556 answers.
When 90%+ sure on yes/no questions, Jev was right 96.5% of the time. Calibrated.
• 77 banking intents: claimed 98%, right 92%.
• 5 sentiment levels: claimed 95%, right 71%.
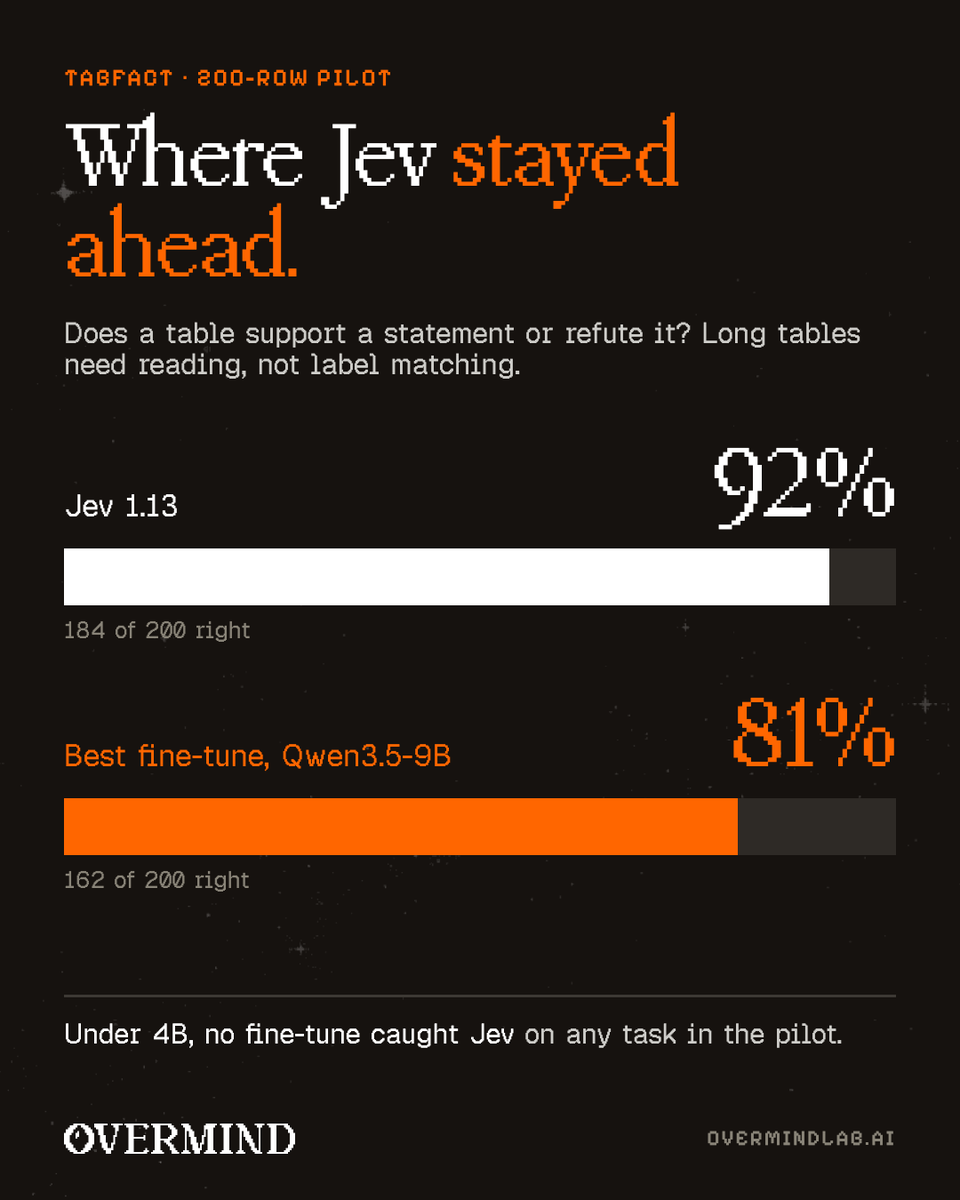
Where Jev stayed ahead: TabFact (200-row pilot). Jev 92%, best fine-tune 81%. Sub-4B models trailed Jev on every pilot task.
Rent the generalist. Train the specialist once the labels exist.
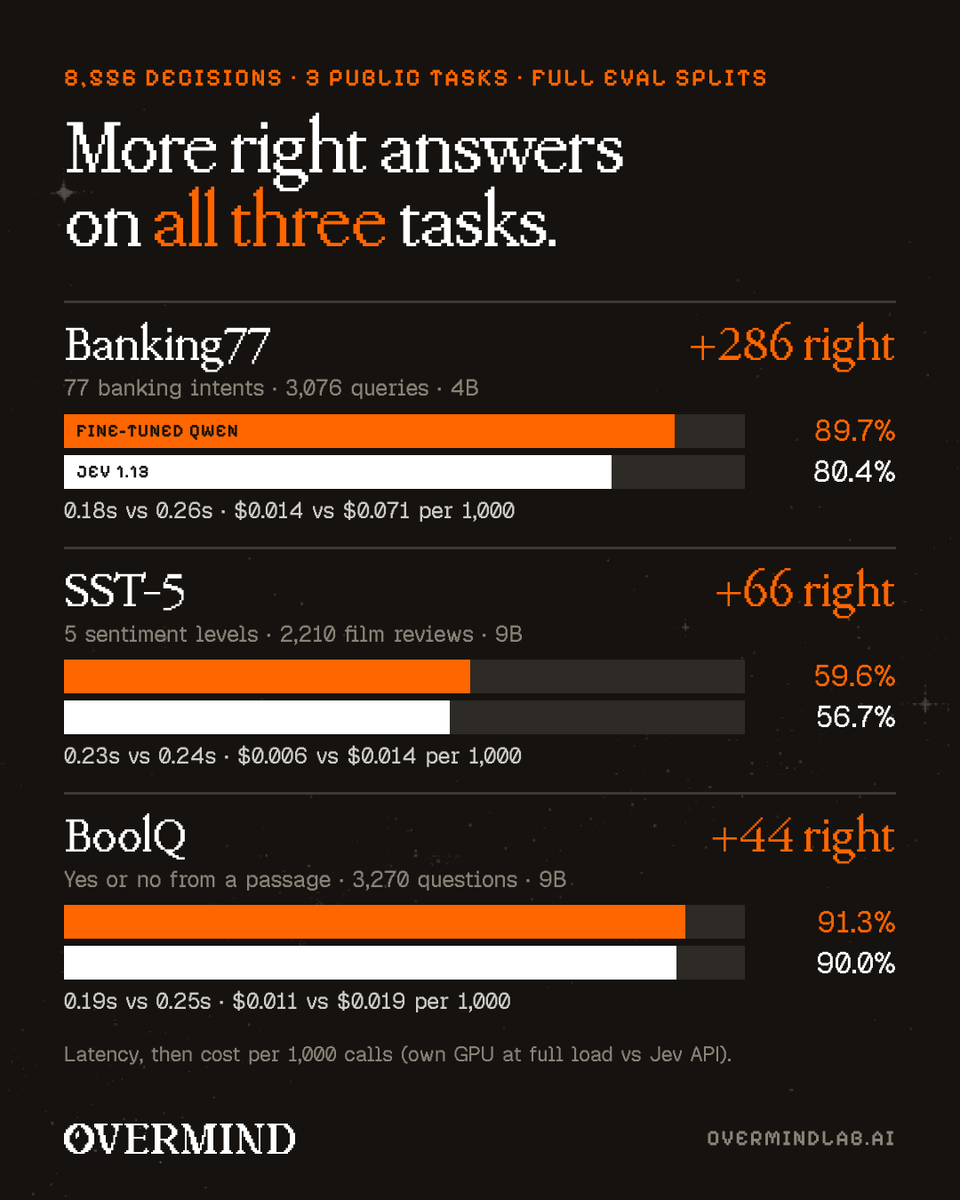
Three public tasks, full eval splits, 8,556 examples.
Jev 1.13 zero-shot with label descriptions.
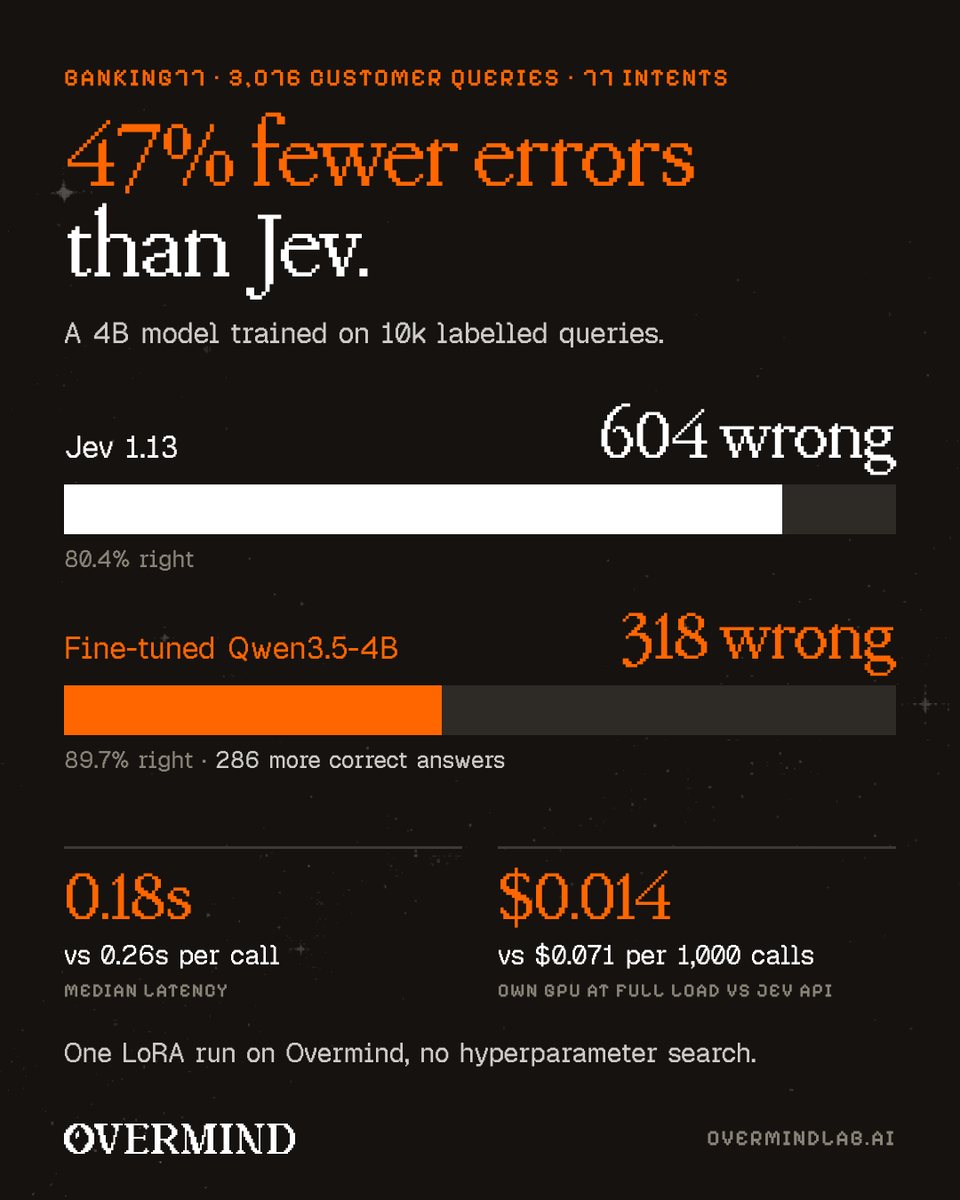
• Banking77: 89.7% vs 80.4%
• SST-5: 59.6% vs 56.7%
• BoolQ: 91.3% vs 90.0%
Lower latency and lower cost per call on all three.
Clef-flash is Qwen3.5-9B, post-trained by Cloudflare to make any decision you describe. The specialist here is Qwen3.5-4B, trained on one task's labels.
Same model family. The difference is the data.
Jev vs Clef settled one thing: a model anyone can rent is not a moat. The labels are.
A 4B model trained on 10k labelled banking queries made 47% fewer errors than Jev.
One LoRA run, no hyperparameter search, under an hour on Overmind.
we have spent years making models bigger
maybe the next leap is making them better at one thing.
smaller, specialised models trained on your own data can be cheaper, more accurate, and actually yours
When intelligence becomes a commodity specificity becomes the advantage.
The frontier is not the model that can do everything but the model that does your thing best.
Everyone’s building on the same models. Time to turn your team into a frontier lab:
▸ Star the repo: https://t.co/AEBRXmUbWk
▸ Run the cloud version: https://t.co/6gU3GXT2Ky
▸ Read more: https://t.co/x14eEGxYJF
@NovaXCode Yup. @NousResearch built the open agent. Learns, keeps skills, isn't locked to one model. For the people. @OvermindLab continues that ownership. An open-source platform for continuously improving agents.
The future belongs to those that own and build their own intelligence.
Keep your tracing stack. Train from it.
Overmind now imports traces from @langfuse, @LangChain (LangSmith), @braintrust and Galileo. Connect a project and it backfills the history, then keeps syncing.
Those traces become eval sets and training data for a model you own.
Introducing Overmind. The training platform for agents.
Overmind trained models across biomedical, legal, and engineering tasks beating the frontier and achieving:
• 7x better accuracy
• 20x cheaper usage
• 28x less hallucinations
Train your own: https://t.co/AEBRXmUbWk
agent builders are about to realize that production traces are gold.
the agents that log failures, evaluate properly, and turn real usage into training data will compound way faster than prompt only wrappers.
pretty interesting direction.