My [email protected] reward is in: 2.35 NEAR 💚
The next phase of NEAR@X is coming.
Join me on https://t.co/4oaKTzR1Md with my referral link:
https://t.co/O51I8NEp3J
The world's stock of high-quality public text sits at roughly 300 trillion tokens.
Stanford's 2026 AI Index says models could exhaust it by 2032.
Perceptron's 800K+ nodes generate fresh real-world data daily, a supply that keeps replenishing itself.
.@OpenAI just signed a $250M, five-year deal with News Corp for licensed text data.
That's the price of one publisher's archive, once.
Perceptron's node network generates live data every day, without an expiring contract.
Ask a crowdsourcing platform for a licensed doctor's read on a dataset. Most can't deliver it.
A token-incentivized network doesn't have that ceiling.
Contributors self-select by expertise.
Perceptron's upcoming data questing platform is being built to surface specialists, not just volume.
Enterprise data won't fix AI's bottleneck.
No Fortune 500 is opening its vault. That data is their moat.
The next edge comes from outside those walls.
800K+ nodes, collecting real-world signal no closed data room can reach.
Most node networks stop at the desktop.
Perceptron runs on either your browser or mobile phone.
Activating these "everyday devices" is critical.
Wider device coverage means a wider data surface, and a harder network to replicate.
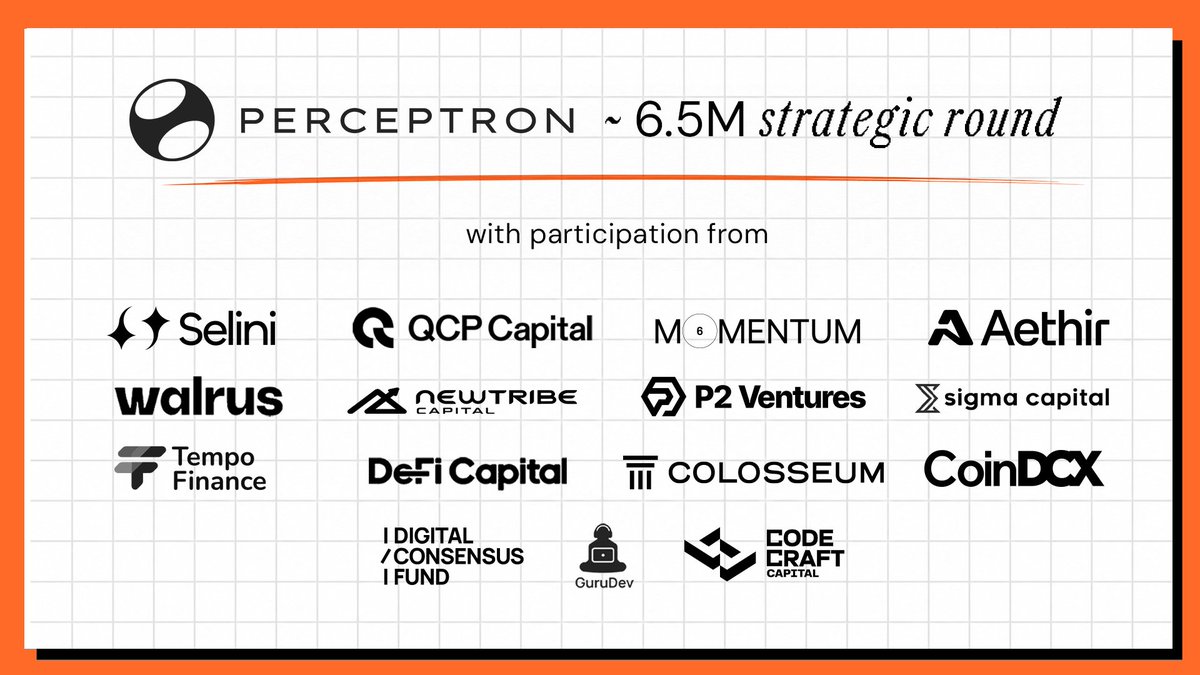
We're thrilled to announce that Perceptron has closed a $6.5M strategic round.
Centralized scraping is hitting diminishing returns on cost and quality. Closed data partnerships are out of reach for most AI teams. The real bottleneck for AI right now sits at the data layer.
Perceptron compresses global data collection into one mesh: idle bandwidth, unique datasets, and domain expertise from a network already live across 800K+ nodes in 150+ countries, with 300K+ daily active contributors.
This round funds our data-questing platform, letting AI companies commission specific, high-value datasets directly from that network and cutting the timeline from request to delivered dataset down to days.
The network continues to expand.
Join us.
→ https://t.co/nXcXB5JrxY
Data freshness gets the headlines.
Data verification is the harder problem.
Anyone can collect a dataset.
Proving where it came from, who collected it, and whether it holds up takes a network, not a script.
That's the part most AI data pipelines skip.