📊 Results: StackedDiffusion achieves strong performance on all metrics, surpassing existing methods. Human evaluators prefer it by wide margins, even surpassing ground-truth images in some cases.
5/n
✨ Advantages: StackedDiffusion outperforms baseline approaches and state-of-the-art multimodal LLMs. In fact, users even prefer it to human-generated articles in 30% of cases, demonstrating its effectiveness.
4/n
⚖️ Evaluation:
• Evaluated on 25 diverse benchmarks encompassing image, video, audio, point cloud, depth, IMU, and fMRI.
• Shows excellent performance on tasks like captioning, VQA, reasoning across modalities.
6/n
📊 Results:The model effectively integrates visual and textual information, resulting in clinically correct radiology reports. It showcases the potential for conversational AI tools in transforming the radiology workflow, saving time, and improving report quality.
6/n
RaDialog: A Large Vision-Language Model for Radiology Report Generation and Conversational Assistance
Paper Link: https://t.co/gbimFTfyYc
📚 Paper Summary:
A thread👇:
1/n
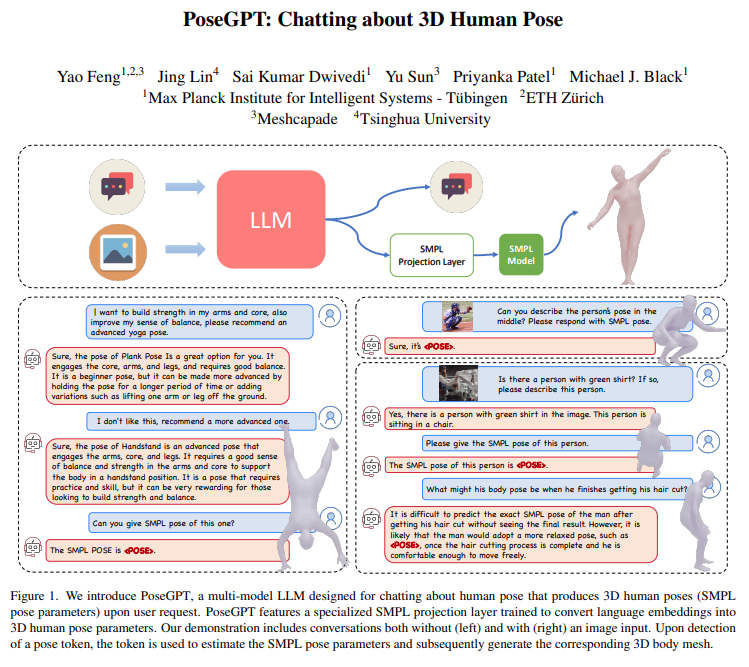
Once LLMs understand SMPL poses, they can utilize their world knowledge for more advanced tasks like speculative pose generation and reasoning-based pose estimation.
📊 Results:
While the accuracy on traditional pose estimation tasks is not yet on par with specialized methods, PoseGPT demonstrates its potential as a first proof of concept.