Doctoral Researcher @UKPLab, @CS_TUDarmstadt | Working on improving the social acceptance of dialogue systems | Supervised by @NafiseSadat and @IGurevych
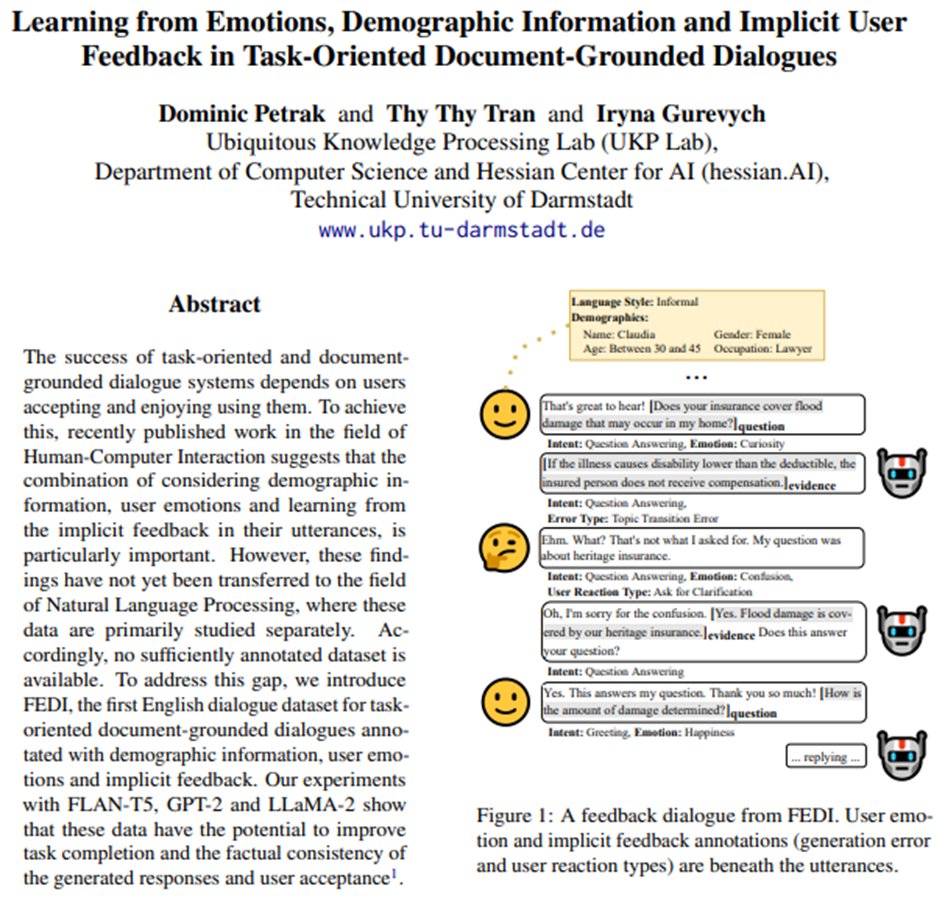
Do you want to know what really improves task completion and factual consistency in task-oriented document-grounded dialogues?😏Then you might want to check out our latest preprint on arxiv! 🤓👉📰 https://t.co/sbIAv7Z88l
(1/🧵)
𝗠𝗲𝗲𝘁 𝗙𝗘𝗗𝗜 💬🤖
Want to know what really improves task completion and factual consistency in task-oriented document-grounded dialogues? 😉
Then check out our #EMNLP2024 paper! 🤓
👉📰 https://t.co/i3Loc16lpb (1/🧵)
Please drop by our poster tomorrow and talk to my co-authors about how IVON can directly optimize a variational objective with similar performance and cost as Adam but many things on top (uncertainty, model adaptation, diagnosis, ...)
Thu. 13:30-15:00, hall c 4-9, poster #1402
Do you want to know what really improves task completion and factual consistency in task-oriented document-grounded dialogues?😏Then you might want to check out our latest preprint on arxiv! 🤓👉📰 https://t.co/sbIAv7Z88l
(1/🧵)
FEDI consists of 8.8k dialogues generated and annotated using GPT-3.5-Turbo, 6k of which with annotations for implicit user feedback. For testing, we additionally provide a set of dialogues collected by humans.
(8/ 🧵)
Fully funded PhD position @shefcompsci, @SheffieldNLP & Healthy Lifespan Institute
Join us in developing cutting-edge NLP techniques for inclusive & evidence-based recommendations to enhance dietary guidelines for older adults
Deadline: February 01
https://t.co/8QYkEsaQUq
Finally... 😊 Check out our EMNLP 2023 paper on learning from free-text human feedback now on arxiv (https://t.co/ETHtHqYEK6)!
We investigate the feasibility of augmenting existing dialogue datasets with the needed annotations and propose two new taxonomies for this purpose.
Human feedback on poor dialog system performance is important for the development of #ConvAI. 👍👎
But datasets with free-text human feedback are scarce. Can data augmentation come to the rescue?
A 🧵 on one of our #EMNLP2023 papers (1/11).
📰 https://t.co/E3YEmk7gh7 #NLProc
📢 We're happy to announce that our group has 12 papers accepted to #EMNLP2023 (6 main, 6 findings) 🧵⬇️
Congratulations to all our members and collaborators! 🥳 #NLProc
Two UKP papers have been accepted to *SEM 2023 (@_starsem) in July in Toronto. The preprint »Arithmetic-Based Pretraining« by @PetrakDominic, @NafiseSadat and @IGurevych has just been finalized – you can find the new, updated version here: https://t.co/0DBlVQD3it
TL;DR: We propose a new, extended pretraining approach that uses contrastive learning and character-level representation to improve the capacity of pretrained language models to work with numbers. 🤓Check it out! It's simple and efficient. Code will be published asap!
Interested in improving the numeracy of your pretrained Transformer-based model without retraining or architectural changes? Then check out the updated preprint of our paper "Arithmetic-Based Pretraining" (https://t.co/uCxrEAUWE2), which will also be presented at @_starsem! 🥳