We also tested a separate route: reinforcement learning from verifier feedback, starting from the base Qwen3.5-4B model rather than the PhAI-IDE SFT checkpoints.
On held-out tasks within the training environments, mean verifier reward rose from 0.357 to 0.857 on LAPS and from 0.286 to 0.571 on MITgcm-biogeo. These results show that the environments can support learning through interaction—not only evaluation or trajectory-based fine-tuning. Transfer to entirely new scientific codebases remains an open question.
For PhAI Labs, the longer-term goal is discovery intelligence that can learn from research actions and evidence, not only from finished papers or predefined answers. ScienceIDE provides one piece of that foundation: a place to act, test, and learn. If you maintain scientific software or can help define what a scientifically correct result looks like, we’d welcome your contribution.
Today we’re releasing ScienceIDE, a research infrastructure project led by the nonprofit @aitonomyfound . PhAI Labs and Qwen are sponsors; @muchencq (Muchen AI) participates in joint R&D and provides technical support.
Scientific software contains decades of research knowledge. But a repository alone is not a training ground: an AI agent needs to run the software, attempt a meaningful scientific task, and receive feedback on whether the result is actually valid. ScienceIDE turns scientific codebases into executable environments with verifiable feedback.
Alongside the environments, we’re releasing PhAI-IDE-4B, 9B, and 72B—models trained on verified scientific interaction trajectories.
📄 Tech report: https://t.co/hdNoiKZnEQ
🌐 Project: https://t.co/HW5yv0m7Tv
💻 GitHub: https://t.co/umz9gVCYAf
🤗 Models: https://t.co/XY5yU0eLLg
#PhAILabs #DFM #ScienceIDE
ScienceIDE is not only a benchmark. We used verified scientific trajectories for supervised fine-tuning and trained the PhAI-IDE 4B, 9B, and 72B model family.
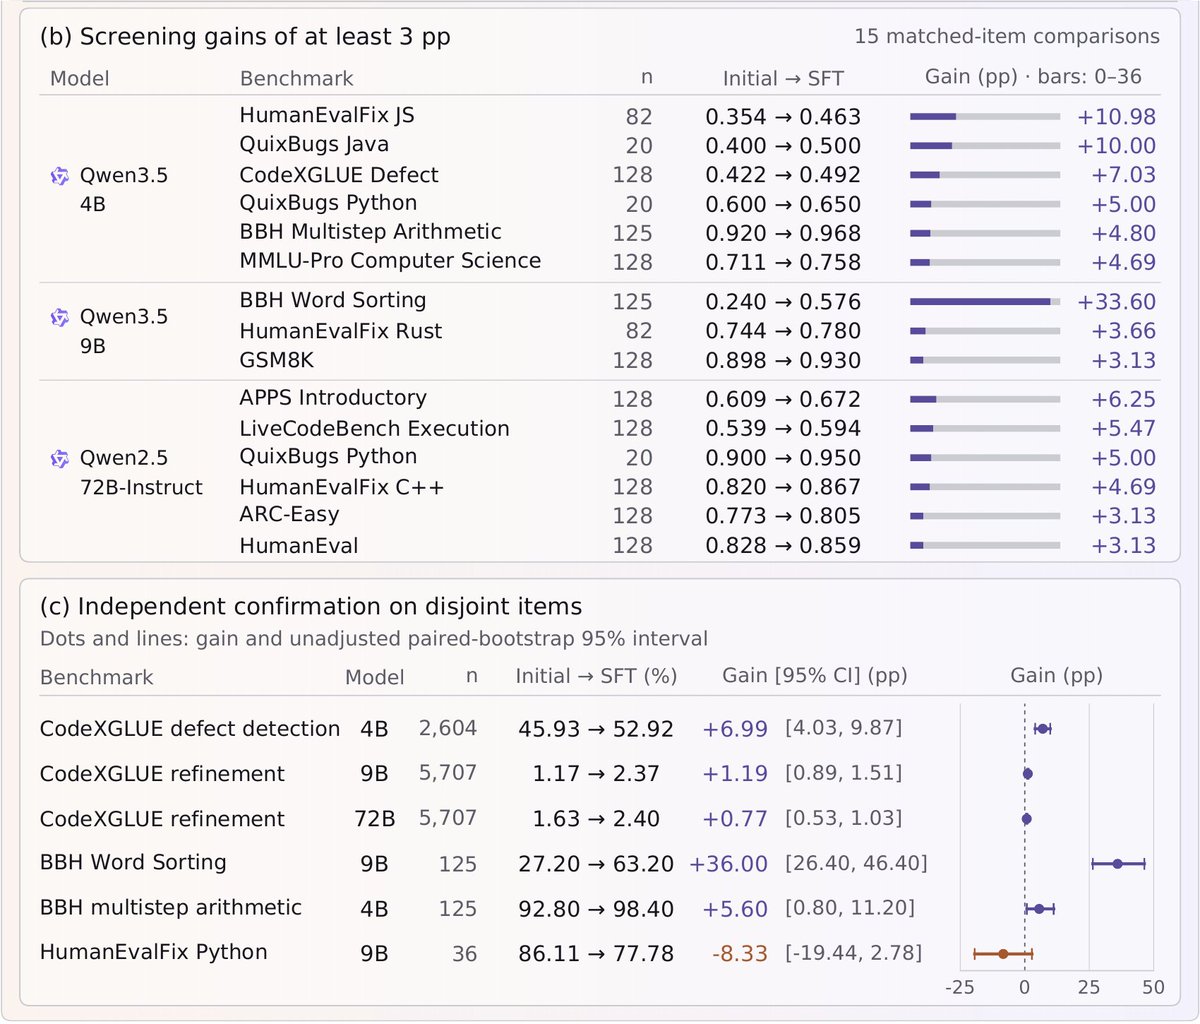
On held-out scientific-code repair tasks, the 4B model’s mean verifier reward on PLUTO-Particles-Dust rose from 0 to 0.333. The paper also examines whether this experience transfers beyond the scientific environments used for training. In independent confirmation tests, the 4B model improved on CodeXGLUE defect detection from 45.93% to 52.92%; the 9B model improved on BBH Word Sorting from 27.20% to 63.20%.
That is an encouraging result: scientific interaction data can help selected code and reasoning tasks too. It is not a claim that every benchmark improves—gains vary by task, and the paper reports a decline in one confirmation comparison.
Today, PhAI Labs launches ScienceBuddy, an interactive research workspace for scientific agents that improve through researcher collaboration.
Initiated by PhAI Labs, with @muchencq (Muchen AI) as a joint R&D and technical support partner. 🧵
ScienceBuddy couples two loops:
🔹 An inner loop that refines the agent harness—its instructions and skills.
🔹 An outer loop that trains the model through rubric-guided reinforcement learning.
Together, they form Recursive-in-Recursive Self-Improvement.
On a held-out set of 180 scientific problems, pass@4 coverage with Qwen3.5-4B rose from 48.3% to 67.8% under the same four-attempt budget.
DFM sets the direction—from predefined tasks toward open-ended discovery. ScienceBuddy explores how scientific agents can improve through sustained collaboration with researchers.
📄 Tech report: https://t.co/gxPRnp5aZJ
💻 GitHub: https://t.co/xNlsshOyXs
🔬 Product access: https://t.co/ksVs3zUXd9
#PhAILabs #DFM #ScienceBuddy
GALILEO examines selected DFM mechanisms in therapeutic-peptide discovery, with a real wet-lab feedback loop.
Candidate designs move through synthesis, quality control, imaging, and phenotypic analysis. The results inform subsequent designs and mechanism hypotheses.
Across five rounds, wet-lab feedback informed reusable design rules about amphiphilic balance—an example of experimental experience becoming knowledge that can guide later designs.
This is evidence from one domain, not proof of general scientific discovery. Broader capability still needs testing across more problems and experimental settings.
We're also opening a Scientist Collaboration Program—details in a separate post.
Scientific discovery often requires changing the question itself.
Today, PhAI Labs releases the technical report for Discovery Foundation Models (DFM), a research direction for AI systems that can identify valuable unknowns, formulate questions, develop hypotheses, design experiments, and revise their understanding as evidence comes in.
The goal is not just to complete one investigation. What a system learns should carry into the next—as reusable methods, accumulated research experience, and better decisions about what to explore.
The report introduces a reference architecture, the science infrastructure we're developing, and a wet-lab case study.
🔬 Alongside the report, we're opening the DFM Scientist Collaboration Program.
Have a scientific question you'd like to explore with AI? We're inviting scientists, research teams, and experimental platforms to collaborate on meaningful open problems with real opportunities for validation.
🙌 Program details & application:
https://t.co/w4S6OlvKAS
📅 Over the next three days, we'll introduce three related research efforts:
Sep 16 — ScienceBuddy · AI research companion
Sep 17 — ScienceIDE · Scientific integrated development platform
Sep 18 — JEPA-Anything · Cross-domain scientific world models
A research direction we're pursuing with @Charles_Y_Wu@LingYang_PU@zhenfei_yin_yzf
📑 DFM technical report:
https://t.co/nRwgHLSkWv
🔗 DFM research roadmap:
https://t.co/fqYzVlXZYP
🏠 More about PhAI Labs:
https://t.co/ZoGBNWHjki
#PhAILabs #DFM
How could a model revise the research process—not just its answer?
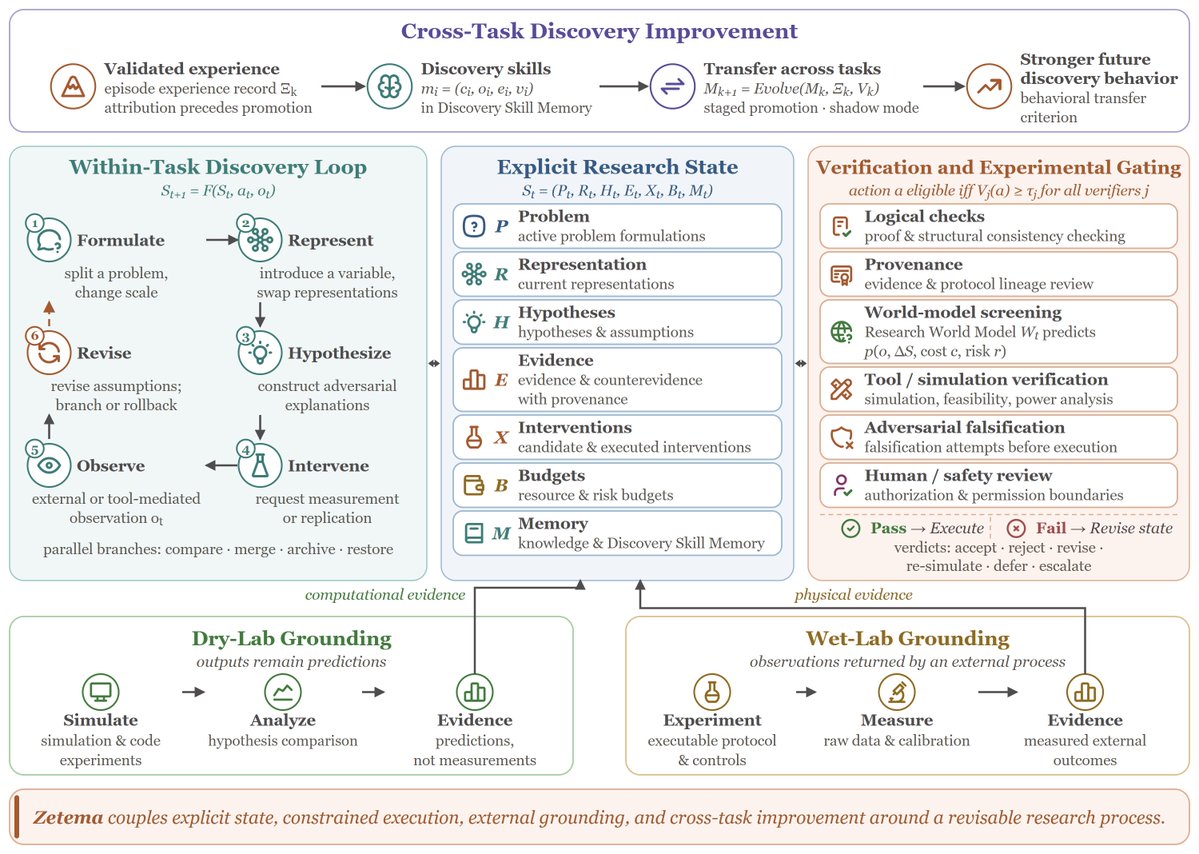
Zetema is the report's reference architecture. It makes questions, representations, hypotheses, evidence, planned actions, and resource constraints explicit in a revisable research state.
When evidence conflicts with expectations, the system should be able to reconsider the hypothesis, the representation, or the question itself. It can track competing explanations and select experiments that help distinguish them.
This creates a recursive discovery loop: identify unknowns, frame researchable problems, test explanations against external evidence, update understanding, and begin again.
Zetema is a reference architecture, not a finished implementation.