my master’s student: “i want to apply for a PhD”
me: great! what motivates you?
student: “i went to a conference this weekend and saw a bunch of PhDs doing shitty work. figured i could do better. gained confidence.”
me: …you were exactly like me three years ago, except now i’m one of the shitty PhDs.
They now predict that 95% of Anthropic's R&D will be fully automated by November 2027. This is what Anthropic describes as AL5, fully autonomous RSI. This would have many implications for policy, as this will eventually happen at every lab, not just Anthropic
@paulnovosad its like driving a stick shift and declaring your locomotion as null because you just steered the car, the engine powered it. I fail to understand. And nothing against Pangram. It is a noble idea but if AI is enabling a person to communiate what they feel so much easily then why?
@paulnovosad Words are used to express what people feel. The author has tried to convey their take on the CJP revolt. Any lay guy would understand it. Rather than engaging with the idea posting a percentage shifts the burden of proof and brands one as a fraud @lianda_edu
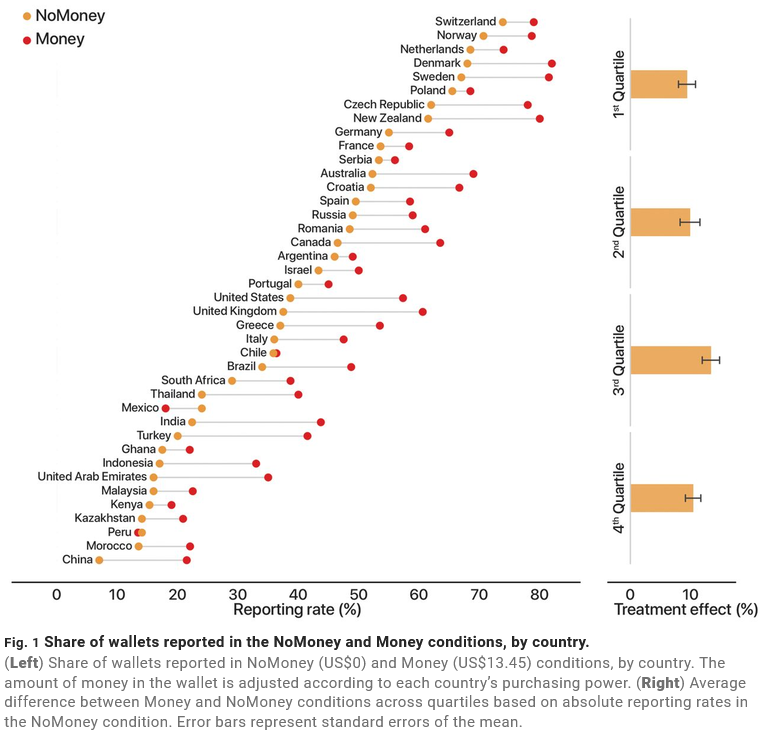
@_akpiper It refers to people reducing effort when their effort is unobservable.
Renters abusing a rental car, CEOs taking on too much risk, referees phoning it in with AI.
AI is a super-powered shirking technology, it's inevitable that a lot of people are gonna use it to shirk.
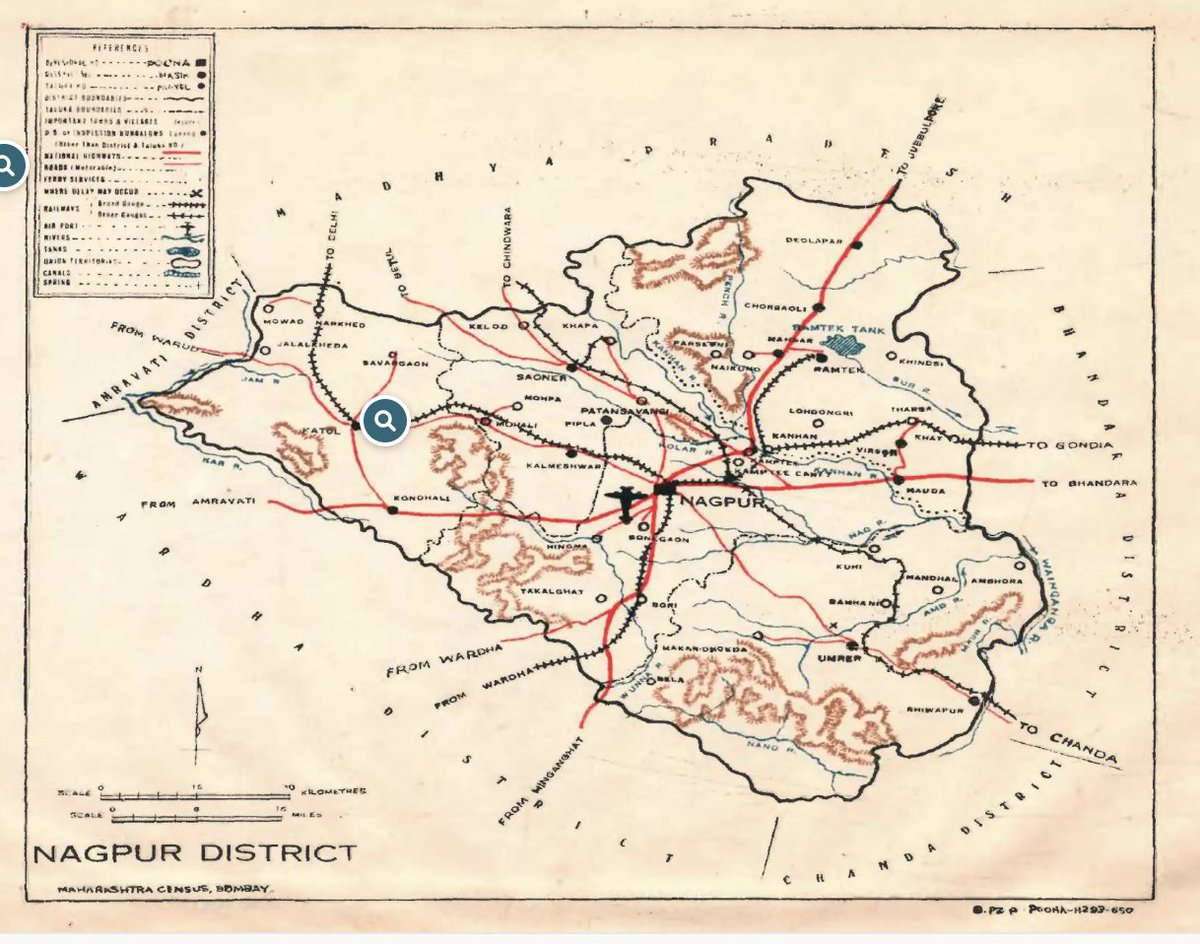
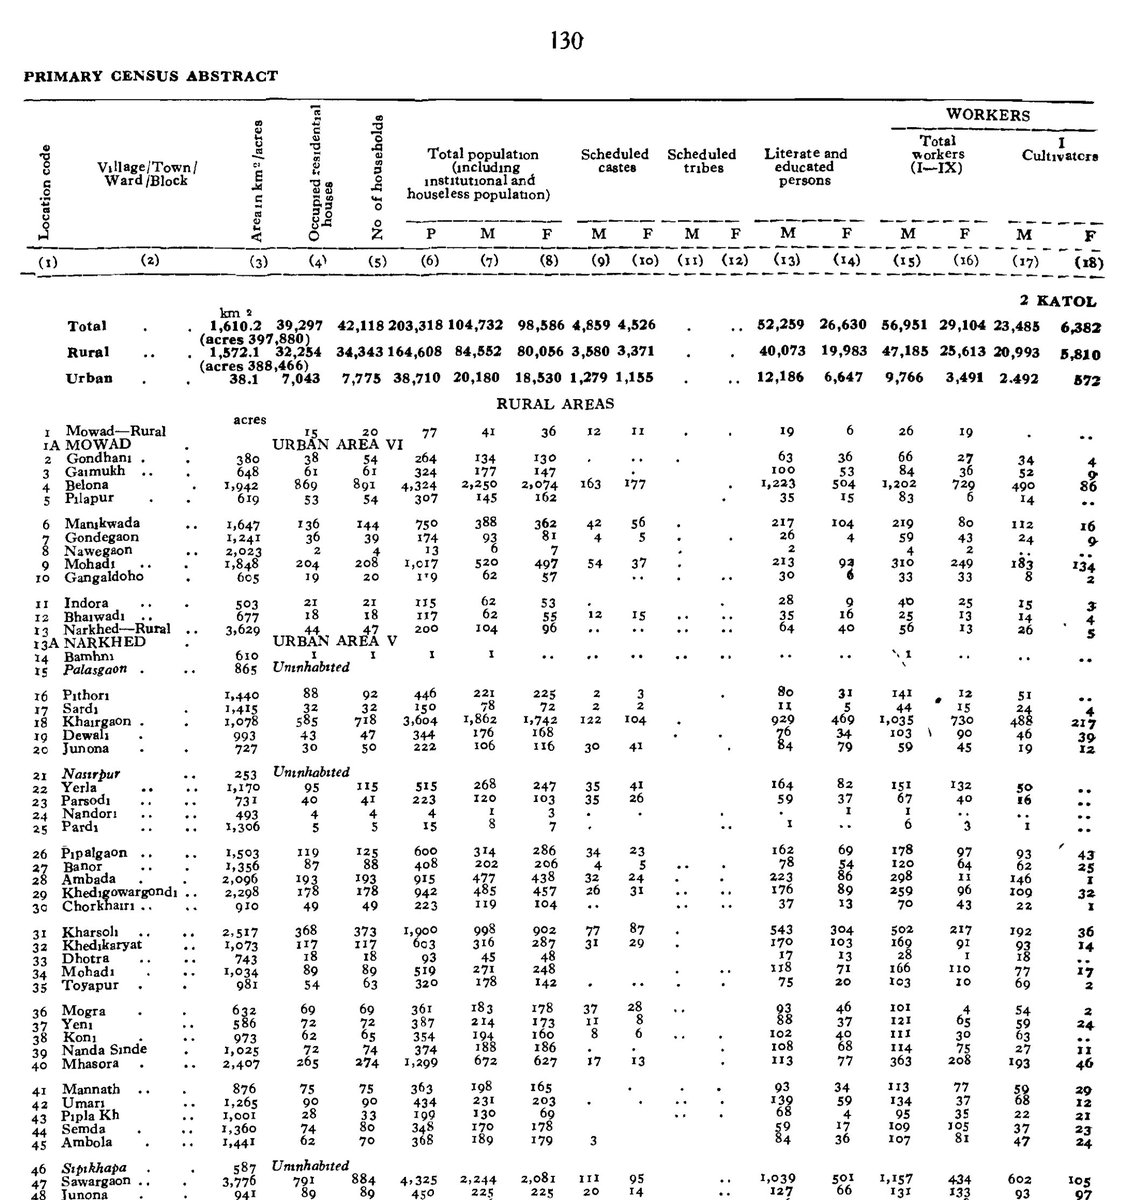
New DDL project -> Help us crowdsource India's economic history!
We're making a complete collection of India's district handbooks c.1951–2011, digitizing ALL the tables, harmonizing districts, variables, villages over time.
You can help! 🧵👇
https://t.co/5xuLWMtc5s
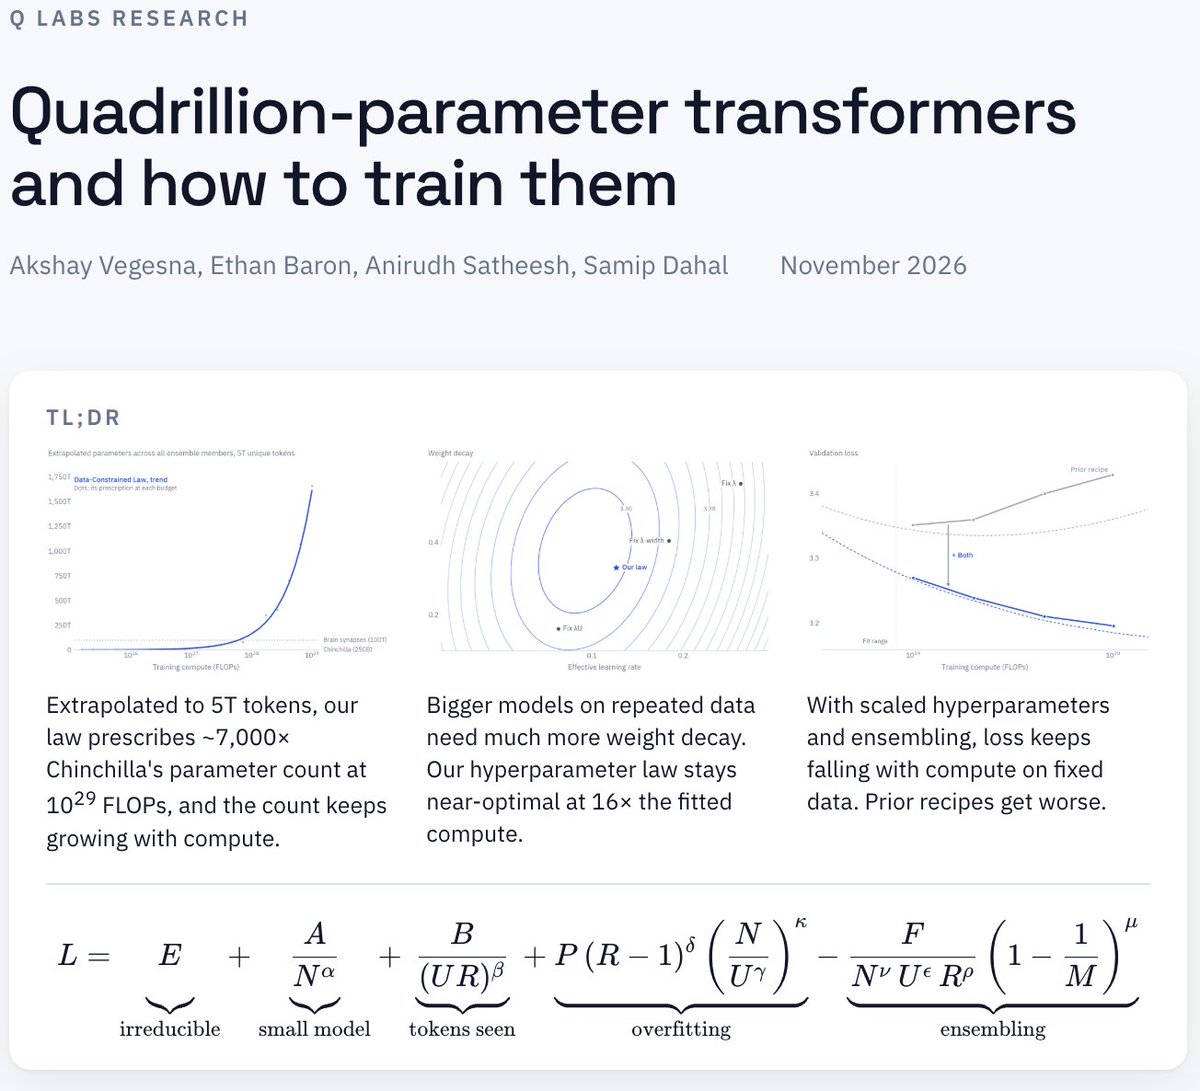
Humans are ~1,000,000x more sample efficient than LLMs, and there are no good explanations.
We’ve found that a big part of the answer is that LLMs are *massively* underparameterized by many orders of magnitude. The brain has 100T synapses learning from ~200M tokens of language. Chinchilla prescribes a 1T-parameter model on 20T tokens. That’s 7 OOMs apart in parameters per token.
After a lot of painstaking work, we present new data-constrained scaling laws and learning algorithms to scale to (extrapolated) quadrillion-parameter transformers.
w/ @akshayvegesna, @EthanBaron78553, @asatheesh6561
Full paper led by @EthanBaron78553, with @ShmuelBerman, @andrewgwils
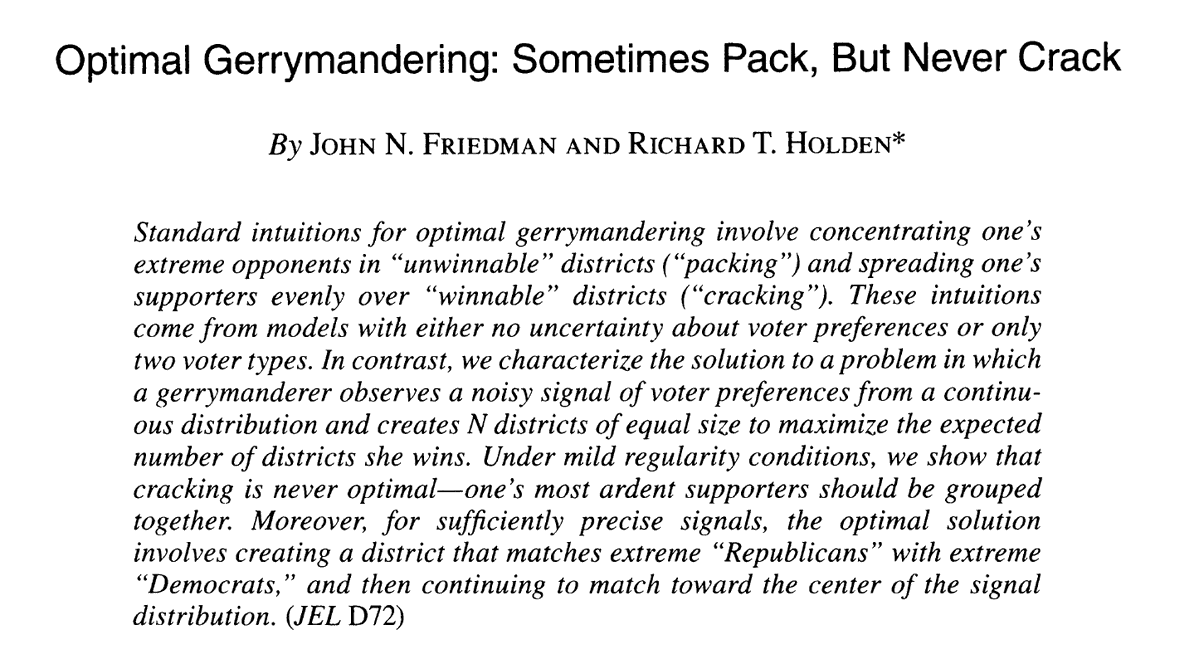
@lm_guirola@RenaudFoucart@diomavro@RenaudFoucart Mr. Foucart would you be interested in doing something similar in India. I am very much interested in making a model of sorts to predict the upcoming 2027 Uttar Pradesh's state election results. It is one of the biggest state in the country
@RenaudFoucart@diomavro@lm_guirola intersting but how does one even arrive at such conclusions?? are you taking help from the polls?? would love to know more about your fiscal and forex projections as well
(wild) predictions after today's MIT Weight-Space Programming work:
1. Model weights become a programming language that AI can understand, but humans can't.
2. Training and inference will merge. Like human brain, AI could continuously rewrite its own weights while thinking.
3. A new path to RSI: AIs will directly edit each other's weights, evolving together without backprop.