OPPO × Phala published a joint paper on Kubernetes Pod-level remote attestation for confidential AI.
Goal: prove the hardware, container image, and Pod identity before sensitive data enters the workload.
https://t.co/jQjC6DFsS0
Voxtral Small 24B is live on Phala—served inside a TDX-attested GPU TEE.
Private, verifiable inference for audio transcription.
https://t.co/mZNmlfzQMf
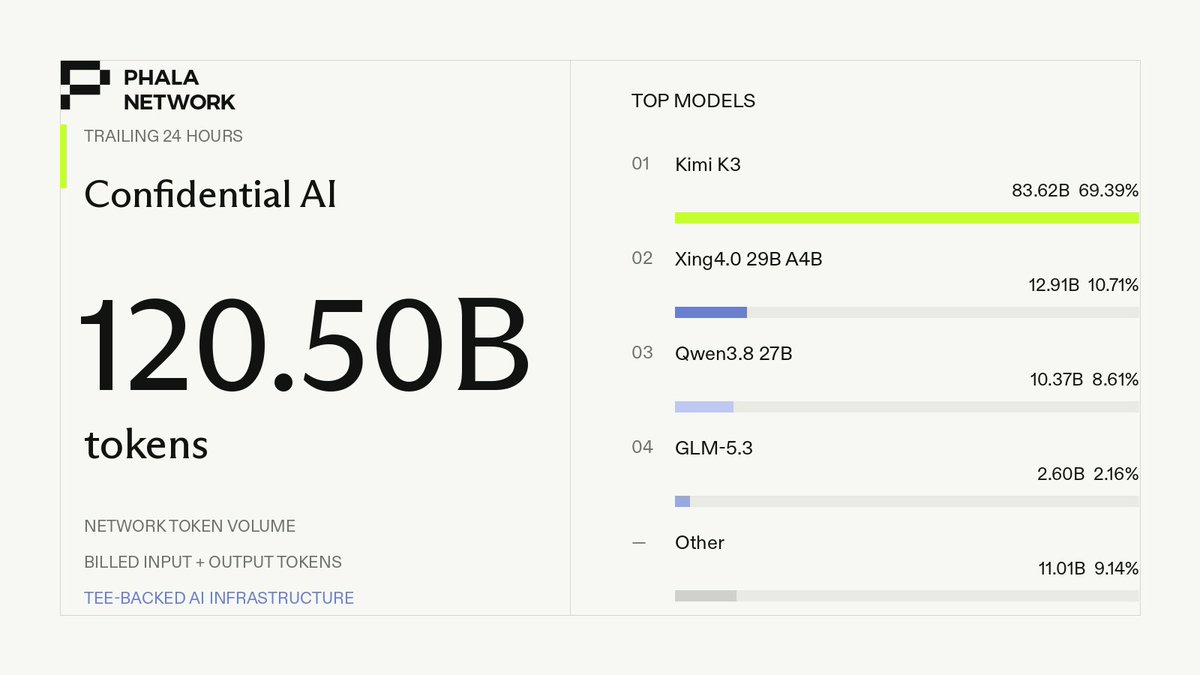
Phala Confidential AI: 120.50 billion tokens over the past 24 hours.
Top models:
Kimi K3 69.39%
Xing4.0 29B A4B 10.71%
Qwen3.8 27B 8.61%
https://t.co/eHSPzOFiwk
TEE-backed AI infrastructure.
Congrats on the launch, @proofableme! 👏 Agents need verifiable identity, ownership, and authority as they act across apps. Proud to be part of what you’re building.
Billions of agents are coming online.
Nobody can tell what's real.
Introducing Proofable.
It lets people and AI agents carry identity, ownership, and authority anywhere.
Proof is the missing layer.
Make it Proofable.
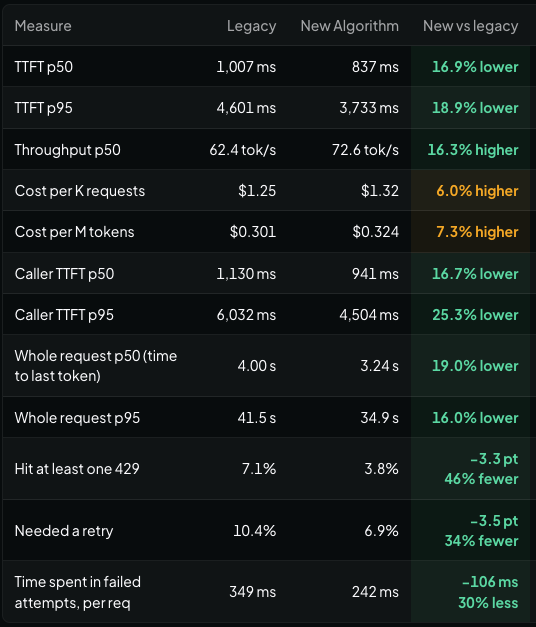
As inference providers multiply, price matters. Model service quality still comes first.
OpenRouter is raising the bar by rewarding inference that is fast, reliable, and cost-efficient. Salute 🫡
We just shipped our biggest improvement to our provider router since the founding of OpenRouter.
Before, we prioritized mostly based on price. The new router now rewards the best quality inference for the actual cost of a request, so requests stay cheap but are also fast and reliable.
Providers that deliver more value automatically win more traffic, so every provider has a reason to keep improving. And every time a provider gets better, so does your inference on OpenRouter.
Private AI should be as easy to use as any other API. Together with @foundry_fi, we're bringing Phala's confidential GPU compute to builders and agents through an OpenAI-compatible API, with payments in USDF.
Phala Confidential AI: 186.42 billion tokens over the past 24 hours.
Top models:
GLM-5.3 Flash 69.41%
deepseek-v4.1-flash-1017 7.61%
xing4.0-29b-a4b 5.50%
https://t.co/e1fj3fVSlJ
TEE-backed AI infrastructure.
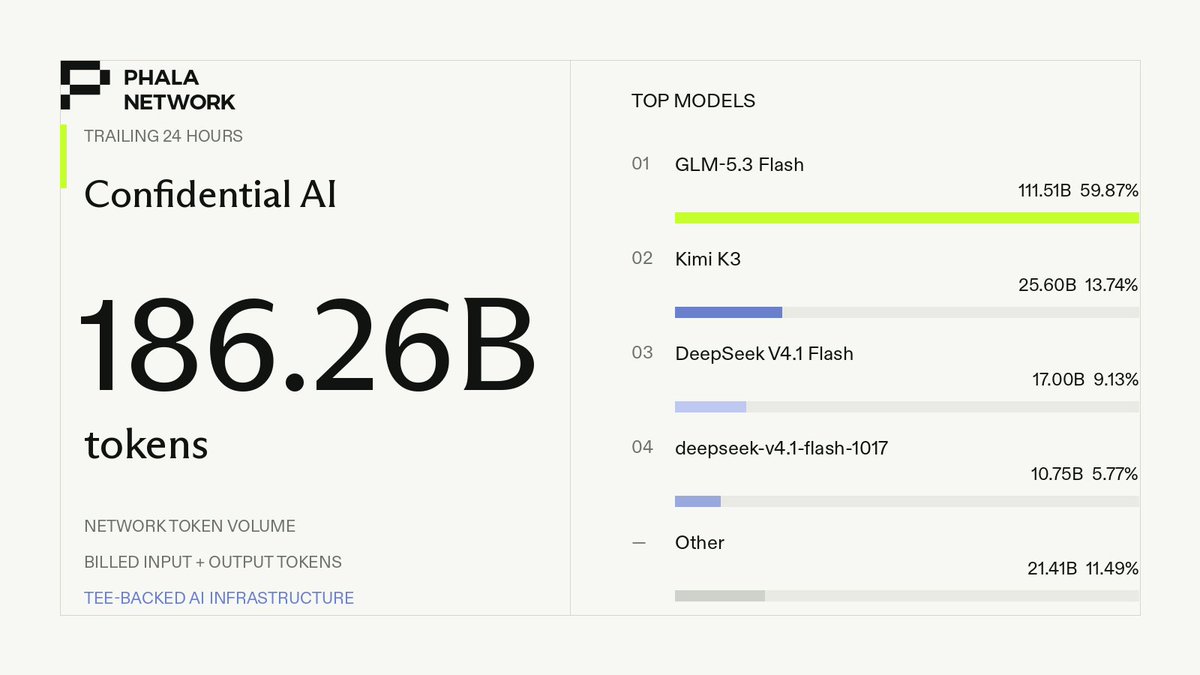
Phala Confidential AI: 186.26 billion tokens over the past 24 hours.
Top models:
GLM-5.3 Flash 59.87%
Kimi K3 13.74%
DeepSeek V4.1 Flash 9.13%
https://t.co/e1fj3fVSlJ
TEE-backed AI infrastructure.
DeepSeek V4.1 Flash 1017 is live on Phala—served inside a TDX-attested GPU TEE.
Private, verifiable inference for long-horizon agents, visual understanding, reasoning.
https://t.co/w66K7vwq0h
Phala Confidential AI: 81.33 billion tokens over the past 24 hours.
Top models:
DeepSeek V4.1 Flash 56.30%
xing4.0-29b-a4b 12.22%
qwen3.8-27b 9.39%
https://t.co/sV8F6voMwO
TEE-backed AI infrastructure.
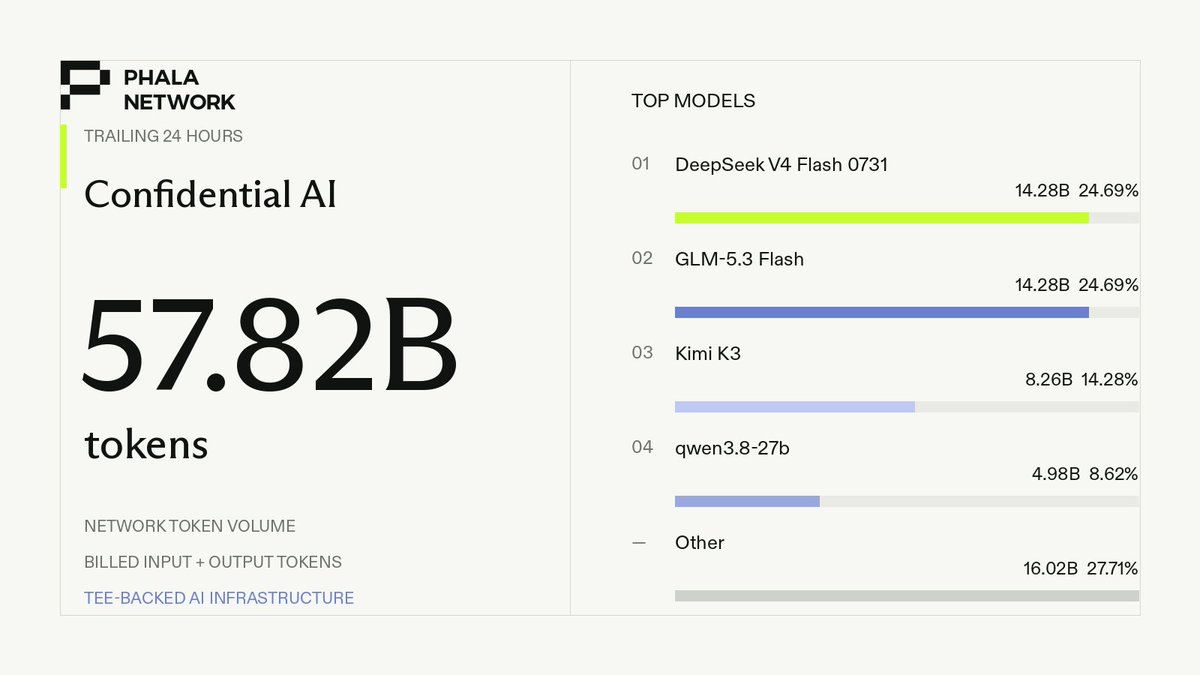
Phala Confidential AI: 57.82 billion tokens over the past 24 hours.
Top models:
DeepSeek V4 Flash 0731 24.69%
GLM-5.3 Flash 24.69%
Kimi K3 14.28%
https://t.co/4lpNF8JGLs
TEE-backed AI infrastructure.
Private AI begins on-device.
Case study: how @solrouterai keeps its backend outside the plaintext path and opens encrypted prompts inside an attested Intel TDX enclave on Phala.
https://t.co/FX9YFk8p0p
From Claude Code, Cursor, Claude Desktop, or the SDK, sealed requests flow to an Intel TDX enclave on Phala.
The enclave holds the decryption key and protected orchestration. Qwen3.5 122B extends the boundary into an NVIDIA Confidential Computing H200.
Agent decisions often touch customer messages, policy documents, and approval state.
Kev-4B is now live in beta on Phala with NVIDIA Confidential Computing.
https://t.co/y1pectnXKv