Everyone celebrating "Claude ported itself to AMD MI355X in 3 days—the Nvidia CUDA moat is dead" missed two huge footnotes in @AnthropicAI's own documentation this week:
1. The GPU Kernel Cap Paradox
In the Fable 5.2 & Mythos 5.2 release notes, Anthropic explicitly states they intervened during training to cap "accelerator kernel optimization" so it performs no better than Opus 5.5.
Why did the AMD port work? Because the roadshow slide footnote cites "Claude Mythos Preview"—NOT the newly capped 5.2 release. Anthropic used an uncapped internal preview model to pitch automated GPU bring-up to IPO investors during the exact same week they nerfed GPU kernel optimization in the weights shipped to developers.
2. Prefill ≠ Full Inference Bring-Up
Look closely at the slide footnote:
"Bring up prompt processing for one Anthropic model on AMD MI355X GPUs at a useful level of performance."
"Prompt processing" is PREFILL ONLY—compute-bound matrix multiplication (GEMMs) where AMD ROCm/hipBLASlt is already strong.
It says nothing about DECODE, which is memory-bandwidth bound and requires custom paged-attention, KV-cache kernels, and collective communication tuning to beat H100/B200 TCO in production.
Agent-written kernels are a massive milestone, but prefill bring-up on an uncapped internal model isn't the death of CUDA yet.
Appreciate the quote on this Robin! The crazy follow-up is what happens on Dec 1 when Gemini 4 Carbon's intro API pricing jumps 2x ($2/$10 -> $4/$20) while Google still locks paying AI Pro users out of the app tier.
Are you testing Carbon via API in your workflow right now, or sticking with Opus 5.5 / Fable 5.2?
$0.10/1M input with $0 output tokens and 150–250ms single-pass scoring across up to 1,000 closed-set choices turns agent routing and guardrails from a generative bottleneck into a deterministic primitive.
Two technical questions on the implementation:
1. When scoring 1,000 questions against a single multimodal input in one pass, are input tokens billed strictly once for the shared context?
2. Does confidence calibration hold up if you shuffle the option order (like Artificial Analysis's AA-Symmetry test)? If log-probs stay invariant under choice permutation, this replaces 90% of LLM-as-a-judge calls overnight.
Primary sources (Verified):
1. Anthropic Fable 5.2 & Mythos 5.2 launch post (disclosing training-time cap on accelerator kernel optimization at Opus 5.5 level):
https://t.co/84R3UxPapR
2. Anthropic IPO Roadshow transcript & slide footnote ("prompt processing for one Anthropic model on AMD MI355X" via Claude Mythos Preview):
https://t.co/udaU4f8Snp
Everyone celebrating "Claude ported itself to AMD MI355X in 3 days—the Nvidia CUDA moat is dead" missed two huge footnotes in @AnthropicAI's own documentation this week:
1. The GPU Kernel Cap Paradox
In the Fable 5.2 & Mythos 5.2 release notes, Anthropic explicitly states they intervened during training to cap "accelerator kernel optimization" so it performs no better than Opus 5.5.
Why did the AMD port work? Because the roadshow slide footnote cites "Claude Mythos Preview"—NOT the newly capped 5.2 release. Anthropic used an uncapped internal preview model to pitch automated GPU bring-up to IPO investors during the exact same week they nerfed GPU kernel optimization in the weights shipped to developers.
2. Prefill ≠ Full Inference Bring-Up
Look closely at the slide footnote:
"Bring up prompt processing for one Anthropic model on AMD MI355X GPUs at a useful level of performance."
"Prompt processing" is PREFILL ONLY—compute-bound matrix multiplication (GEMMs) where AMD ROCm/hipBLASlt is already strong.
It says nothing about DECODE, which is memory-bandwidth bound and requires custom paged-attention, KV-cache kernels, and collective communication tuning to beat H100/B200 TCO in production.
Agent-written kernels are a massive milestone, but prefill bring-up on an uncapped internal model isn't the death of CUDA yet.
@OpenAI@AnthropicAI@GoogleDeepMind: AI leadership is also about access.
Anthropic gave Pro users a launch week window for Fable 5.2. Google put Carbon behind Ultra not AI Pro. Paid API access exists; Gemini Pro users remain locked out.
Smart strategy or trust problem? Fuck!
Fuck you, @GoogleDeepMind and @OfficialLoganK.
You have users’ data to train your models, yet give those same users practically no access. What the fuck is this?
Even OpenAI’s free tier offers more usable access. And Google's answer is just “Unavailable”?
Seriously?
Fuck you, @GoogleDeepMind and @OfficialLoganK.
You have users’ data to train your models, yet give those same users practically no access. What the fuck is this?
Even OpenAI’s free tier offers more usable access. And Google's answer is just “Unavailable”?
Seriously?
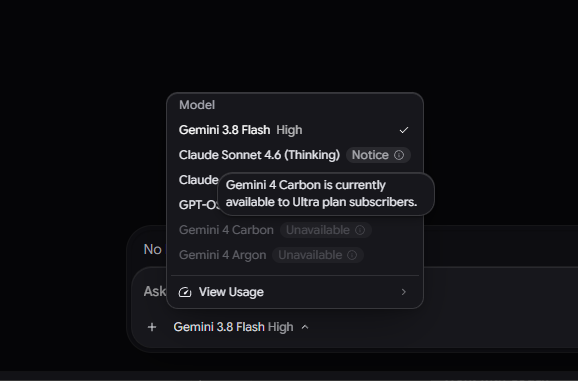
🚨Gemini 4 Carbon is Live! is only available with a Google AI Ultra plan, or pay per request with an API key.
No Carbon for Pro User's @OfficialLoganK@GoogleDeepMind WTF! no Pro user's. I paid you guys.
@CryWoozieMu@GoogleDeepMind@OfficialLoganK Without free users and clients there is no fucking business for Google
Mate I’m not said I want everything free I want what is paid for I have paid for Pro plan cost me rupees nearly 2K/monthly for it and I can’t get the Pro models!? WTF! I fucking paid it.
@CryWoozieMu@GoogleDeepMind@OfficialLoganK Google says India is its largest global user base for voice and visual Search, and leads the world in daily Gemini use for learning. Criticise Google’s decisions—but don’t dismiss the users and talent helping power its ecosystem.
@CryWoozieMu@GoogleDeepMind@OfficialLoganK South Asia is not a footnote—and India alone shows why. Google Research’s India lab works on foundational ML, multilingual NLP, computer vision and healthcare AI for products used worldwide. This is technical contribution, not just consumption.
@alwayspriyesh Alphabet’s 2026 CapEx guide is $195–205B; most Q3 CapEx supports AI. Yet Carbon in Gemini app/Search is Ultra-only, not Pro (API is separate). With Keep Activity on, chats may train models and some are human-reviewed. Pro users deserve capped access and data choice.
@alwayspriyesh Paid API access ≠ consumer access.
Carbon is Ultra-only in Gemini and Search AI Mode; Google hasn’t announced a capped Pro tier or rollout date.
A lower Pro quota would manage compute and reward subscribers. Forcing an upgrade to try the flagship is poor product strategy.
@_mohansolo@GoogleDeepMind@OfficialLoganK I have Two Pro account and i paid for one for ₹1950 for it and now i don't have access for 4 Carbon WTF is this!? this is Fucking Stupidest thing Google ever done Well played!
Qwen4 is coming.
Deeper knowledge. Richer world understanding. Stronger coding and agentic capabilities.
Built for real-world tasks — from complex coding and knowledge work to front-end builds and professional software workflows.
Qwen4-Max is now in preview on Alibaba’s Token Plan. You can also get early access to the new model on QwenWork, Qoder, Qwen APP, and QwenStudio.
Put it to the test on a real problem. Show us what you build. 👀
Token Plan: https://t.co/LOB2Jdt3Sk
🚨Gemini 4 Carbon is Live! is only available with a Google AI Ultra plan, or pay per request with an API key.
No Carbon for Pro User's @OfficialLoganK@GoogleDeepMind WTF! no Pro user's. I paid you guys.