Estimates for Prop 40, the 2026 Billionaire Tax Act, run from ~$100B in revenue (Galle, Gamage, Saez & Shanske) to a −$39B mean net present value (Jaros & Rauh). Our open calculator splits the gap by assumption.
Webinar Fri Oct 30, noon PT: https://t.co/VnxoSd79PG
Five years ago today PolicyEngine launched in the UK to democratize evidence-based policy. PolicyEngine US followed in 2022. Anyone can change a federal or state tax or benefit rule and see what it means for their household and the country.
Thanks to all who build and use it.
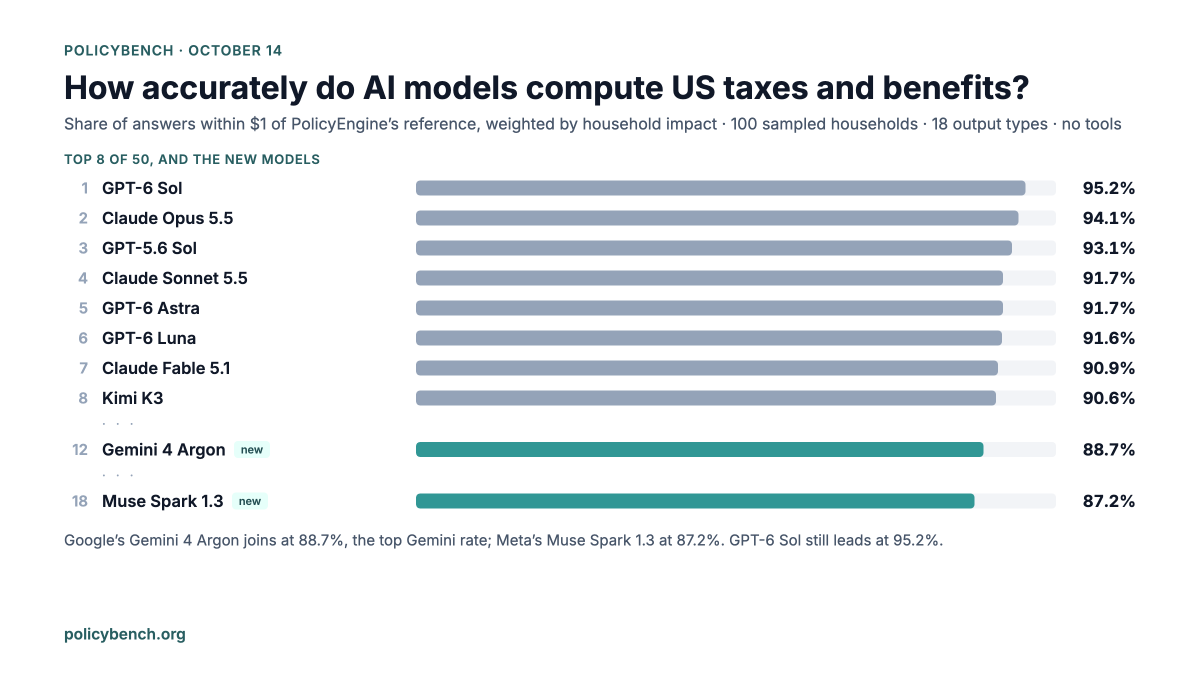
Gemini 4 Argon answers through a forced tool call, which switches off reasoning in some models. So we fixed a test in advance and ran every household both ways. It reasoned about as often either way, so the forced row stands. Muse Spark 1.3 trails Muse Wonder on exact answers but ranks 6th when near misses get partial credit.
What changed: https://t.co/1DLEXnoRr9 The board, per-program results and every answer: https://t.co/uK5yxlbPnk
Google's Gemini 4 Argon is on PolicyBench: 88.7% of tax and benefit answers within $1, with no tools, the highest within-$1 rate of any Gemini model on the board. Meta's Muse Spark 1.3 joins too, at 87.2%. GPT-6 Sol still leads all 50 at 95.2%.
Meta also released Muse Wonder Full, but only inside Muse Code, with no API, so it can’t run under the board’s protocol. This release also moves our reference calculations to policyengine-us 2.41.0, which fixes the engine defects behind 9 outputs we had stopped scoring. Few models get those right, so every earlier model’s score fell, by 0.18 to 0.42 points.
What changed and why: https://t.co/edvB1Jgpzt
The board, per-program results and every answer: https://t.co/uK5yxlcncS
Meta’s Muse Wonder is on PolicyBench, the first Meta model on the board: 90.1% of tax and benefit answers within $1, with no tools. Give near misses partial credit and only GPT-6 Sol and Claude Opus 5.5 do better. GPT-6 Sol still leads all 48 at 95.2%.
Claude Haiku 5.5 is on PolicyBench: 79.6% of tax and benefit answers within $1, with no tools, 4.8 points above Claude Haiku 4.5.
The board forces an answer tool call, which turns Haiku’s thinking off. With the call left to the model, it scores 89.2%, which would rank #10. GPT-6 Sol still leads all 47 at 95.6%.
This release also moves our reference calculations to a policyengine-us version that fixes the engine defects behind 14 outputs we had stopped scoring. Few models get those right, so every earlier model’s score fell, by 0.24 to 1.37 points.What moved and why, output by output: https://t.co/GCZz3nbtxd
GPT-6.1 Sol trails GPT-6 Sol by 4.4 points, but it gets two SNAP households right that GPT-6 Sol misses. The board, per-program results and every answer: https://t.co/lAkEGED217
Four new models on PolicyBench. Claude Sonnet 5.5 lands level with GPT-6 Luna: both get 92.1% of tax and benefit answers within $1, with no tools. GPT-6.1 Sol gets 90.6%, Grok 4.7 88.3% and DeepSeek V4.1 Flash 87.1%. GPT-6 Sol still leads all 46 at 95.0%.
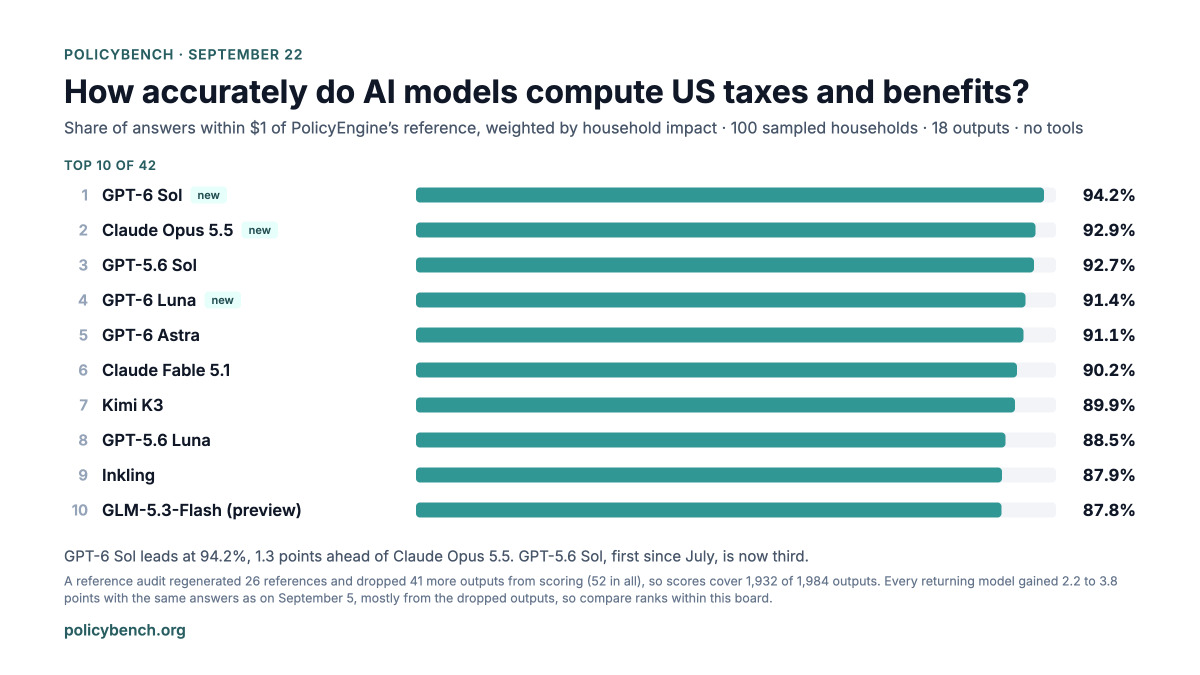
PolicyBench has a new #1: GPT-6 Sol gets 94.2% of tax and benefit answers within $1 with no tools, ending GPT-5.6 Sol's run at the top since July. Among other models release yesterday, Claude Opus 5.5 enters second at 92.9%, GPT-6 Luna fourth at 91.4%.
https://t.co/ojuURzdOhX
See it live in less than 90 minutes with guest speakers @BlahaOsborne
(Prenatal-to-3 Policy Impact Center) and @JoshuaTMcCabe (Niskanen
Center).
Register: https://t.co/KeN6ECQMDk
This morning, the Census announced that the SPM child poverty rate was 13.4% in 2025, down 0.1 pp from 2024.
Today we're launching the Child Poverty Impact Dashboard: a tool to analyze how reforms can affect this rate across all 50 states and DC.
https://t.co/sxDUWmo1dO
Configure a reform: a state Child Tax Credit, EITC, dependent
exemption, child allowance, and more to see its impact on child poverty, individual households, income distribution, and congressional districts.
Census releases the 2025 poverty numbers today at 10am ET. At 2pm ET we go through them live with guests @BlahaOsborne and @JoshuaTMcCabe and demo the tools: "The new child poverty numbers, and how state reforms would affect them." Register: https://t.co/Czh9ZDdScE
BLS re-estimates SPM poverty thresholds every year from consumer spending, not inflation. Renter threshold for two adults and two children: +6.3% from 2024 to 2025, more than twice CPI. PolicyEngine now builds and projects those thresholds the way BLS does, from the Consumer Expenditure microdata with BLS's procedure. A calculator and a paper: