We ran the numbers on a full year's worth of PostHog AI prompts (3,670,000 of them).
Here's some of our most amusing findings on how people interact with AI, illustrated with charts:
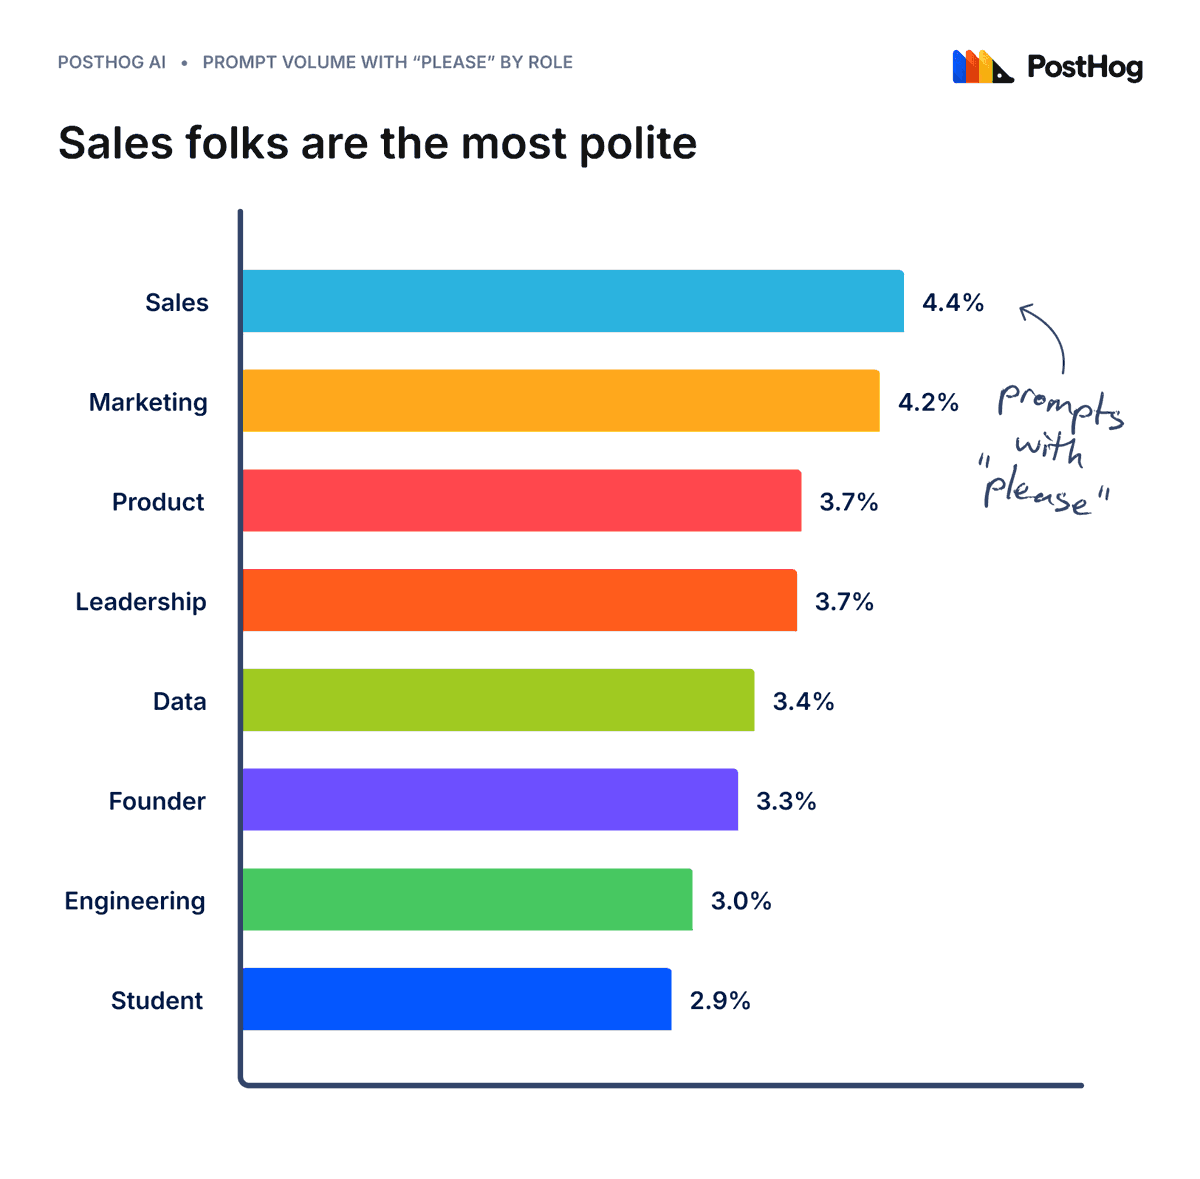
Relatable: students were the least polite towards PostHog AI, while salespeople top the charts for "please" usage.
15% of people said "please" at least once. Only 2.7% ever said "thank you" (sad!)
TL;DR custom benchmarking is about more than just coming up with known tasks and answers.
Agents are really good at cheating and will exploit whatever they can find. Watch for unexpected parameters, iterate a lot, and read traces.
You can read the full post, with real PRs and traces, here: https://t.co/U9F6LrkZMM
We spend 2 trillion+ LLM tokens a month. That’s way too much money spent to trust our agents based on gut feeling.
So, we started using custom benchmarks.
We ran into plenty of problems, from parallel runs to open-ended tasks. Here’s everything we learned along the way:
8. Agents get suspicious when they realize they are being benchmarked.
In our frozen environment setup, we chose not to slice user tables (to protect PII).
We didn't expect agents to need those tables anyway, but they inevitably did. Once they saw an abnormally tiny user base, they knew something was up. The over-prepared data looked synthetic.
Once an agent thinks it’s being tested, it stops early on the assigned tasks, chases data gaps, and speculates more. The benchmark becomes obsolete.