Try it live: https://t.co/cFOjlIc7ML
Code: https://t.co/UDzHz4NmXa
Would love feedback from anyone working in RAG/LLM systems.
#AIEngineering#RAG#BuildInPublic
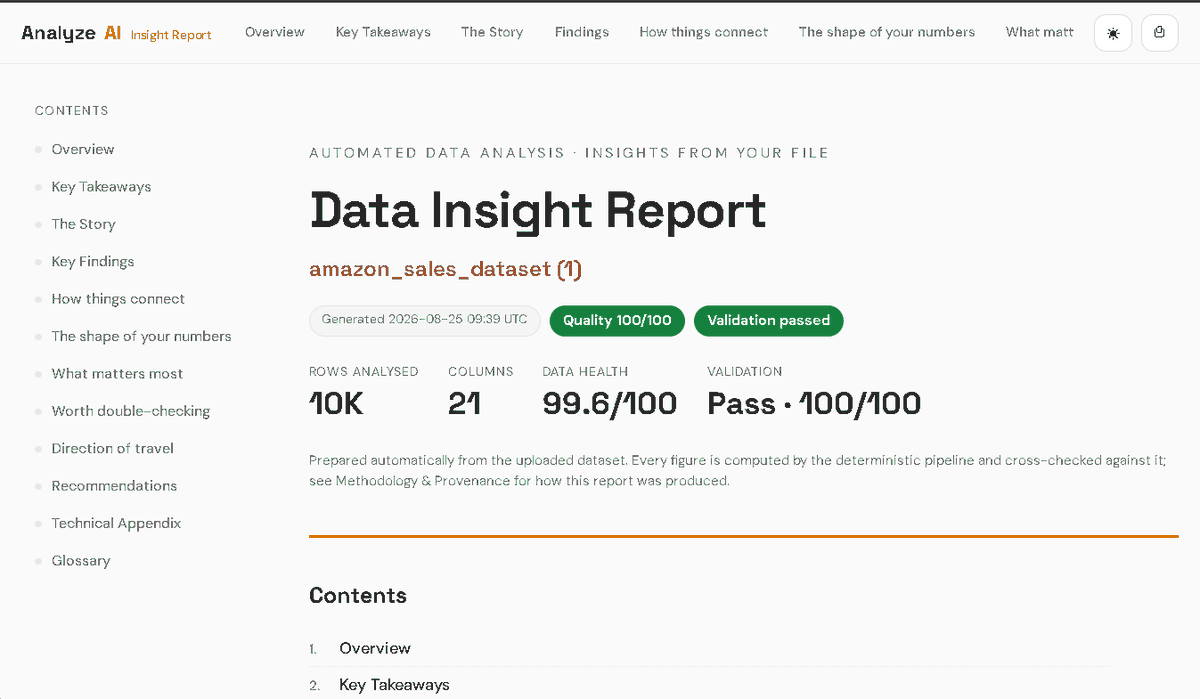
Built a 7-agent LangGraph pipeline that turns messy financial/sales CSVs into a full analytical report — with only 2 of the 7 agents actually calling an LLM.
Here's why that ratio matters 🧵
Output Validation sits between Insight Generation and Report Generation specifically to scope LLM retries — if the insights don't check out, I retry just that step, not the whole pipeline.
Full paper + code (ROUGE-L, Bradley-Terry, SelfCheckGPT, kappa — all from scratch):
🔗 Paper: https://t.co/hzLjXbt1CT
🔗 Code: https://t.co/GAji97Tmuh
#AIAgents#LLMEval#MachineLearning
Everyone's shipping AI agents. Almost no one is checking if their outputs are actually correct.
I spent a week building an eval pipeline to test this — and found something that should worry anyone using "LLM-as-a-judge."
Lesson:
reliability (a consistent score) ≠ validity (the correct label).
If you're using an LLM judge in your pipeline, check per-class not just one aggregate kappa.
I stopped reading PDFs. I started talking to them instead.
Built Contextra AI — a RAG system that turns any document into a knowledge base you can chat with, summarize, and turn into flashcards.
Full-stack, live demo, open source 🧵
Try it live: https://t.co/cFOjlIc7ML
Code: https://t.co/UDzHz4NmXa
Would love feedback from anyone working in RAG/LLM systems.
#AIEngineering#RAG#BuildInPublic
I'm a CE student building toward remote AI Engineer / Forward Deployed Engineer roles. This is how I'm learning end-to-end — not just calling an API, but designing the retrieval architecture and product around it.
Open to opportunities 👋