@morgancfung joined us earlier this year and within his first couple months he:
- Played an instrumental role in the development and launch of the Pulse MCP
- Enabled agentic payments on our platform
- Improved our schema endpoint
- … and has been steadily building ever since.
Morgan came on ready to hit the ground running, and his energy for the mission has been apparent not only in what he ships but how he does it. I’ve seen him meet every question with curiosity.
We’re hiring for people who are energized by the idea of having a story like this. Roles below in comment!
Lots of love going into the @Pulse__AI API these past few weeks. the engineering team and I have literally been holed up in our conf room for the past 13 days in design meetings.
We think the bar for products in our space should be a lot higher. great models deserve an equally great API, thoughtfully designed down to the smallest details.
Can’t wait to show what we’ve been cooking. Sneak peeks coming soon…
The most regulated companies in the world already run their data on @Snowflake, yet much of their most valuable information never makes it there because it sits in well logs, engineering schematics, scanned field records, lease agreements, and policy documents that no warehouse can read on its own.
@Pulse__AI closes that gap by reading documents as they land in a secure Snowflake stage and returning the results as governed tables, with structured fields, a confidence score on every value, and a link back to where each one appears on the page. Clean documents flow straight through, while only the uncertain values are routed to a reviewer, and every correction is logged alongside the data it changed.
For an energy operator, that means decades of well logs become something a geoscientist can filter across thousands of wells, and for a bank it means contract terms sit next to the exposure data they govern, so the documents stay the source of truth while the business can finally query them.
More below.
Read the full blog: https://t.co/QnYIvK3bfA
A big focus for our team at @Pulse__AI is making the data AI agents receive more useful.
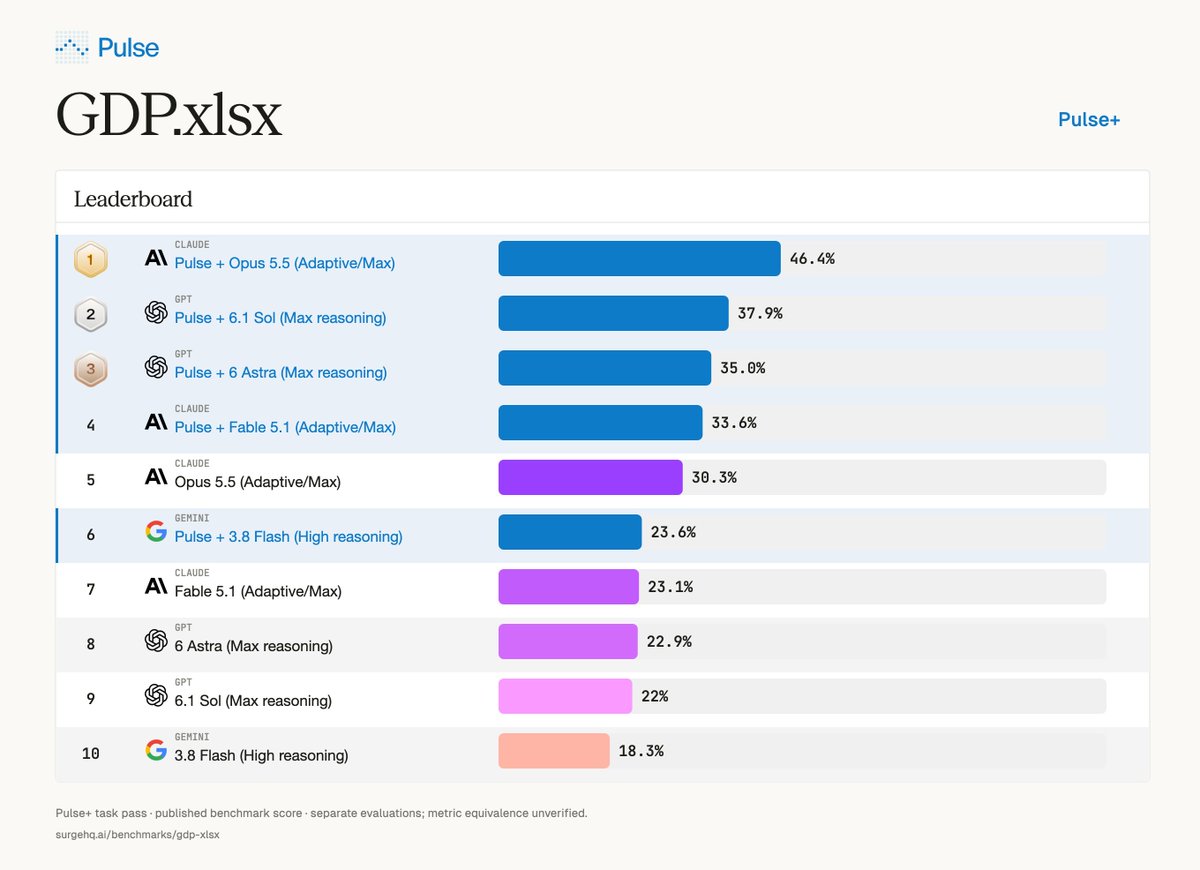
Huge congrats to the @HelloSurgeAI team on GDP.xlsx, a strong benchmark testing spreadsheet reasoning across finance, engineering and healthcare.
With Ultra 2, our latest model, we’re focused on preserving hidden content, formulas, complete records and visual context within these enterprise documents. We evaluated Pulse’s spreadsheet extraction pipeline using the benchmark’s OpenHands agent harness, providing structured text and image evidence upfront.
Our latest reported task-pass rates, compared with our earlier Pulse-assisted results:
- Claude Opus 5.5 46.4% (up from 41.4%; +5 percentage points)
- GPT-6.1 Sol 37.9% (up from 32.9%; +5 percentage points)
- GPT-6 Astra 35.0% (up from 30.0%; +5 percentage points)
- Claude Fable 5.1 33.6% (up from 28.6%; +5 percentage points)
- Gemini 3.8 Flash 23.6% (up from 18.6%; +5 percentage points)
Better data gives agents more to work with, read more here: https://t.co/4JFNPQaLd8
A few members from the @Pulse__AI engineering and research team are at Runtime by @modal in San Francisco today. Thanks to the Modal team for the invite.
They work on the research behind our vision-language models and inference engineering. Modal’s been a great partner, and we’re excited to run our production systems on them!
Come say hello if you're around!
Another day, another benchmark broken. @Pulse__AI schema v2 scores #1 on LongExtractBench-50, the public set of the long-document extraction benchmark Reducto commissioned and Micro1 ran.
Pulse scores 99.7 precision and 99.7 recall, run through Micro1's published harness and grader on the 50 released documents. This was done with 0 custom configuration on Pulse.
Reducto, who commissioned the benchmark, published 99.3. One caveat: the leaderboard was scored on 225 documents and 50 are public. @micro1_ai , happy to run our models through your private set, or have your team run it as well!
Astra and Fable are genuinely excellent at reasoning over text, and dont get me started on how much ive enjoyed coding with these new models. the problem is that enterprise documents are not only text.
The failures are the same on the models we test. Past ~50 pages, recall drops hard and the model does not notice, so it returns a confident result with most of the values missing. Schema logic, like "use the current period column" or "sum these rows unless a subtotal exists" starts drifting super quickly.
The economics also dont help - running these complex/long docs through a coding agent costs 15 to 30 cents a page before retries, with no auditability on the output
Each generation of oai/ant models is a large jump on reasoning and coding benchmarks , but a considerably smaller step on enterprise documents. Progress here comes from models trained on the problem directly
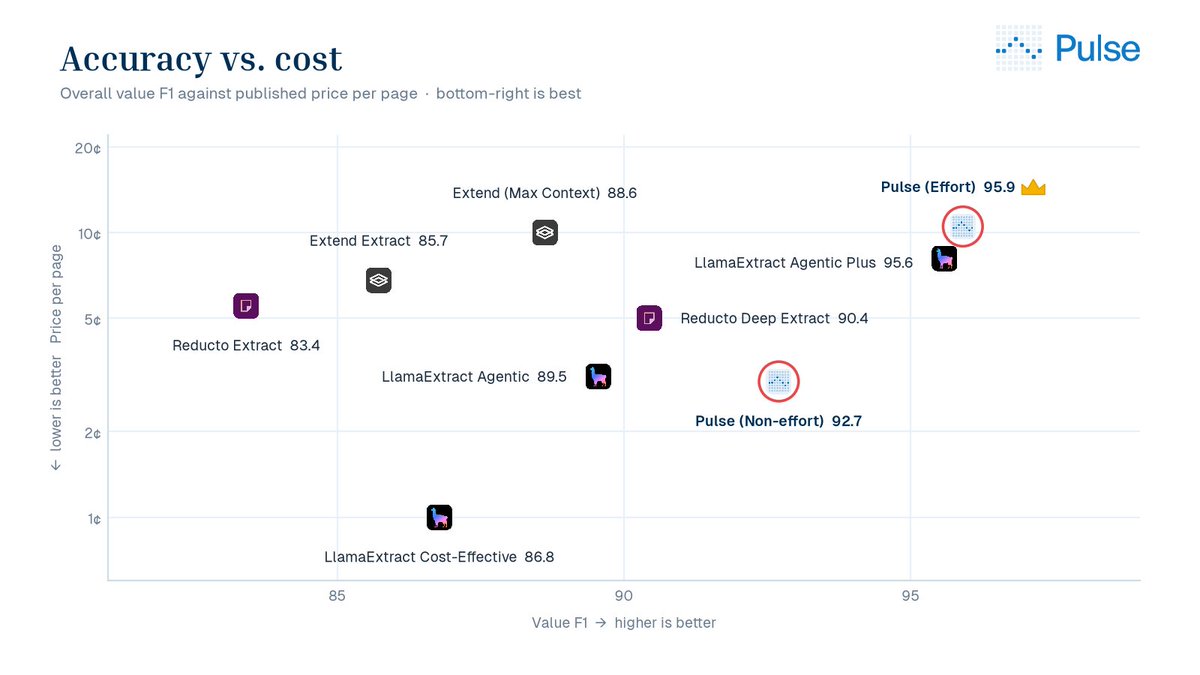
Awesome to see the latest results from our Schema V2 model. The price/accuracy curve has been a huge frontier push for our team, and Pulse non-effort is a sleeper:
• Pulse Non-effort: 92.7 at $0.015/page + parsing
Meanwhile:
• LlamaExtract Agentic: 89.5 at ~$0.03/page
• LlamaExtract Agentic Plus: 95.6 at ~$0.08/page
• Reducto Deep Extract: 90.4 at ~$0.05/page
And if you want maximum accuracy, Pulse Effort reaches 95.9 at $0.09/page + parsing.
Try it out now!
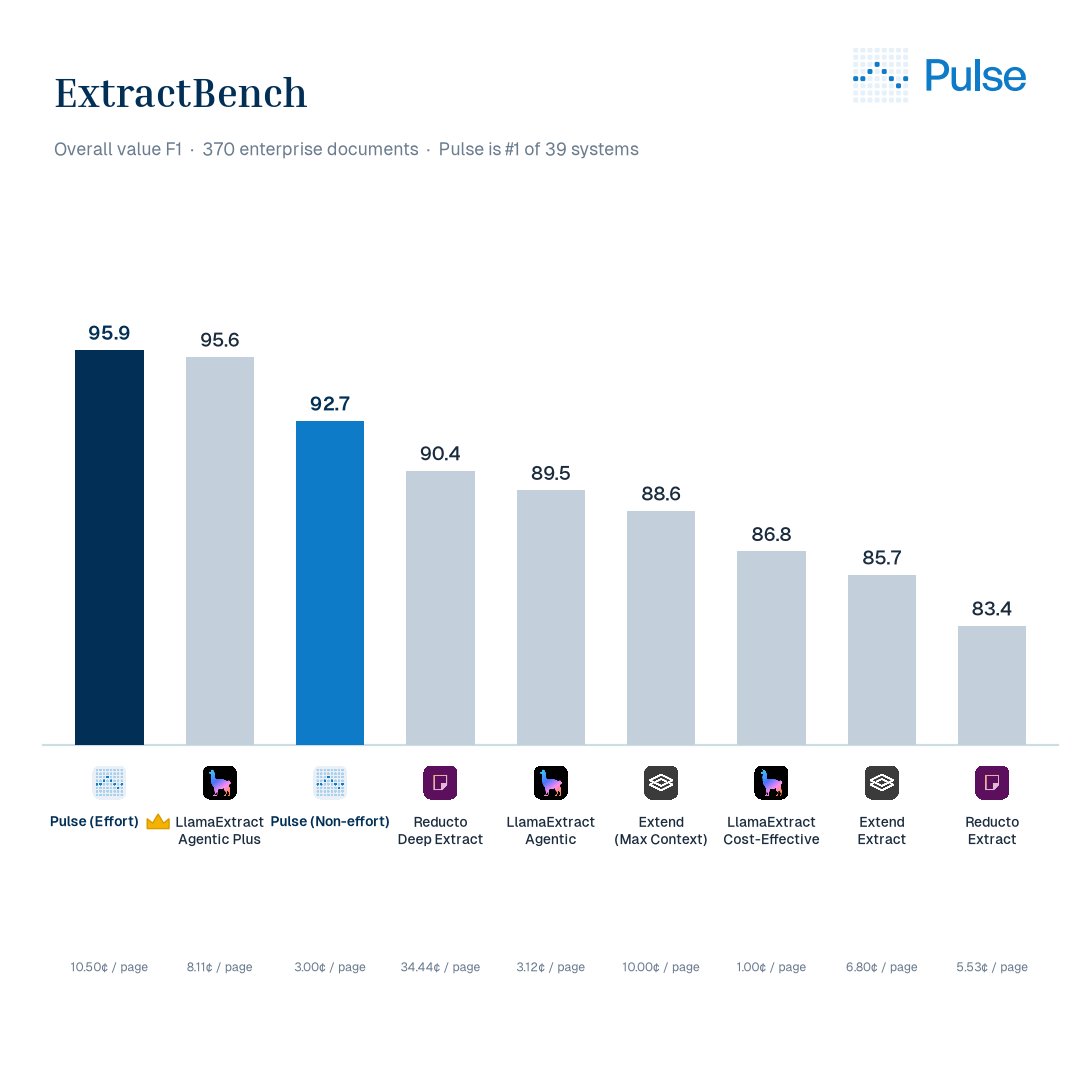
@Pulse__AI is now #1 on ExtractBench.
ExtractBench is LlamaIndex's open benchmark for schema-guided extraction from enterprise documents: 370 real documents, 4,869 pages, and 67 schemas spanning SEC filings, customs entries, court exhibits, energy filings, and scanned forms with handwriting.
Across 39 systems, including frontier models, coding agents, and specialized extraction APIs, Pulse ranks first with an overall score of 95.9.
The board also measures cost, and Pulse's standard mode makes the case on that axis. It ranks #4 overall with a score of 92.7, ahead of GPT-6 Astra, Reducto Deep Extract, and every open-weight model tested, while running at a fraction of the price.
This is the same schema extraction system that ships in the Pulse API today.
We have an exciting set of models releasing very shortly, our research team has models training every day - stay tuned!
A few months ago, the team at @Pulse__AI launched PulseBench-Tab, our frontier table extraction benchmark with 1,820 human-annotated tables across 9 languages.
Our evals team has updated the benchmark against the latest generation of document parsers and frontier models.
Pulse Ultra 2 remains state of the art on the benchmark, and is now just 1 credit per page. As always, everything is open source: the scorer, the runners for every provider, the dataset, and every prediction.
Leaderboard: https://t.co/C6BSNVwFNt
GitHub: https://t.co/Lq1AzD7lI0
Dataset: https://t.co/SAmoZHYP5R
PRs welcome if you'd like a provider added or a sample corrected. Excited to keep pushing the frontier of table extraction.