At the beginning of June, a part of @QuEst_BMBF officially entered the second round with a project extension. During this time, you can expect the publication of a guide to assessing the reusability of audiovisual data and semi-automated quality assurance tools. Stay tuned!
For further publications and results on the topic of reusability and evaluation of audiovisual annotated language data, please have a look at our project homepage as well: https://t.co/9YUY7HZee0
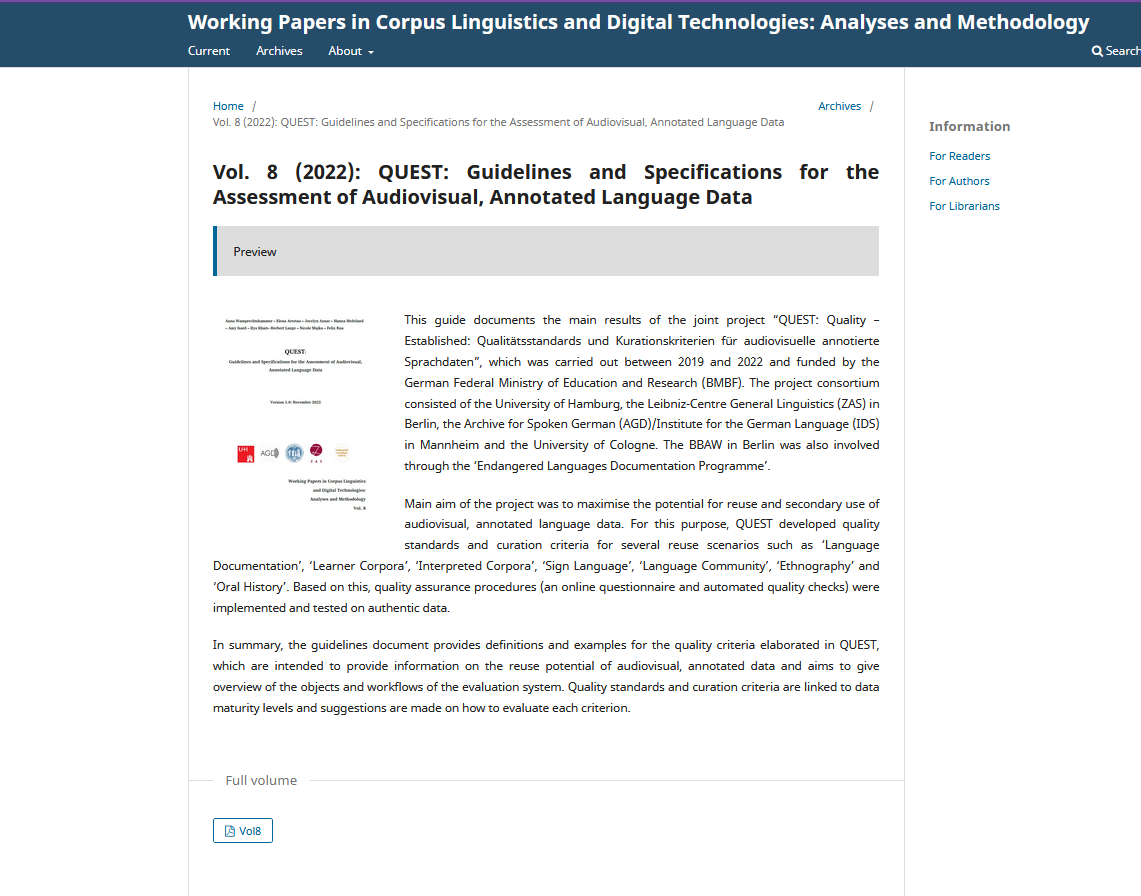
Wit the start of the new year, @QuEst_BMBF finally ends its runtime and says goodbye with the publication of a guide to assessing the reusability of audiovisual annotated language data:
👉https://t.co/qsMxy7JC2T
🔔Today at #LDA2022: @pietaetskirsche, Jocelyn Aznar & @AmyIsard present an automatic gloss checker for annotated corpora recently developed in QUEST within the quality assurance measures.
👉https://t.co/eh7fZQaJBL
📣 The next training "Improving corpus quality in language documentation" will be given by Jocelyn Aznar and Herbert Lange in 20 minutes (at 22:00 GMT+11). See you there! #LDA2022 Find out more about @QuEst_BMBF 👉 https://t.co/vvjb3SHVo4
📢How to improve Corpus Quality in Language Documentation? In a hands-on demonstration of the quality assurance processes and tools developed within QUEST Jocelyn Aznar & Herbert Lange give answers in today's #LDA2022 training session
👉https://t.co/tr3c6vBjKq
Just published in Selected Papers from CLARIN 2021: @AmyIsard & Arestau, Elena (2022): Curation Criteria for Multimodal and Multilingual Data: a Mixed Study within the QUEST Project.
Take a look👉https://t.co/lgyxff1uBI
Today at #LREC2022: @pietaetskirsche & Jocelyn Aznar present their paper on "RefCo and its Checker: Improving Language Documentation Corpora's Reusability Through a Semi-Automatic Review Process". Have a look at the paper here: https://t.co/QrCciwoK1K
Conference week: @QuEst_BMBF will be present at #LREC2022. @AmyIsard will talk about the anonymisation of sign language corpora, @pietaetskirsche & Jocelyn Aznar present results on reusability of language documentation corpora:
https://t.co/eXtNKJuD4F / https://t.co/QzwwkC4V4T
Interoperability across resource collections with the ISO/ #TEI standard for Transcription of spoken language as an exchange format @IDS_Mannheim @AGDIDS @TSRISEUBAS @QuEst_BMBF#CLARIN2021
#CLARIN2021 Paper presentation
Quest project: curation criteria for multimodal and mutlilingual data to improve reuse potential of corpora @QuEst_BMBF @AmyIsard
Today Amy Isard and Elena Arestau represent QUEST on #CLARIN2021 with a paper on "Curation Criteria for Multimodal and Multilingual Data: A Mixed Study within the Quest Project". We are looking forward to it! @AmyIsard
Heute live auf der virtuellen GAL-Sektionentagung (@galwue21 ): Unsere Mitarbeiterin Elena Arestau stellt im Rahmen der Postersession einen Ansatz zur nachhaltigen Dokumentation von audiovisuellen Lernerkorpora vor. #galwue21
Today we presented QUEST @ESUDH and discussed how to optimise the re-use potential of audiovisual language data from a generic and discipline-specific perspective. @AmyIsard #QuEst_BMBF
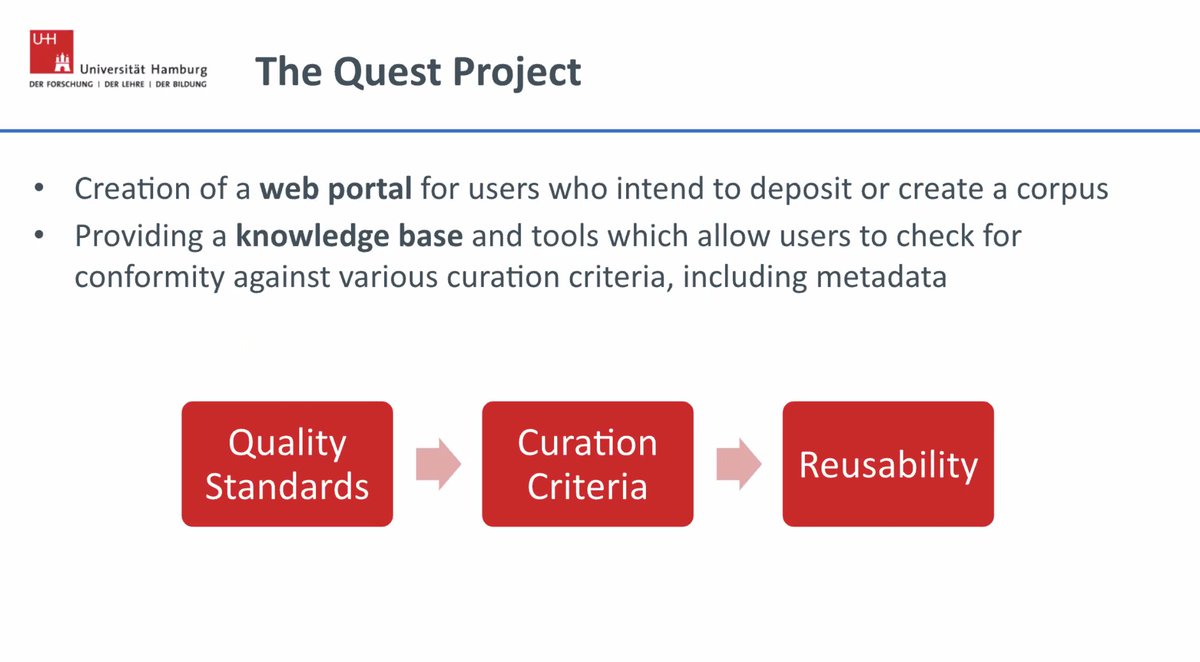
@QuEst_BMBF is establishing criteria to exploit the reuse potential of multilingual resources. These criteria will be incorporated into quality assurance tools such as web-based quality checks to support researchers in the creation and curation of such resources. #DayofDH2021