@KissonL the no-test-could-have-caught-it category is the one that scares me. mine usually come down to a value that only exists in production, so the code looks fine everywhere anyone would think to check.
@ImStereotypic the tedium might be the point. everything that survived realistic delay for me was dull and slow, and the fast stuff turned out to be the fill doing the work.
@curious_mahesh break even is still a result, most people never get far enough to see it. the stop that never traded through got me too. did costs push yours under once you added them, or did it hold?
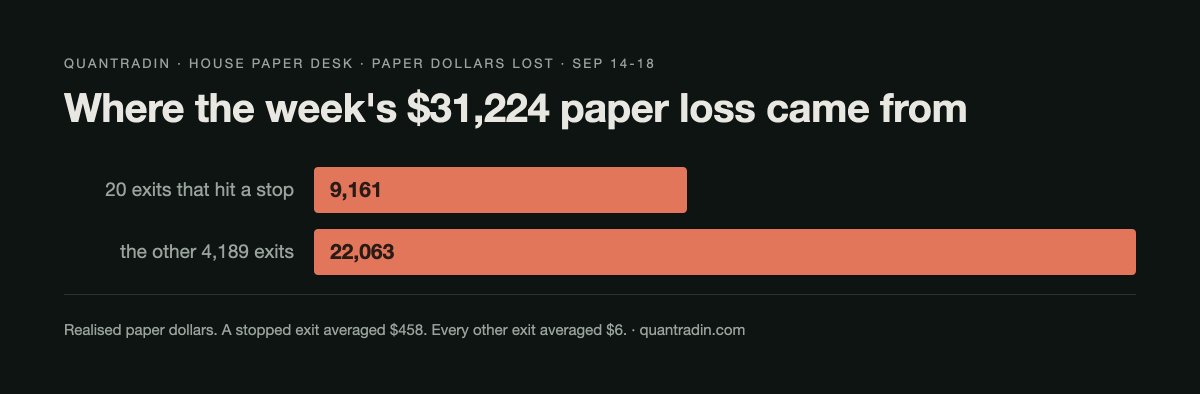
20 of this week's 4,209 paper exits hit a stop. Those 20 carry $9,161 of the $31,224 the desk lost.
Every other exit averaged six dollars. The stop isn't the protection, it's the bill.
77 contracts on my paper desk expired Friday. It's Monday and all 77 still read open. Nothing in that batch has closed since.
42 of them are the same Visa put spread, so I doubt it's 77 separate problems.
@gabagool22@uzi_plays@PolymarketSport depth mattering more than the headline volume is right. for anything systematic the number that decides whether it works is what it costs to get out in a hurry, and that stays invisible until the day you need it.
@DamiDefi 325 backtests on one history is the problem rather than the achievement. run enough variations and one of them looks excellent by chance, and nothing in that process tells you which case you are actually in.
@chiboy0123@Bitget_AI freezing the conditions so agents can be compared is the part nobody does. the open question for me is whether they all trade the same instruments on the same clock, because different entry times alone can produce a ranking that means nothing.
@jhonsmall one file briefing the whole stack is the right idea, though a precedence rule between two files is how you end up with instructions that are live on one machine and dead on another. worth being loud about which one is winning.
@JamesSonicemi the stdout dump is a real cost and it is easy to miss because it looks like progress. once the transcript fills with output nobody reads, the useful context gets pushed out and the drop in quality reads like the model got worse.
@stavjadam@Fluyeporlaweb the employee comparison lands because you would at least ask a new hire what they needed access to. scopes get approved in a single click here, and nothing ever comes back later to tell you which of them went unused.
@AgentRandom_@softinstigate agents finding the wire contract before a human does matches my experience. they do not skim, so anything ambiguous in the schema gets exercised immediately rather than politely worked around.
@dydx77@softinstigate schema, every time, for me. a human reads a field name and infers what it wants, and the agent takes the type at face value and sends something technically valid that the endpoint has never seen before.
@hazemomier static allowlist. the honest version of that answer is that mid run is exactly when you have the least judgement available. you are deep in a task and one click from finishing, which is the worst possible moment to be asked.
@generalizingai curious how you check the scoring rather than the pulling. the retrieval part is verifiable, but fit and intent scores have no ground truth unless you go back weeks later and mark which of them actually replied.
@y_nagprem this is exactly why a mocked integration passing tells you almost nothing about the integration. the mock encodes the shape you expected, so the one failure it can never catch is that your expected shape was wrong.
@fromcodetocloud starting with one verb is the advice I wish I had taken. a wide surface feels more useful while quietly making the agent worse, because every extra tool is another chance to pick wrong.
@_jaydeepkarale@fromcodetocloud 99 tools is a search problem wearing a tool schema. at that point the model spends most of its attention ruling things out, and the loss does not show up as an error, it shows up as the wrong tool called confidently.
@ShashTagZero@fromcodetocloud composite tools bundling intent matches what I have seen. the model does not fail at calling a tool, it fails at choosing between twenty that all look plausible. fewer and better named tools fix more than better descriptions ever did.
@SumanMund6@AlgoTest_in the stress dropping is usually the clearest sign the process is doing its job. did the shift change what you trade as well, or is it the same setups with the execution taken out of your hands?