If you're curious about how LLM inference works, start here: Prefill vs. Decode.
Includes original measurements and firsthand experience running Qwen3.8-27B. https://t.co/69xEb8B7Fo
@AppaloreLabs - guessing you mean this - https://t.co/95iul7NwKR - but looks like that is API only - not open weights yet. Qwen has Qwen-Audio-3.1-ASR-Next - which is the one with diarization - and combines transcription and diarization in one model.
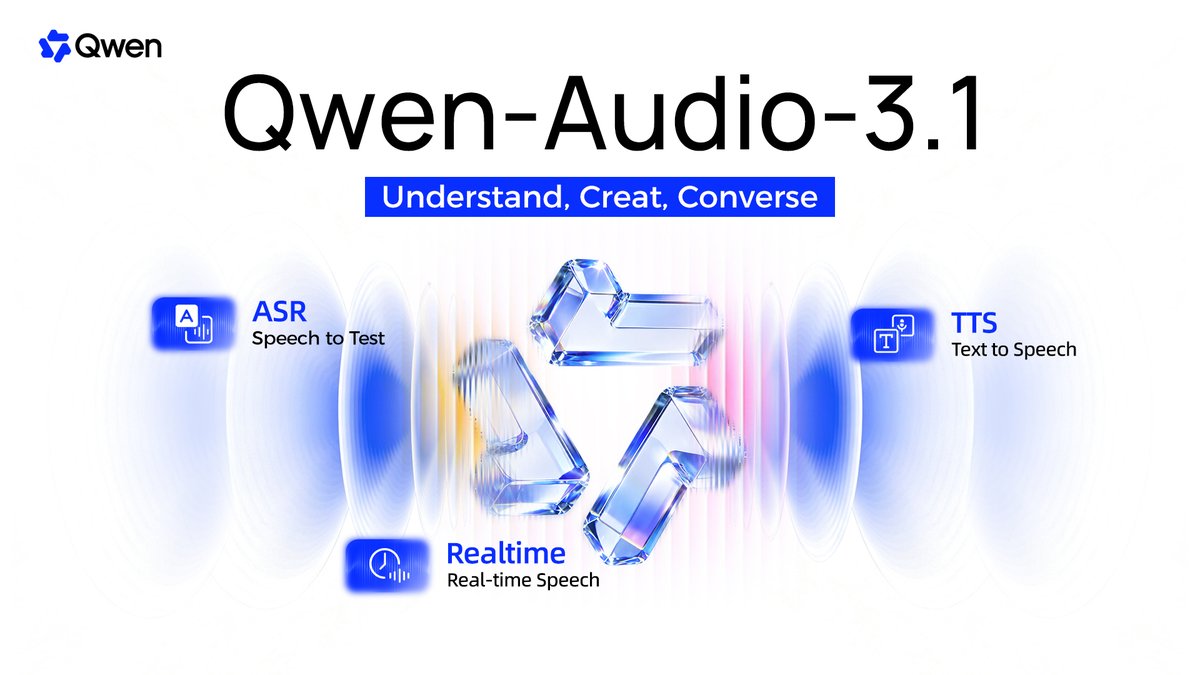
⚡ Meet Qwen-Audio-3.1! ASR, TTS & Realtime are fully upgraded, joined by two new models: TTS-Next for audio creation and ASR-Next for audio understanding.
Five models, one complete audio stack: understanding, generation, interaction & creation.
Plus big price cuts across the lineup: TTS ~70% off, Realtime ~85% off, and ASR up to 95% off.
Highlights: 🥳
- ASR: stronger multilingual & dialect recognition, plus native polishing that auto-removes fillers & repetitions for cleaner, more logical transcripts.
- ASR-Next: supports multi-speaker ASR with speaker labels, timestamps & aligned transcripts, and understands emotions, ambient & machine sounds for sound captioning, event localization, audio QA & reasoning.
- TTS: multilingual & dialect synthesis with natural cross-lingual voice transfer; control emotion, speed & style via simple instructions.
- TTS-Next: unified LM + diffusion framework generating voice, sound effects & background audio in one pass for audiobooks, podcasts, games & ads.
- Realtime: speak & listen at once with anytime interruption, just like a real call; it even slows down and responds empathetically when it senses a low mood.
Unlock the full potential of Qwen-Audio-3.1! 👇
- Blog: https://t.co/e0M8wvj8Kg
- Qwen-Audio-3.1-ASR:
https://t.co/88lPQTPxyz
- Qwen-Audio-3.1-Realtime:
https://t.co/Y63sdtK2AC
- More APIs: coming soon @qwen_cloud
For the voice AI enthusiasts - Nvidia launched their new model today that a ton of people are tweeting about - but note that it is a "Diarization" only model - ie - the model tells you who spoke when, not what they said! You need to couple this with a ASR model - an automatic speech recognization model - to get the text.
Voice agents still don’t understand who’s speaking to them. That’s a huge gap compared with humans, hidden by all the “phone-call” demos. But that changes today!
NVIDIA is open-sourcing Nemotron 3 Diarization: a model that can reliably track speakers in live conversations, under a commercial-friendly license! In my tests, the quality is really good with one-second speech chunks. So we can use it for voice agents!
I tested it with Reachy Mini and speech-to-speech running on a DGX Spark. It’s super fun to see the robot notice a new voice, ask for a name, and remember it.
The model has day-zero integration with Transformers!
Kudos to the NVIDIA team for shipping useful tools for the whole community!
When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗
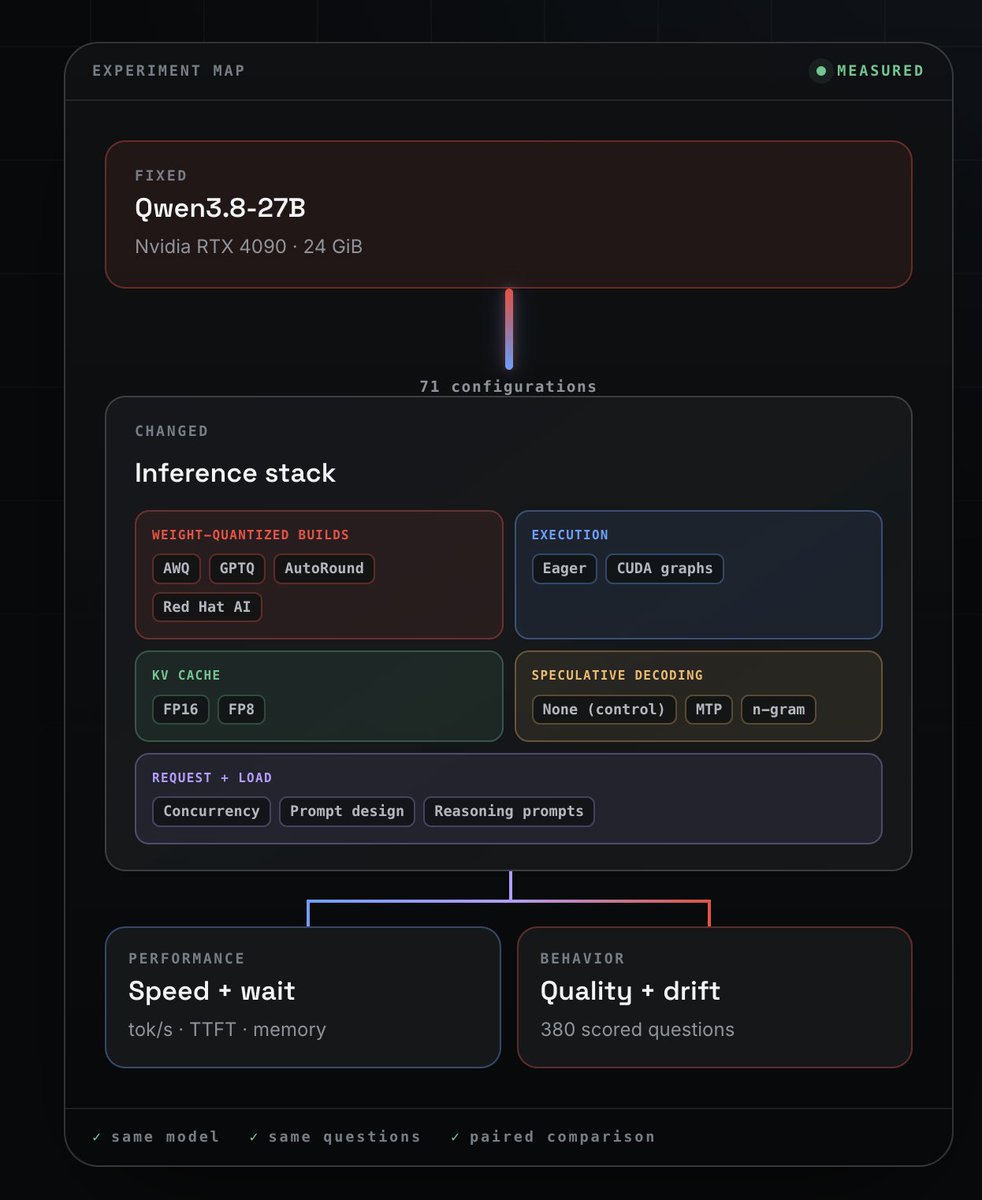
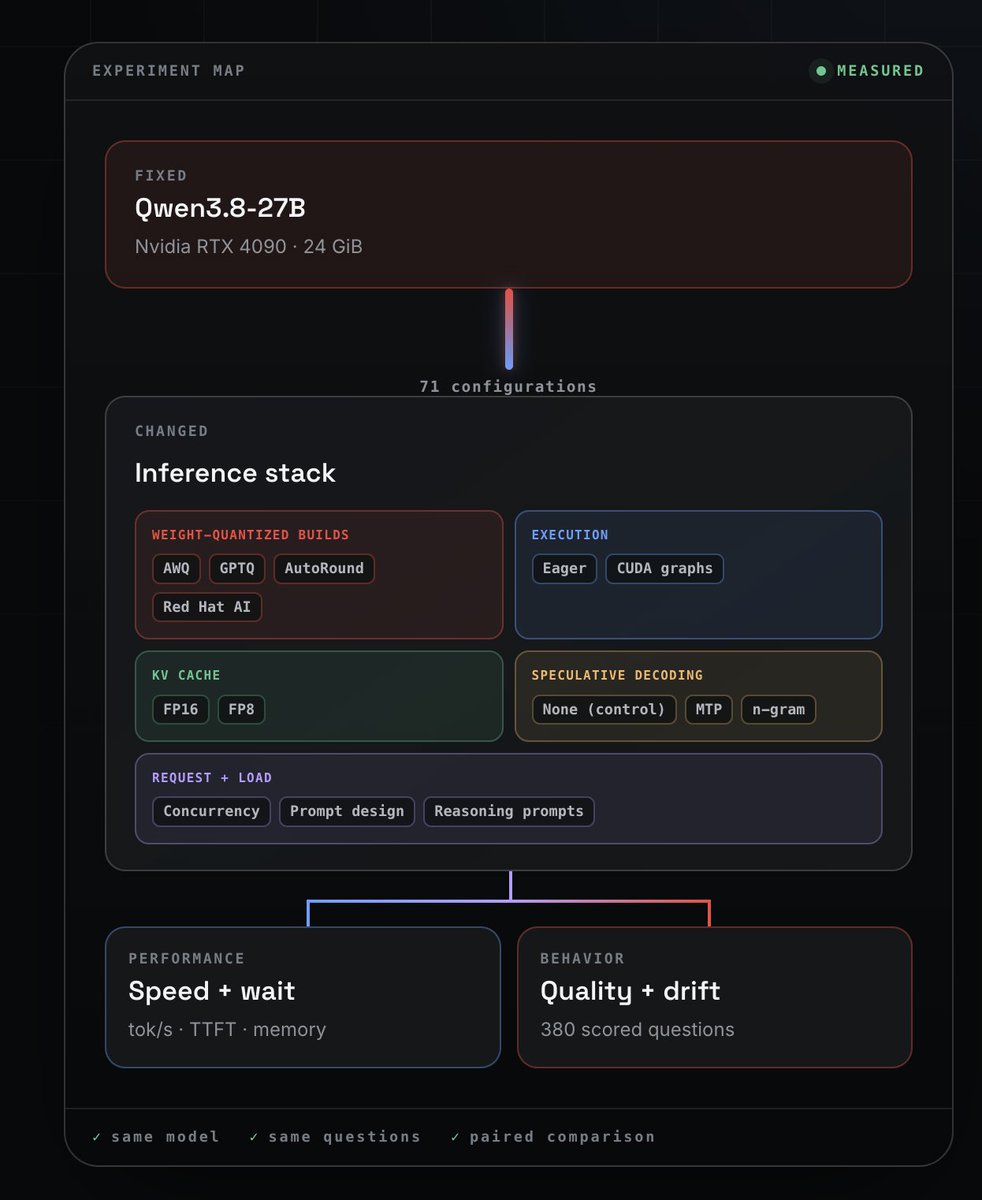
Would be great to see how Bonsai 2 benchmarks against various quantized Qwen3.8-27B models across these configurations — especially with the PTQ1_0/PQ2_0 + Hadamard setup that is required for the Bonsai 2 model. @RadianVector - yet another thing for you to do 😀 https://t.co/aI2DWGu2u3
The upcoming tutorial on AI and LLMs is designed to demystify what happens inside these systems & provide a clearer understanding of how AI works - as it becomes increasingly relevant to all of us
If you have questions, topics you’d like us to explain in more depth, let us know!
Learn about the various inference settings and the inference stack you can use on your GPU. https://t.co/tyoQZOBSAb - in night (dark) mode. We will be launching an easy to understand AI, LLM tutorial with great graphics - follow and connect if interested.
Learn about the various inference settings and the inference stack you can use on your GPU. https://t.co/tyoQZOBSAb - in night (dark) mode. We will be launching an easy to understand AI, LLM tutorial with great graphics - follow and connect if interested.
Our latest benchmark study on Qwen3.8-27B is now published. Reach out for more info, or if you'd like a similar study on another open-weight model. Study: https://t.co/tyoQZOBSAb