Weekly drop #4 is live on the Respan AI Gateway.
Top deal: Hy4, 70% off. $0.25 in / $0.75 out per 1M tokens.
Also this week:
GPT-6 Astra: 18% off
Claude Sonnet 5.5: 15% off
Qwen 3.8 Flash, Qwen 3.8 Max, Kimi K3.1 Pro: 30% off
MiniMax M3.1 Flash: 20% off
Gemini 3.8 Flash, Gemini 4 Argon: 50% off
DeepSeek V4.1 Flash 1017: 30% off
No transaction fees. Full prices in the comments.
New drop every Monday 🧵
We’re seeing more people build with realtime and live chat.
Respan OSS Gateway was built for compatibility from day one, and now we’re putting more into realtime.
Through Respan, realtime models are interchangeable: keep your OpenAI Realtime client, switch to Gemini Live or Phonic.
The gateway reads each one into one set of events (audio, transcripts, turns, barge-ins, tool calls) and writes them back out in the other’s.
Checkout: https://t.co/7CNut8FQmB
Retell just crossed $100M in revenue run rate.
$10M to $100M in 17 months. Profitable. $4.6M raised.
From day one, we’ve focused on solving the hardest parts of deploying voice AI in the product itself, so customers can build, manage, and improve their own agents without depending on us.
Our bet: the future of the contact center belongs to the teams who run it.
Proud of our team. Grateful to every customer who believed in us.
We trained a custom model to kill the only moat CRMs have, switching cost.
@RespanAI asked @octolane to migrate them off Attio to Octolane. Octolane migrated years of their data in under 4 minutes.
That’s Exodus 1, our in-house migration model. It reads your old CRM’s schema, maps every custom field and object, carries over full conversation history, and enriches every account and contact in flight.
Attio customers now migrate in under 5 minutes. HubSpot customers in under 20.
And we’re already training Exodus 2 to migrate Salesforce customers in under 30 minutes.
we're making Gemini 4 Carbon free on @RespanAI
google's best model yet, and it's better than Opus 5.5
no card, no credits, just an API key
48 hours only. try it now
https://t.co/FfzYFe4HYo
hi @X i'm Kelly! sf-based, looking for more friends in tech :)
a lil about me:
> journalism grad
> used to make documentaries
> now making launch videos at an AI startup
> learning to code with claude code, slowly
would love to meet anyone building cool things, especially if you still shoot film for fun 📷
Prompt caching: why does Anthropic only offer 5-minute and 1-hour options?
It comes down to where your cache is stored.
A cache can sit in GPU memory (fast, expensive) or CPU memory (slower, much cheaper).
Either way, keeping it costs money every minute. At some point it costs more than just rereading your prompt.
I did the math. The break-even point:
~5 minutes on GPU (HBM)
~1.5 hours in CPU memory (DRAM)
So when you pick 5 minutes or 1 hour, you’re really telling Anthropic where to store your cache.
we’re making Muse Ember free!
Meta’s newest and most cost-efficient model built for high-volume agent work.
no payment or credit card required.
1. create an API key on @RespanAI
2. call meta/muse-ember:free
fyi: free usage has a token limit. deposit $5 to raise it (still free).
Claude Fable 5.2 is live on the Respan Gateway.
Respan-only launch deal: 15% off, this week only
$6.80 in / $34 out per 1M tokens (was $8 / $40)
1M context · 128K max output · adaptive thinking
Model: anthropic/claude-fable-5.2
Weekly drop #4 is live on the Respan AI Gateway.
Top deal: Hy4, 70% off. $0.25 in / $0.75 out per 1M tokens.
Also this week:
GPT-6 Astra: 18% off
Claude Sonnet 5.5: 15% off
Qwen 3.8 Flash, Qwen 3.8 Max, Kimi K3.1 Pro: 30% off
MiniMax M3.1 Flash: 20% off
Gemini 3.8 Flash, Gemini 4 Argon: 50% off
DeepSeek V4.1 Flash 1017: 30% off
No transaction fees. Full prices in the comments.
New drop every Monday 🧵
shipped a small one today: redesigned the Models page on @RespanAI
recommended and discounted models are now grouped together and pinned at the top, so you can spot them at a glance
also open to any feedback on the gateway. if we adopt your idea, i'll send you $100 in credits
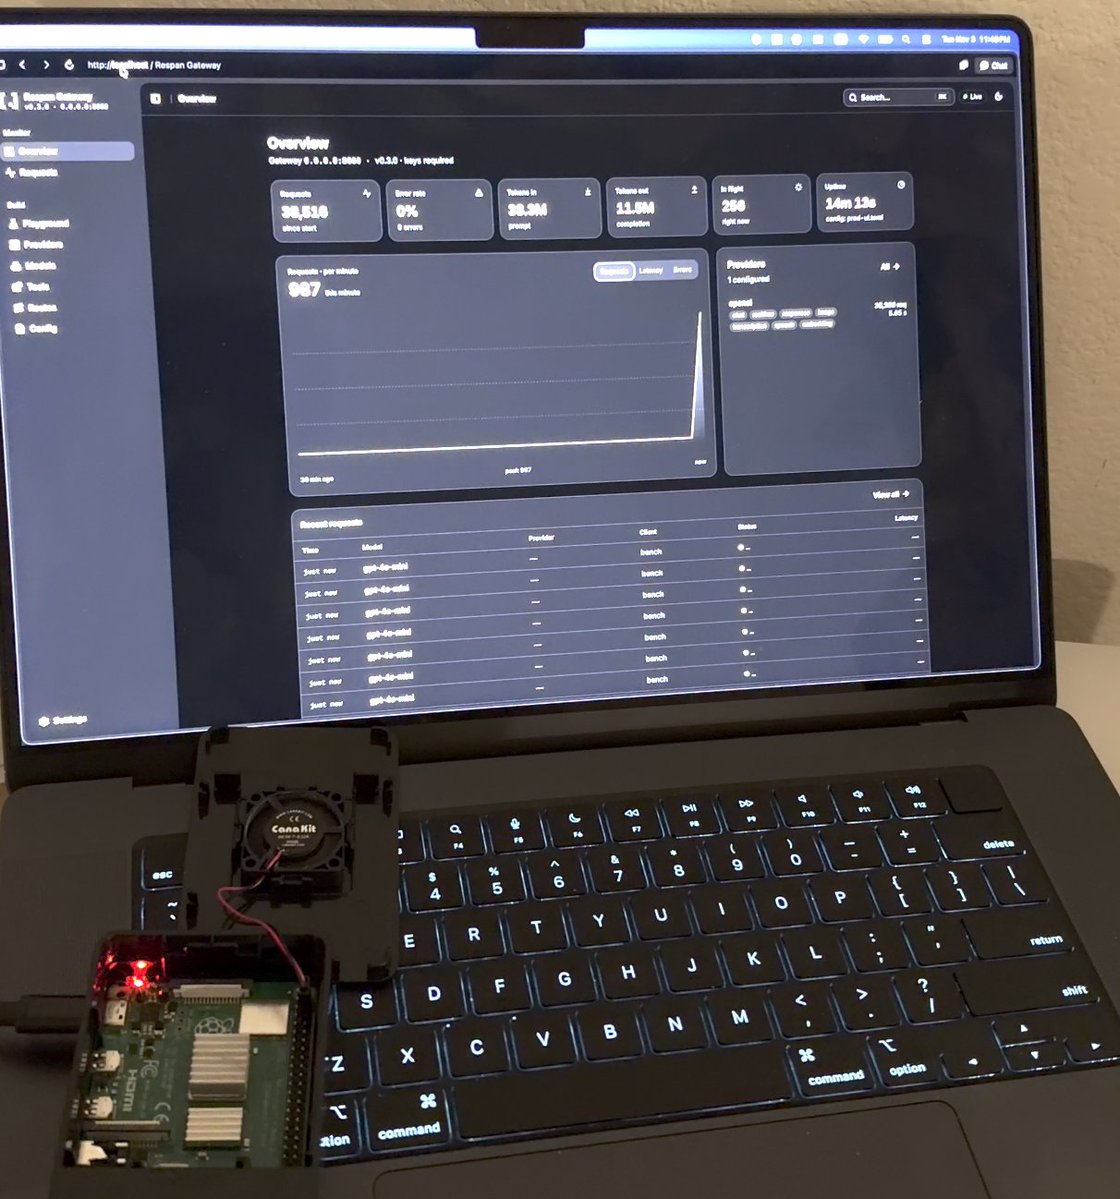
Respan Gateway runs on my Raspberry Pi 4: 20 MB of RAM, about 2 ms added to first-token latency at 100 concurrent streams.
At 256 streams, the 2 cores I gave it were maxed out: still only 35 ms added on a 1.8 GHz CPU.
I ran a 15-minute stress test: 40,718 requests with zero failures.
Now I kinda want to get a few more Pis for load balancing 😂
Respan OSS Gateway is also an MCP gateway.
Add your MCP servers to one config and every client connects to one URL.
- Credentials stay on the gateway
- Tools switch off without restarting clients
- Every MCP request can show up in Respan.
A reverse proxy isn’t enough. Each server needs its own session, and two servers can both have a search tool.
So the gateway holds a session per server and prefixes tool names: github__search, linear__search.
Tencent Hy4 is out, and Respan is the cheapest place to run it.
60% off list:
→ $0.3336/M input
→ $0.0168/M cached input
→ $1.0004/M output
That's 20% below every other gateway - and no platform fee on top.
Live within 30 min of release.
https://t.co/hQoCzzd8Lu
Tencent Hy4 is out, and Respan is the cheapest place to run it.
60% off list:
→ $0.3336/M input
→ $0.0168/M cached input
→ $1.0004/M output
That's 20% below every other gateway - and no platform fee on top.
Live within 30 min of release.
https://t.co/hQoCzzd8Lu
I used to film documentaries waist-deep in the ocean. now i film ai startup launch videos in a garage
documentary vs launch video:
> 130 hours of footage → 45s of screen recording
> waiting for golden hour → waiting for deploy
> b-roll of the ocean → b-roll of a cursor
> people who are shy on camera → engineers who are shyer
> blurring faces → blurring API keys
> the hero is a person → the hero is a dashboard
the job never changed: find the 10 seconds that make a stranger care