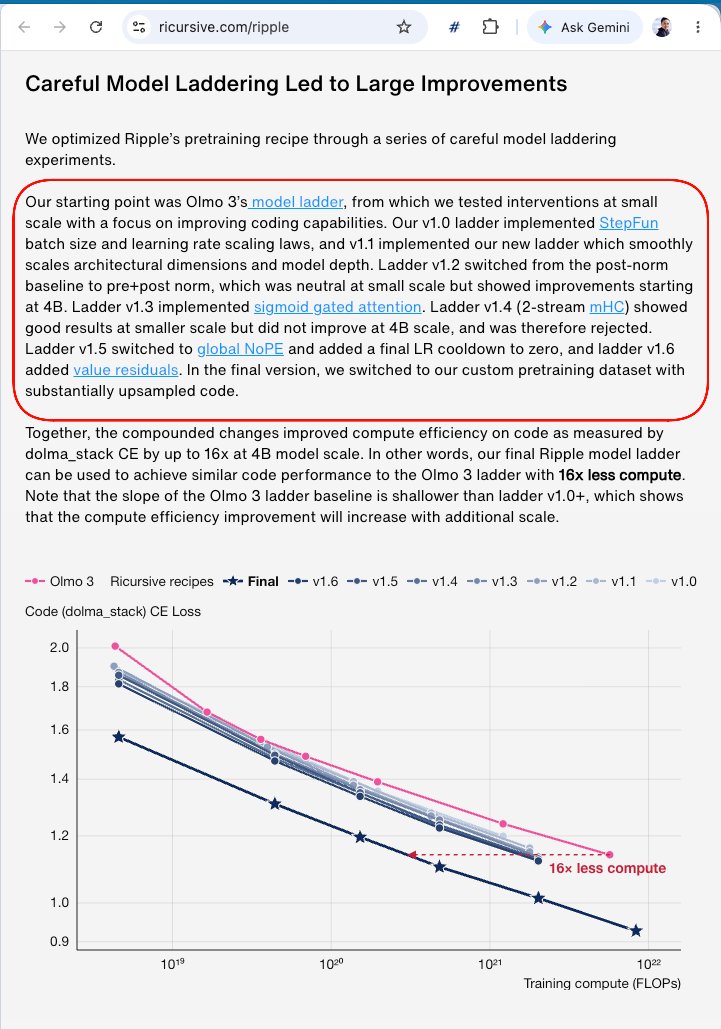
Today we release Ripple-65B Preview, our 65B dense LLM we pretrained from scratch.
Ripple sets a new state-of-the-art for U.S. open-weight models in agentic coding tasks, surpassing significantly larger models including Muse Spark Open-816B, Beam-501B, Inkling-975B, and Nemotron 3 Ultra-550B.
Learn more: https://t.co/Pe04ZKhkE9
We just set the U.S. open-weight SOTA on agentic coding. Tomorrow, @DZhang50 goes behind the scenes on Ripple-65B Preview with @zainhas of @togethercompute: dense over MoE, ablations, and the RL runs.
📆 Nov 17 · 11am PT
👉 https://t.co/H4dFLXvN8S
How do you build a small coding model from scratch?
@RicursiveAI 's Dan Zhang breaks down the architecture and decisions behind Ripple-65B Preview with @zainhas: dense over MoE, the ablations that held up (and didn’t), and what happened inside the RL runs.
Tuesday, Nov 17 . 11 A.M. PT / 2 P.M. ET
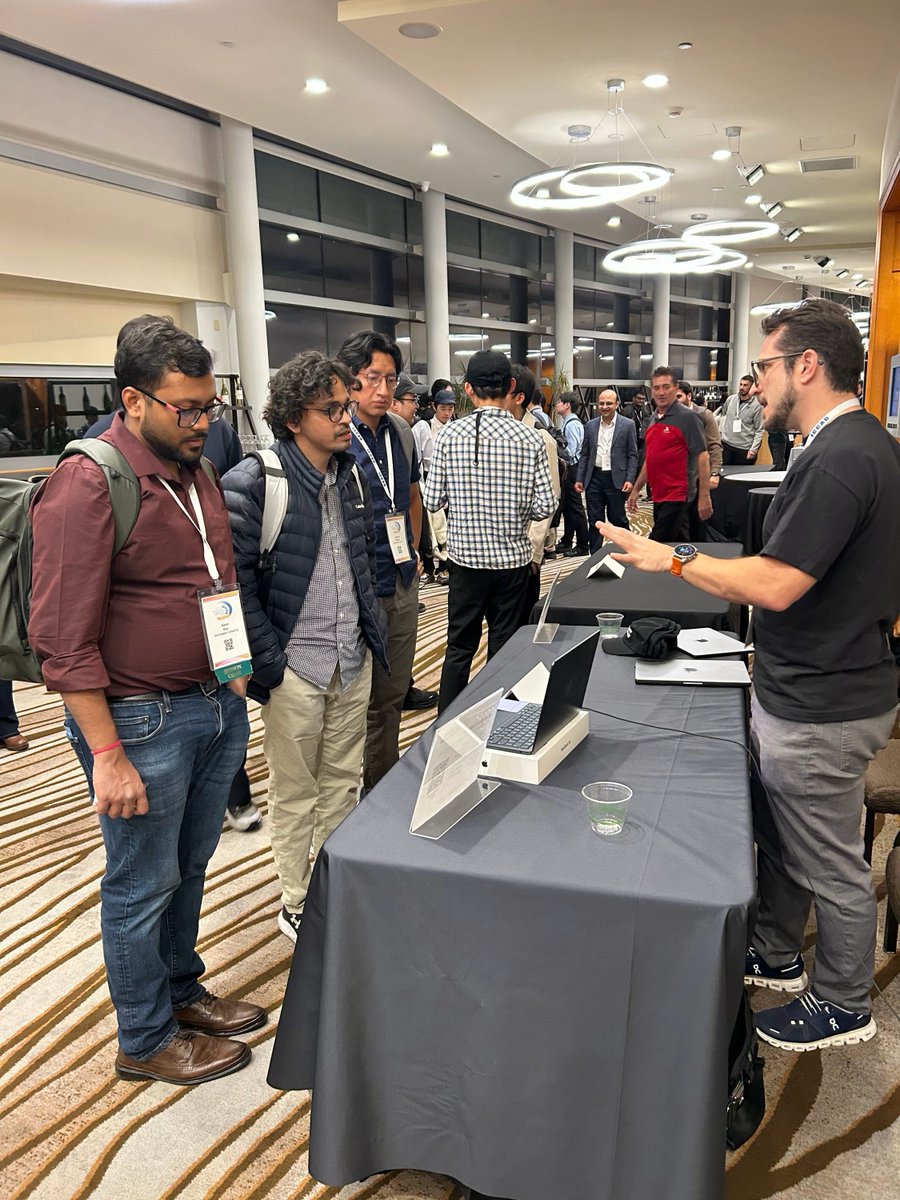
A fantastic week at @ICCAD 2026. The Ricursive booth was as busy as ever. It was great meeting so many talented researchers, engineers, and field experts.
We hire those who are the very best at what they do, and who do it with radical humility and kindness. Once you're here, you'll design algorithms, run large-scale experiments, and ship work that changes how chips get designed.
Join us: https://t.co/vR4jfmpeAk
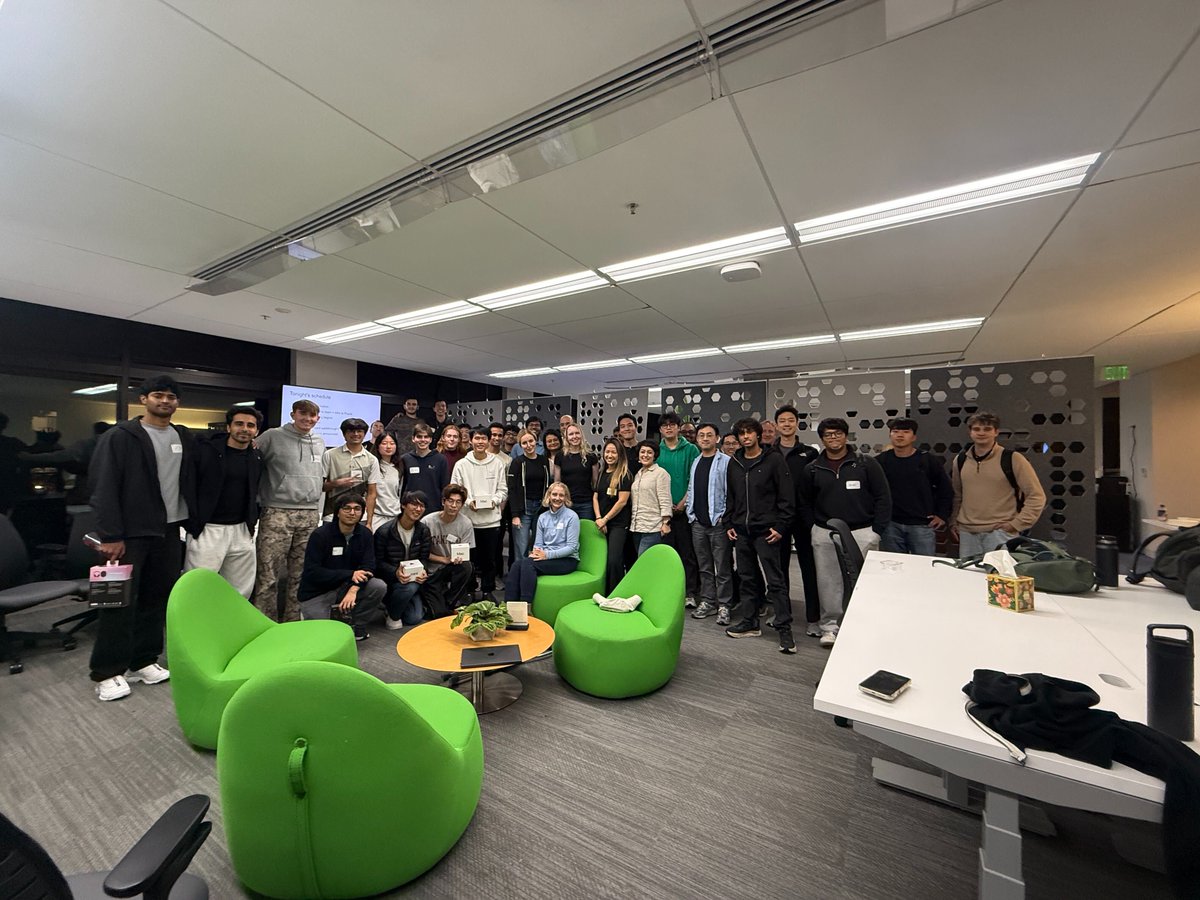
Last Friday we hosted the Ricursive Intelligence After Dark Hackathon, our first hackathon centered on our open-weight model release, Ripple-65B Preview. We brought together an incredible group of researchers, engineers, and builders to push the model in new directions. We saw some amazing projects spanning everything from CUA and Weight-Space Programming to model watermarking.
Huge thanks to everyone who came out, built something, and made the night memorable! This is just the beginning!
Last week, we released Ripple-65B Preview. A 65B dense LLM that set a new U.S. open-weight SOTA on agentic coding.
Join our very own @DZhang50, Founding Member of Technical Staff, and @togethercompute's @zainhas to learn how we did it.
📆 Tuesday, Nov 17 · 11am PT / 2pm ET
👉 Register at https://t.co/d4OUjY9L4E
How do you build a small coding model from scratch?
@RicursiveAI 's Dan Zhang breaks down the architecture and decisions behind Ripple-65B Preview with @zainhas: dense over MoE, the ablations that held up (and didn’t), and what happened inside the RL runs.
Tuesday, Nov 17 . 11 A.M. PT / 2 P.M. ET
Ripple 65-B Preview from @RicursiveAI is on Ollama. Built for agentic coding, with up to 1M tokens of context. Run it locally with full zero data retention.
Last week we released Ripple-65B Preview. This Friday, come build with it.
Ricursive After Dark Hackathon: Fri Nov 13, 3PM–10PM, at our Palo Alto office. Compute, dinner, and hardware prizes.
Applications close Thursday, November 12 at noon PT. Accepted participants will be notified by email Thursday night with the address and full details.
https://t.co/zkOcwkS8nD
Today we release Ripple-65B Preview, our 65B dense LLM we pretrained from scratch.
Ripple sets a new state-of-the-art for U.S. open-weight models in agentic coding tasks, surpassing significantly larger models including Muse Spark Open-816B, Beam-501B, Inkling-975B, and Nemotron 3 Ultra-550B.
Learn more: https://t.co/Pe04ZKhkE9
Now live on Fireworks and Together as well! All inference endpoints available below:
Fireworks: https://t.co/ynpk146es2
Together: https://t.co/C8d48YBPkM
GMI Cloud: https://t.co/aGiqARWjYh
OpenRouter: https://t.co/Hq7JbJgDun
Thank you for your kind words!
Yes, our $32M R&D cost fully encompasses our pretraining ladder development, data mixing, evals, debugging, synthetic data generation, posttraining recipe development, and the final hero pre, mid, and posttraining run!
> we developed and trained Ripple-65B Preview for only $32M, which is one-tenth the cost of the previous open-weight SOTA on agentic coding¹
this is like the avengers of open model SOTA
¹ "Note that $32M is our full R&D cost starting from scratch, including pretraining ladder development, data mixing, evals, debugging, synthetic data generation, posttraining recipe development, and the final hero pretraining and posttraining run."
Congrats to @RicursiveAI on Ripple-65B Preview, their first open model 🎉
It was trained on NVIDIA B300 GPUs & sharpened with open NVIDIA Nemotron post-training datasets.
Download the NVFP4 checkpoint from Hugging Face and run locally on DGX Spark 👉 https://t.co/MyEPwPTKIt